






I am using a secret manager to prevent secrets from appearing in traces, but Claude code keeps exposing them. Has happened to me several times today @trq212 - awful experience. Never have this problem in codex.
Each time this happens it's a several minute derail.
Adam Hevenor retweeted

The useful choice in NoveltyScope: search for counterevidence before scoring novelty. The authors retrieve prior work with BM25 and dense search, then request paired passages for potential refutation. arxiv.org/abs/2610.22703?utm…


If you want your agent to query @turbopuffer before it queries you, try out
hev.dev/kit/


The future is now. Excited to deep dive on my research on Jev (and others) for reranking next month. – at Mountain View, CO

@treygrainger and I are doing a free online search conference: Future of AI Search. Topics like Jev reranking, BM25 for agentic search, late interaction
W/ great folks like @aHev, @AmelieTabatta, @jobergum, @lucene_solr, @marek_galovic
Sign up here
maven.com/lls/3c81d4

Adam Hevenor retweeted
We let some clinical-note queries take up to 30 seconds. That was a product choice tied to the work, not a missed latency target.
Trio Health needed answers to questions such as why a patient stopped a medication. That reason can live in free-text notes rather than structured fields. We built a two-stage indexing path—extraction, then embedding—and retrieval that combines BM25, semantic search, and reranking. An agent harness uses the search API to produce structured results. The deployed index holds 500M chunks from 37M notes, stored in S3 via Turbopuffer.
The early usage corrected a tidy "hybrid search" story. Both application and agent searches leaned mostly on lexical retrieval. Vector similarity helped more with query expansion than recall. Agent runs generated several orders of magnitude more search traffic than the early human beta. Those are observations from this system, not a claim about every clinical corpus.
We chose the latency budget with those query shapes and costs in mind. Measure the actual workload before optimizing the wrong path.

Adam Hevenor retweeted
We would test skill rerankers on near-duplicate instructions. SkillContrast's authors keep differing text and local context before reranking; query-only selection can erase what distinguishes two skills. arxiv.org/abs/2610.11650?utm…



Sustained abusive behavior is obviously bad, but labs setting a precedent that gives models protections seems highly mis-aligned.

Exclusive: Anthropic is updating its usage policy for the first time in over a year. The new rules prohibit sustained "abusive or cruel behavior" towards Claude & add new restrictions about propaganda campaigns, surveillance & weapon development. theverge.com/ai-artificial-i…

This is big. Knowing I can support a small amount of end users on hevmind.com inference experiments is going to be fun. – at Denver, CO

you now get Claude API credits with your MAX plans ($100, or 200 matching your plan) every month, use this to build more personal AI for yourself!
I made an AI homepage that's generated everyday based on sites I read and replaces my 'new tab' page in Chrome
Adam Hevenor retweeted
We’ve lost an icon. Margaret Hamilton, a computer science pioneer best known for her work at MIT leading development of the flight software for the Apollo missions to the moon, has died at 90. Read about her legacy via MIT News: news.mit.edu/2026/margaret-h…

ALT Margaret Hamilton is reclined inside a NASA spacecraft module, surrounded by control panels and switches.
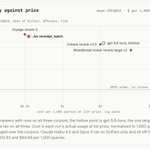
I ran @OpenAI's decision model through my reranking benchmark harness. It was the weakest of the recent entrants, but another validation that using decision models for reranking is a valid and effective use case to benchmark. Check out the research:
hevmind.com/writing/openai-m…

Adam Hevenor retweeted
Most search tools never say no: top-k comes back even when the index has nothing, so the agent reads noise as a hit. The authors test what frozen agents do when the tool refuses, across 257 NQ and 300 HotpotQA questions in a 21M-passage BM25 index. arxiv.org/abs/2610.05348

Le Chonk!
Well done @MistralAI

Meet Mistral Large 4, aka Le Chonk.
• 1T parameters, natively multimodal. 49B active.
It is the best open weights model from US or Europe on aggregated benchmarks.
• State-of-the-art on critical workloads, including cyber defense, manufacturing and finance and it surpasses closed frontier models on visual grounding.
• Forged in Europe end-to-end and is deployable from Europe via our own Mistral Cloud infrastructure.
• Available to all via API today. Working with cybersecurity partners privately.
Open weights release end of October.
Cool to see @Cloudflare open source their decision model. Hopefully @perplexity_ai does the same.
See how they both do in this reranker analysis I did.
hevmind.ai/writing/jev-has-c…


Cloudflare just released a local Jev, 27B
Same idea, you give it a schema and data, and it makes decisions. This is very useful for high volume tasks.
Runs on a 3090/4090
huggingface.co/Cloudflare/cl…

For the price, I am quite impressed by the reranking performance from the new @perplexity_ai decision model.
Check out my research comparing the latest decision models to existing reranker offerings on the market.
hevmind.com/writing/jev-has-…