
GTM Lead @ Mundo AI (YC W25) Building the data layer for perceptual intelligence! | views are my own
Vancouver, British Columbia
Joined April 2019
- Tweets354
- Following647
- Followers157
- Likes1.9K




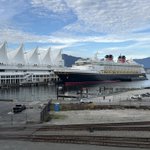
330+ notes on notesforbelal.site as of this morning!! I love that there are notes from all across the world from Japan to the UK to Brazil and North America 💙🤍
1
1
67
I made a site where you can write Belal Halbouni a note of encouragement, and every note fills a seat in a 3D BC Place 💙
The goal is to fill out all 54,000 seats so on hard days he can open it and scroll through a whole stadium worth of notes of strength and encouragement :) #VWFC @WhitecapsFC @MLS
notesforbelal.site
really love this isometric city trend going on at the moment. came across it for the first time a few months ago… wonder how much it costs to get a city online
1
1
208
been thinking a lot lately about cascaded voice systems vs native audio voice models that take audio in as well as output it and which will be more prevalent in the future…
cascaded models make sense when you look at them through the lens of where we started - they’re relatively easy to stitch together via different components like STT, LLM, and TTS and allow us to pick and choose the best component as each component improves. They’re also really beneficial for auditing text at every point in the chained pipeline which is great for compliance reasons.
However, my main concern with cascaded systems is the fact that they throw away at least half of what makes speech so important - all the paralinguistic context such as tone, prosody, emotion, etc… for me, personally, how something is said can sometimes be more important than what was actually said and I think we’ll want to build, and interact with, systems that capture both of those things in the future. If what we care about, as a society, is naturalness and AI systems that can steer their expressiveness to match your current state, then I can’t see us using voice models that lose the ‘how’ in the process.
Having said this, as with everything, it will also depend on the use case and context - task-oriented use cases will probably care more about what was said as opposed to the how and whether or not the task was completed whereas other use cases will most definitely want to understand how something was expressed in order to respond with the right tone and prosody.
1
1
167
oooo was there a claude desktop update? looks cleeeeean @alicelovescake1 :) i like it!
1
1
120


another awesome event last night put on by @DeepgramAI - had a blast talking voice and speech with everyone there. we’re so early!


1
6
286
awesome day full of learnings and meeting new folks - thx to @GoogleDeepMind, @kaggle, and @zapier for putting on a really well run inaugural event :)


4
20
667
the A220 is a lovely aircraft to fly on, especially for tall folks - the complimentary wifi onboard was awesome too @AirCanada!
81
will be my first time on an A220 this week - looking forward to seeing how it compares to the 737
69
I let one of my non-tech friends listen to this conversation and they failed to identify Dessa as the agent… pretty crazy stuff tbh

We made the first AI model you can have a realistic conversation with that was trained entirely on speech!
Dessa is a full-duplex speech-to-speech model that you can run on consumer GPUs.
This is a GPT3 moment for speech.
55
Pumped to be in SF again next week. If you’re working on speech, audio models, conversational data, or evals, I’d be keen to grab a coffee while I’m in town. Shoot me a DM :)
42
I had, arguably, too much fun last night playing around with gpt live 1.1 - my new fav thing to do is have Miko or Sonna speak English with a German accent. Dare I say I prefer that over regular English haha

1
5
115
it's actually pretty crazy how early we are with AI - i think it's important to realize how most of us live in this tech bubble where all of our peers and colleagues are up to date with the latest releases and technology but thanksgiving dinner conversations this weekend with friends and family made me realize that the average person today is still very much removed from AI and personal agents.
first company to really capture this part of the market is going to win big.
3
119
