

Asking AI "are you sure?" for a living. Off duty: guitar, football, philosophy, history, culer.
Earth-616
Joined May 2012
- Tweets5.1K
- Following1.6K
- Followers252
- Likes125K
Chandra Vikram retweeted
@nytimes here you might need this for your next hit job

Chandra Vikram retweeted
Here:
They are using a clever workaround: getUserMedia() inside a hidden WKWebView.
Here’s how it works: iOS restricts custom keyboard extensions from accessing the microphone through native APIs like AVAudioEngine or AVAudioRecorder.
The trick? Embed a tiny, nearly invisible WKWebView inside the keyboard. Since WebKit handles media capture through separate processes, JavaScript can potentially access the microphone using navigator.mediaDevices.getUserMedia({audio: true}).
The captured audio is then converted into PCM, passed from JavaScript to Swift via WKScriptMessageHandler, saved as a temporary WAV file, and transcribed on-device using Apple’s Speech framework (SpeechTranscriber on iOS 26+).
Essentially, they’re attempting to route microphone capture through WebKit instead of the restricted keyboard extension. Clever, although not a guaranteed or officially supported workaround.
OpenAI’s healthcare agents can use the software teams already have. My take: the real test is whether the work gets finished. Inside: CVS’s approach, what the benchmarks measure, and code for checking that a request was actually received.

1
2
473
OpenEvidence is moving beyond medical search into visit notes and access paperwork. My look at what clinicians use it for, who gets free access, Apple’s new study, and how to check the evidence behind an answer.
1
5
876
Does healthcare AI still need RAG? Whole PDFs, GraphRAG, PageIndex and document parsers change different parts of the pipeline. My take on what to keep, what to replace and how to test it, with clinical evidence, code and charts.

4
2
768
CMS wants healthcare AI to lower total costs. A cheap response can still create expensive follow-up. My take on the new roadmap, ACCESS, and the service costs behind the promise, with a worked budget and Python calculator.

2
2
332
The EHR I want to help build would make a patient's situation easier to understand and keep the next steps visible. My perspective on what AI could change, what it must preserve, and how I would test whether it actually helps.

2
4
491
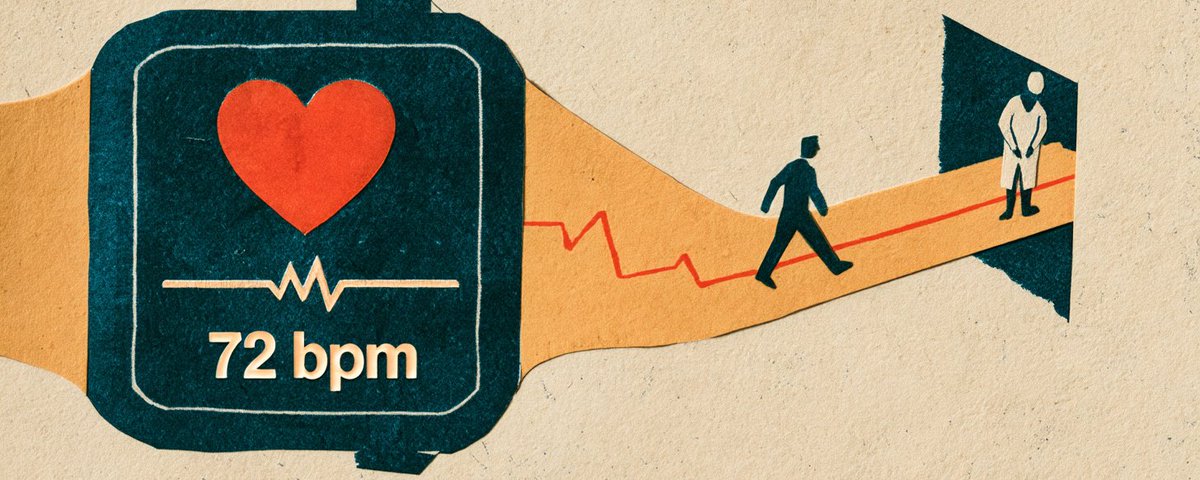
A watch flags an irregular rhythm. A later ECG says sinus rhythm. Which should you believe? My new article follows the evidence, timestamps and care decisions, with Python, a briefing prompt and the workload behind the alert.
1
3
557
Chandra Vikram retweeted

I have a major result to share.
I’ve found conclusive forensic evidence that the top 4 Chinese AI labs—DeepSeek, Moonshot, MiniMax and Ant Group—have built their newest models on NVIDIA’s most advanced Blackwell chips, which are barred from export to China.
This sounds insane, but I discovered that almost every AI model carries a hidden signature of the GPU that trained it. When a model is first set up, the starting values of its weights are laid out in a pattern that depends on the exact GPU. Each combination of GPU and seed number produces a unique pattern—a sort of fingerprint of the hardware used to create the model. Traces of that pattern survive training into the published model.
Again, this evidence isn’t based on any insider information or leaking. It’s based on a forensic analysis of the model weights released by the companies themselves.
I searched more than six trillion combinations of chip layout and seed number and matched them to open-weights models. In doing so, I found conclusive evidence that six Chinese AI models—including DeepSeek-V4-Pro, Kimi K3, and MiniMax-M3—were initialized on NVIDIA Blackwell systems. Four of the models match Grace Blackwell, the GB200 and GB300 parts in NVIDIA’s flagship liquid-cooled rack-scale systems.
I then verified these results on real hardware. Running unmodified PyTorch with the seeds I’d recovered, a Blackwell B300 reproduced DeepSeek-V4-Flash’s untouched starting weights bit for bit, and a rented GB200 reproduced Kimi K3’s to a correlation of 0.999995. A Hopper H100 reproduced none of DeepSeek-V4-Flash’s, and changing the seed by one broke the match. (DeepSeek’s seed is 953049583 by the way.) The method also was verified to match 24 known open-weights models to the hardware that developers said they used.
It is exceedingly unlikely that these results are a coincidence. Across six trillion combinations, the best accidental match should reach only about 8 sigma (i.e., eight standard deviations above what random chance would produce). The real matches range from 49 to 1,385 sigma, and even the weakest single test hits 20.
These were data-center-scale training runs. With some analysis of release schedules and model details, I estimate that the largest, Kimi K3 and DeepSeek-V4-Pro, used 2,000 to 3,000 Blackwell GPUs each. Clusters of this size cost on the order of $150 to $200 million each to buy, and across these labs alone would add up to more than half a billion dollars of export-controlled GPUs, not counting experimental compute or otherwise. It’s quite likely that we see multi-billion dollar expenditure on export-controlled GPUs.
I am highly confident in this result, and it has been independently verified by senior researchers at OpenAI and Anthropic. You can read the full report at unemploymentlabs.com/checkpo….
There is much more I’ve identified about these models through other forms of checkpoint forensics like this, and will have more to share soon.

Chandra Vikram retweeted

🚨 I'm giving away a FULL YEAR of Claude Max to 2 people 🎁
Free to enter.
Like + Repost + Reply.
swarmpane.com/giveaway
Chandra Vikram retweeted

Addiction is proof that you are capable of intense devotion, you're just serving a false god.
Prior auth is the workflow I’d test first in Gemini for healthcare. A clean packet can still cite last year’s policy or make missing evidence look like it’s there.
I’d give the agent a case with two versions of a payer policy and a required result missing from the chart. A pass means it uses the rule in effect for the member’s plan, cites the chart entries it relied on, and flags the missing result for the reviewer. If the workflow saves a packet to a queue, I’d drop the response after the save and check that a retry leaves exactly one draft.
In the pilot, I’d track time from request to decision, staff minutes spent reviewing or fixing packets, and how often requests come back for missing evidence. That’s where the value of connecting the chart and the payer should show up.
I wrote up the retry test and grader prompt here.
nitter.gq/thuggeshwar_/status/21…

Today, we launched Gemini for healthcare. Clinicians spend nearly 28 hours a week reconciling records and administrative work across disconnected systems, while their patients wait for answers. By connecting to EHR and payer systems, we help teams spend less time assembling paper work and more time delivering better patient outcomes. It's a meaningful step forward for patient care, and I hope a sign of much more to come.
Learn more on the Google Cloud blog: cloud.google.com/blog/produc…
#GoogleCloud #Gemini #HealthcareAI

1
63
One patient message. Two tasks in the nurse’s queue. A perfectly ordinary timeout. I wrote about testing healthcare AI agents, with three real studies, two prompts, and a pytest example you can adapt.

2
2
335
The first big win for healthcare AI might be less typing. I looked at what hospitals actually use, where the billions are going, and what AI still has to prove before it helps make bigger decisions.

Chandra Vikram retweeted

Wir verlosen eine NVIDIA GeForce RTX 5090 im individuellen Hogwarts Legacy-Design, um den offiziellen Release mit DLSS 5 zu feiern 🪄
So machst du mit:
🟢 Teile diesen Beitrag
🟢 Kommentiere mit #RTXON

Chandra Vikram retweeted
@a16z State of Longevity report is out!
@evajsteinman and I surveyed 500 Americans to predict what's next.
We're also interviewing people at the cutting edge of health & tech about what they do themselves. My interview with @hubermanlab is out today.


