

founder @heurist_ai building agents for finance
New York
Joined May 2013
- Tweets4.6K
- Following3.5K
- Followers7.1K
- Likes22.1K




Datacenters can be positive sum

1/ Texas is now arguing over whether it wants AI data centers at all.
So I looked at a county that already has a giant one: Dickens County, pop. ~1,700, home to $GLXY Helios campus.
What does the local public record say? A sourced thread.
JW (jay,dub) retweeted

I don't know how much lower we go in AI
There are a lot of reasons to be skeptical of overbuild and cyclicality
But let's keep in mind...
- agentic adoption really started in Q3 and is an order of magnitude more token demand than an individual person (always on, stackable)
- frontier cyber AI only recently became public an is now a permanent tax on enterprises and nations (and is escalatory in nature no ceiling)
- the rest of the world, including China, is behind the US in their buildout and in penetration
- speaking of penetration, Anthropic's S-1 rounded to 0.1% of enterprise spend on AI - that's a low amount for intelligence as a service!
- robotics & autonomy are still sub-scale but real
Buybacks in q4 going to lead a strong bounce take my word

Lam Research $LRCX announced a $25 billion stock buyback hours after falling 16% on its worst day in a year.
Anthropic has a new agent scaffold besides Claude Code, reported by @METR_Evals
"People can spam 10 ideas at the scaffold for autonomous experiments" - said a researcher
My guess is that the internal agent scaffold is the main driver for RSI


JW (jay,dub) retweeted
If you think the AI trade is collapsing after today, and data centers delivery next year will be pretty much stalled, you would think that 10 year should be substantially lower than 4.9%, cuz we’d be talking about sub-1% GDP growth, possibly even talking about the R-word (which i am specifically banned from saying).
But if not…. Then what world are we in?

JW (jay,dub) retweeted

some people downplay this, some overhype it
but i'm excited for one reason: this work is verifiable
and we've seen what happens to verifiable domains
(hint: a few years ago, models struggled with 8th grade math)

We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: rikiyat.github.io/blog/weigh…

Readers added context they thought people might want to know
LLM was given weights explicitly as text in prompt and used code/forward passes (per authors' logs) to ablate Qwen looping direction, a known thinking-mode issue per model card. Primarily fixed repetition in that mode, not general 'natively' improving weights/math.
rikiyat.github.io/blog/weight-sp…
github.com/RikiyaT/lm_und…
huggingface.co/Qwen/Qwen3.5-0…
huggingface.co/RikiyaT/Qwen3.…
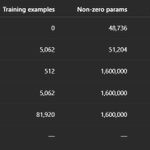
Let GPT 6 Astra hand-write weights of a 1.6m param model to predict bitcoin price
I just asked for the weights. It beats the baseline without training

JW (jay,dub) retweeted

are you serious right now?
all our stuff is open source and fast. that's why the devs use them and love them, and people cant rmb how it was to dev on ethereum before we build these tools. you need the devtools to build anything. the devtools gotta be fast else your devs churn. 101. basics!
promoting the usage of a slow, painfully dumb setup e.g a miniature quantized qwen in your qubes over tor using kohaku is not making the world a better place or promoting a helpful ideology, it's making you sound like a fucking hipster, and worse you're baiting other people with potential in dumb hipster philosophies.
don't you like the halloween costume?


JW (jay,dub) retweeted

Tired of these DPRK hacks. So I built the ultimate defense.
DPRKaptcha[.]com
Simple questions with existential outcomes (for them).
Live now to protect the internet from North Korea.


JW (jay,dub) retweeted

For anyone questioning whether this post is overhyped, I think they are actually *underselling* the approach.
We did similar experiments and found that Claude models can write entire, functional neural net weights from scratch! csinva.io/weight-space-progr…
We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: rikiyat.github.io/blog/weigh…
Readers added context they thought people might want to know
LLM was given weights explicitly as text in prompt and used code/forward passes (per authors' logs) to ablate Qwen looping direction, a known thinking-mode issue per model card. Primarily fixed repetition in that mode, not general 'natively' improving weights/math.
rikiyat.github.io/blog/weight-sp…
github.com/RikiyaT/lm_und…
huggingface.co/Qwen/Qwen3.5-0…
huggingface.co/RikiyaT/Qwen3.…
Most trading apps are built for attention-grabbing and make you over-trade.
I vibe-coded my own terminal with the right amount of information. Custom layouts, watchlists, minimal set of indicators (MA, Fib, sigma levels) that I care about.
Bye Tradingview!


Combining with Claude + @heurist_ai workbench, I can now analyze every names of my book, let AI create a trading plan and show it up in the terminal.
nitter.gq/heurist_ai/status/2113…

frontier model capabilities blowing my mind
We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: rikiyat.github.io/blog/weigh…
Readers added context they thought people might want to know
LLM was given weights explicitly as text in prompt and used code/forward passes (per authors' logs) to ablate Qwen looping direction, a known thinking-mode issue per model card. Primarily fixed repetition in that mode, not general 'natively' improving weights/math.
rikiyat.github.io/blog/weight-sp…
github.com/RikiyaT/lm_und…
huggingface.co/Qwen/Qwen3.5-0…
huggingface.co/RikiyaT/Qwen3.…