
PhD student @cornell_tech @Cornell_CS | Research Intern: @GoogleDeepMind Past: @AdobeResearch
Joined July 2024
- Tweets80
- Following228
- Followers212
- Likes9.1K

Chao Feng retweeted

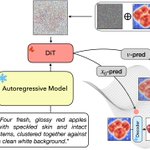
We build a hierarchy in semantic space: text → semantic → pixel. AR learns what to draw; diffusion learns how to draw it.
Like LLMs: pretrain for knowledge, post-train for behavior.
Know, then Draw: A New Learning Paradigm for Visual Generation 🧵
arxiv.org/abs/2610.37626

Chao Feng retweeted
I've long believed hierarchical representations are one of the most promising paths forward for vision problem. QuadTok is our first step: a tokenizer for adaptive image representation and generation.
Paper: arxiv.org/abs/2610.10497
Code: github.com/myc634/QuadTok
Details below.

ALT QuadTok overview. A dog image is reconstructed with 64 to 192 tokens, with orange overlays marking finer tokens. Below are generated images and a supplied quadtree used to guide the spatial layout of a generated bird image.
Chao Feng retweeted

Excited to share our #NeurIPS2026 E&D 🏆 Spotlight!
We all agree that memory is essential for modeling a persistent 4D world.
But: 🙋 Can 4D Foundation Models Remember?
Introducing 🔥 PersistBench: a benchmark for testing visual memory in camera-controllable video models / 4D reconstruction models / video-to-360° models.
One key challenge in evaluating visual memory is obtaining real-world ground truth for what happens to an object after it leaves the camera’s view.
In PersistBench, we introduce a simple way to sidestep this challenge. 🤫
🌐 Project Page: guangzhaohe.com/persistbench…
🏆 Leaderboard: huggingface.co/spaces/therea…
🐙 GitHub: github.com/guangzhaohe/Persi…
🤗 Dataset: huggingface.co/datasets/ther…
See how well your models do and submit to our leaderboard today!
🧵 [1/n]
Chao Feng retweeted
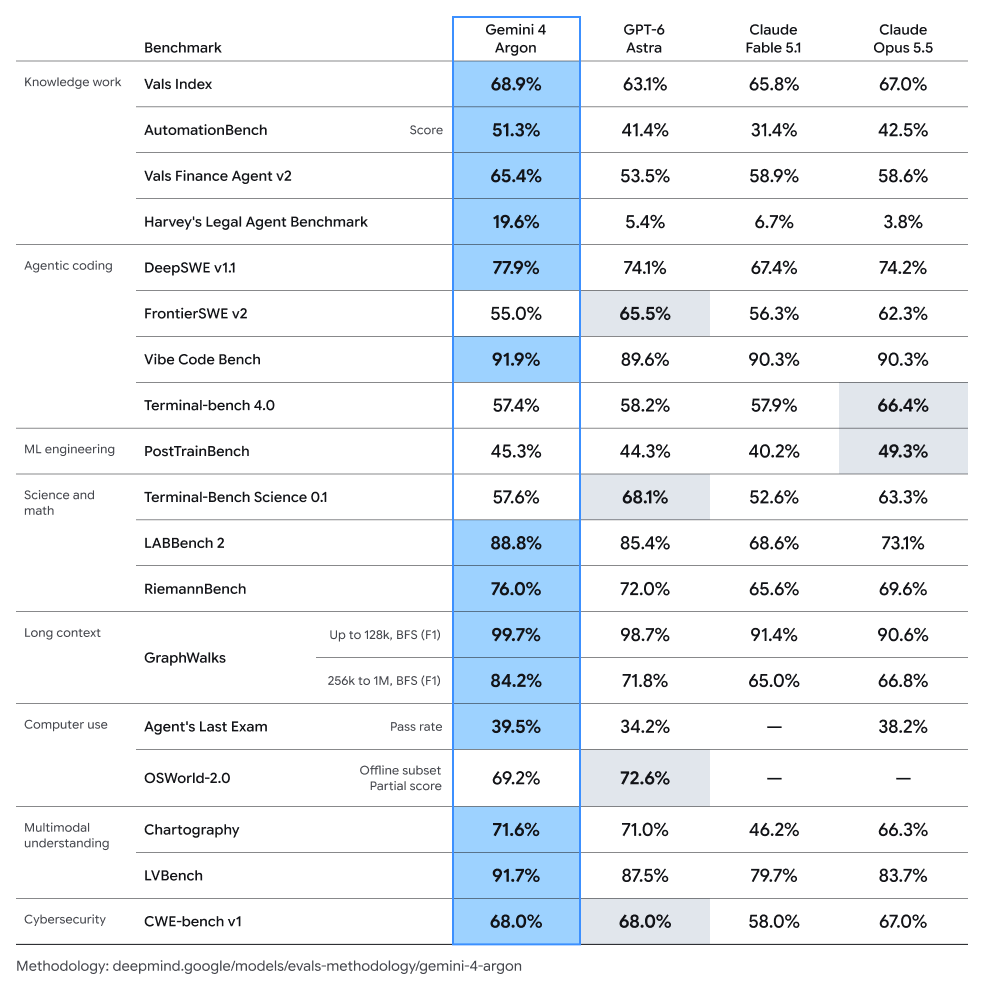
Introducing Gemini 4 Argon – our new frontier model.
It’s built for complex workflows across coding, enterprise knowledge work, and cybersecurity defense – rolling out today to a set of trusted testers through our Fairwind Program.
Late to the party, but happy to introduce our #ECCV2026 paper: On the Diffusibility of High-Dimensional Latents.
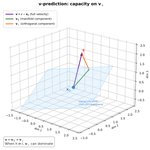
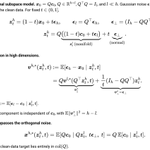
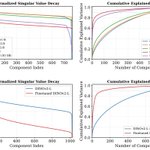
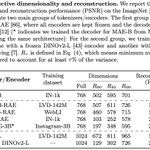
We found that finetuning representation autoencoders (RAEs) for reconstruction can hurt diffusibility under standard velocity prediction in flow matching. Why?(1/10)

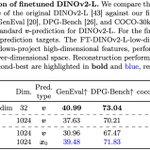
For both finetuned DINOv2-L and MAE-RAE, switching from v- to x0-prediction improves GenEval, DPG-Bench, and COCO-30k FID. Finetuned DINOv2-L with x0-prediction also outperforms original DINOv2-L with v-prediction on all three benchmarks. (9/10)


This is a great collaboration with Adobe. Thanks to all my amazing collaborators @zhiyangx11 @bowei_chen_19 Yuanjun Xiong @XiyaoWang10 @JuiHsienWang1 @rzhang88 Zhe Lin @andrewhowens @leexiaoju
Paper: arxiv.org/pdf/2609.28473
Project page: cfeng16.github.io/on_the_dif…
(10/10)
Chao Feng retweeted

We now release the technical report for TabFM: arxiv.org/abs/2609.37959. Together, we introduce TabFM-Auto: an LLM agent working on feature engineering on top of a frozen TabFM. You can find more details at arxiv.org/abs/2609.37989 and explore features LLMs found at deqingfu.github.io/tabfm-aut….


Introducing TabFM, a foundation model designed specifically for tabular data classification & regression. This approach allows generation of high-quality predictions on previously unseen tables in a single forward pass.
Learn more and try out the model →goo.gle/4eR7uku

Chao Feng retweeted

This is very close to CPC right?
Sometimes I feel like @avdnoord @yazhe_li & @OriolVinyalsML had it all perfectly worked out in 2018 and it's just taking use 10-20 years to finally understand them

Can we build world models purely in the latent space, without pixel prediction?
We present Contrastive World Models - we train the latent states to maximize mutual information with future observations, without any decoders / pixel reconstruction.
Contrastive World Models enables
⚡ Substantially more robust representations
🤖 More efficient training by removing the pixel decoder entirely
🌍 A general approach with minimal assumptions [1/n]

Chao Feng retweeted

Open-source video generation is now faster than playback without compromising quality.
Introducing Video Delta Net (VDN): hybrid attention for live text-to-video with near-lossless quality.
VDN accelerates Minimax-H3 by 75 - 90 x, generating 14 seconds of 768p video in 11 seconds on 8× NVIDIA B200 GPUs.
Checkpoints + training/inference code + Technical Blog ⬇️
(1/6)
Chao Feng retweeted

Introducing Gemini 3.8 Flash, another jump in Gemini's agentic + coding capabilities, and our 3rd updated Flash model in only 6 weeks...
This model has been a ton of fun to work with, excited to see what you all think!


Chao Feng retweeted

We live in a multimodal world. We see, talk, act, and dream.
Yet most LLMs still start with language pretraining. Why not train them natively with multimodal I/O from scratch?
Because it’s SUPER HARD, adding modalities triggers training instability, design complexity, and often modal competition
So what’s the path forward?
Introducing: Towards Physics of Multimodal Pretraining (junlinhan.github.io/projects…)
We unpack the underlying mechanics of multimodal pretraining across 4 aspects: Knowledge Flow, Modality Synergy, Early Unification, and Recipe.

