

The Sovereign Cloud for AI. Purpose-built for the full AI lifecycle. Any workload. Any scale. Zero compromise.
Joined March 2026
- Tweets73
- Following38
- Followers20
- Likes84




One CloudLogics customer found $40,000 a month in idle compute during their first week using the platform.
CloudLogics surfaced the unused resources automatically, giving the team a much clearer picture of what they were actually using.
#AIInfrastructure #CloudCostManagement
What should managing high-performance AI infrastructure feel like?
Learn more:
cloudlogics.com/
#AIInfrastructure #SovereignCloud #GPUComputing

The hyperscale cloud model was built for a different era of computing.
Learn more:
cloudlogics.com/
#AIInfrastructure #SovereignCloud #GPUComputing #NeoCloud
How should AI infrastructure performance be measured?
See what CloudLogics is built to deliver:
cloudlogics.com/
#AIInfrastructure #GPUComputing #AIInference #HPC


Each CloudLogics Sovereign POD operates as its own autonomous environment, combining dedicated GPU infrastructure, immersion cooling, and a localized OpenStack control plane in one self-contained system.
cloudlogics.com/
#SovereignCloud #PrivateCloud
CloudLogics is built for high-performance inference, delivering 20,000-50,000 billable tokens per second at scale.
The goal is to get more useful work from the infrastructure you already have, not just add more compute.
Learn more: cloudlogics.com/
#AIInfrastructure
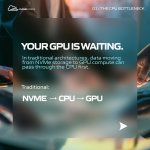
GPUs depend on a steady flow of data to stay productive.
See how CloudLogics approaches AI infrastructure as a complete system:
cloudlogics.com/
#AIInfrastructure #GPUComputing #AIPerformance #AIArchitecture #HPC


Traditional air cooling has to remove increasingly large amounts of heat as GPU density rises. CloudLogics takes a different approach, immersing the hardware in cooling fluid so heat can be removed directly from the system.
#AIInfrastructure #GPUComputing #LiquidCooling #HPC

CloudLogics' current cluster is built to run 90+ AI models simultaneously through GPU instance splitting.
See what we’re built to handle:
cloudlogics.com/
#AIInfrastructure #AIInference #GPUComputing #EnterpriseAI #HPC
You can keep adding faster GPUs, but if the data path can’t keep up, you’re just putting more expensive hardware behind the same bottleneck.
#AIInfrastructure #GPUComputing #HPC #AIArchitecture


Infrastructure teams have enough to monitor without juggling multiple tools to understand what’s happening across their environment.
Bringing monitoring into one place gives teams a clearer view of infrastructure health, performance, and operations.
#ITOperations #AI

Turns out, keeping your cool is an infrastructure strategy. 🧊
#AIInfrastructure #LiquidCooling #HPC #DataCenters #SustainableInfrastructure


What if low GPU utilization isn't actually a GPU problem?
Read more: loom.ly/keLHXmM
#AIInfrastructure #GPUComputing #Latency #DataInfrastructure

GPU utilization and network latency are worth looking at together. If utilization drops as latency rises, the constraint may not be the silicon.
Before adding more GPUs, ask a question: What are they waiting for?
Read more: jdubyou.substack.com/p/the-m…
#GPUComputing #Latency
Why put a CPU in the middle when data needs to get to the GPU?
#AIInfrastructure #HPC #GPUComputing #NVMe
What happens when an AI workload needs to scale beyond a single data center?
Adding GPUs is only part of the answer. Those GPUs still need to communicate with storage, data, and each other.
#AIInfrastructure #GPUInfrastructure #CloudComputing #HighPerformanceComputing

What is the real cost of waiting two days for infrastructure?
For engineering teams, every manual ticket, approval, and handoff adds time between an idea and the infrastructure needed to execute it. Self-service changes that equation.
#CloudInfrastructure #PlatformEngineering

Containers can still rely on a cloud provider’s storage, identity, networking, and other proprietary services. The application may be portable while the environment around it remains tied to one platform.
Read more:
jdubyou.substack.com/p/the-n…
#CloudComputing
