ai+ui engineering / creative coder / principal swe @splunk
Joined January 2013
- Tweets531
- Following442
- Followers2.4K
- Likes18.2K


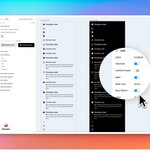

In @ChromeDevTools holding SHIFT while moving mouse over resources in network panel shows you which asset caused to load another asset.
· Green: top initiator
· Light green: direct initiator
· Red: child resource (current resource caused to load this)
#javascript #CodeNewbie
Mike Skowronek retweeted

LLM Knowledge Bases
Something I'm finding very useful recently: using LLMs to build personal knowledge bases for various topics of research interest. In this way, a large fraction of my recent token throughput is going less into manipulating code, and more into manipulating knowledge (stored as markdown and images). The latest LLMs are quite good at it. So:
Data ingest:
I index source documents (articles, papers, repos, datasets, images, etc.) into a raw/ directory, then I use an LLM to incrementally "compile" a wiki, which is just a collection of .md files in a directory structure. The wiki includes summaries of all the data in raw/, backlinks, and then it categorizes data into concepts, writes articles for them, and links them all. To convert web articles into .md files I like to use the Obsidian Web Clipper extension, and then I also use a hotkey to download all the related images to local so that my LLM can easily reference them.
IDE:
I use Obsidian as the IDE "frontend" where I can view the raw data, the the compiled wiki, and the derived visualizations. Important to note that the LLM writes and maintains all of the data of the wiki, I rarely touch it directly. I've played with a few Obsidian plugins to render and view data in other ways (e.g. Marp for slides).
Q&A:
Where things get interesting is that once your wiki is big enough (e.g. mine on some recent research is ~100 articles and ~400K words), you can ask your LLM agent all kinds of complex questions against the wiki, and it will go off, research the answers, etc. I thought I had to reach for fancy RAG, but the LLM has been pretty good about auto-maintaining index files and brief summaries of all the documents and it reads all the important related data fairly easily at this ~small scale.
Output:
Instead of getting answers in text/terminal, I like to have it render markdown files for me, or slide shows (Marp format), or matplotlib images, all of which I then view again in Obsidian. You can imagine many other visual output formats depending on the query. Often, I end up "filing" the outputs back into the wiki to enhance it for further queries. So my own explorations and queries always "add up" in the knowledge base.
Linting:
I've run some LLM "health checks" over the wiki to e.g. find inconsistent data, impute missing data (with web searchers), find interesting connections for new article candidates, etc., to incrementally clean up the wiki and enhance its overall data integrity. The LLMs are quite good at suggesting further questions to ask and look into.
Extra tools:
I find myself developing additional tools to process the data, e.g. I vibe coded a small and naive search engine over the wiki, which I both use directly (in a web ui), but more often I want to hand it off to an LLM via CLI as a tool for larger queries.
Further explorations:
As the repo grows, the natural desire is to also think about synthetic data generation + finetuning to have your LLM "know" the data in its weights instead of just context windows.
TLDR: raw data from a given number of sources is collected, then compiled by an LLM into a .md wiki, then operated on by various CLIs by the LLM to do Q&A and to incrementally enhance the wiki, and all of it viewable in Obsidian. You rarely ever write or edit the wiki manually, it's the domain of the LLM. I think there is room here for an incredible new product instead of a hacky collection of scripts.
Mike Skowronek retweeted

🚨SOMEONE REINVENTED HOW TEXT RENDERS ON THE WEB AND ITS ABSOLUTELY INSANE.
the goated dev behind react, reasonML, and midjourney’s frontend, just dropped Pretext. a tiny typescript library that measures and lays out text 500x faster than the DOM.
he trained models against real browser rendering for weeks until the output matched safari, chrome, and firefox exactly.
the demos are insane!! hundreds of thousands of text boxes at 120fps. magazine layouts and chat bubbles that actually wrap right.
engineers from Vercel, Remix, Figma, and shadcn all cosigned. this is the kind of open source that makes you want to be a better dev.
here are some cool demos in the past 24hrs👇

My dear front-end developers (and anyone who’s interested in the future of interfaces):
I have crawled through depths of hell to bring you, for the foreseeable years, one of the more important foundational pieces of UI engineering (if not in implementation then certainly at least in concept):
Fast, accurate and comprehensive userland text measurement algorithm in pure TypeScript, usable for laying out entire web pages without CSS, bypassing DOM measurements and reflow

I miss times when I was developing in Delphi 7. Superior experience when it comes to mix of visual design and code. Everything has got its place and was easily hackable. Components had their design and runtime version so developers were even able to deliver specific experience for devs.


To nie jest celem badania. Ujęto to, by nie zakładać intuicyjnie, że zawody znikną, ale zmienią się w pewnym stopniu. Trudno przewidzieć, w jakim. Szanuję Pana, ale tytuł zaprzecza prośbie w badaniach.
Mike Skowronek retweeted

Shopify just launched a racing game built in threejs and React (R3F).
No physics libraries. No raycasts.
Not vibe coded. But all vibes. ✨
Mike Skowronek retweeted

my son asked me, dad why don't people build UI like this anymore.
slowly i turned to him, and told him the uncomfortable truth.
"we can't, we dont know how to do it."
xitter.cf/NostalgiaFolder/status…