
Ing. Informático de la PUCP.
Lima, Peru
Joined May 2009
- Tweets2.3K
- Following371
- Followers218
- Likes80

David Balbin retweeted

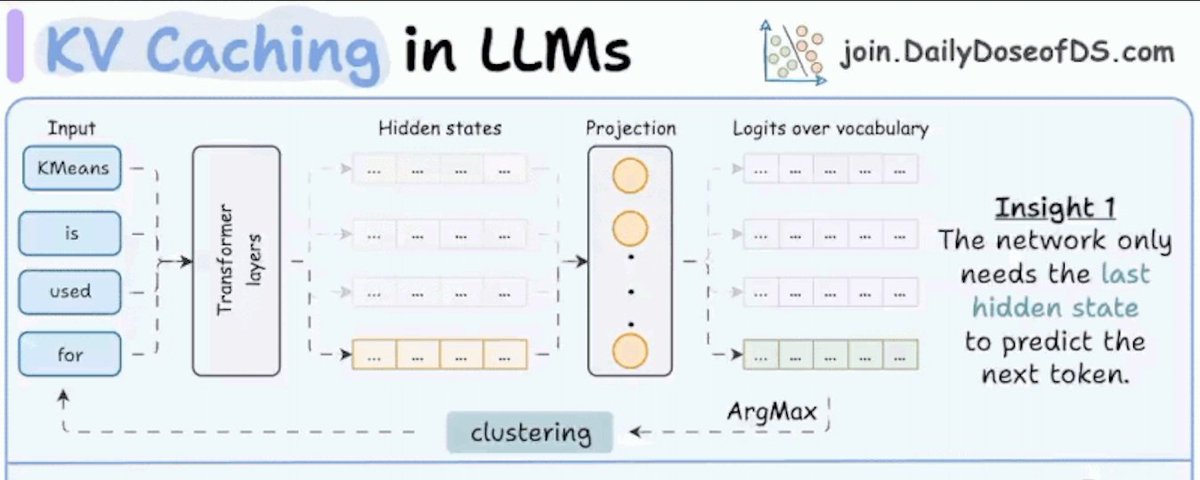
Brilliant paper by NVIDIA.
they found a way to make KV cache transferable between models.
the target model skips prefill entirely, and the conversion runs 2.7 to 25x faster than processing the context again.
let's understand why this is so important today.
LLM APIs are stateless, so every turn sends the entire conversation back to the model. the model reads it again before generating a new token, and all of it is billed as input.
prompt caching lets providers hold the KV cache for a stable prefix and bill cache hits at roughly 10% of the base input rate because that compute was already done.
this 90% reduction is one of the biggest levers in LLM serving.
but the cache only works on the model that produced it. since keys and values depend on that model's weights, another model cannot directly reuse them.
this becomes a problem with LLM routing.
if traffic moves to another model for cost or capability reasons, the accumulated KV cache becomes invalid.
the entire context must be processed again and billed at full rate.
NVIDIA's recent paper treats this as a representation problem.
prefill's main output is the KV cache, so transferring it means converting one model's cache into the representation another model expects.
they first checked whether this conversion had enough structure to exploit.
for Qwen3 14B → 32B, a linear regression from a single source layer reconstructed 56% of the variance in the target model's keys.
because models can have different layer counts, there is no natural one-to-one layer mapping.
so, for every target layer, they rank the source layers by predictive power and use the top eight together.
that pushes reconstruction to 79%.
the mapper has three parts:
> each target layer and head gets its own linear map, solved in closed form instead of with gradient descent.
> cross-layer selection chooses the source layers that best predict each target layer. their ablation shows this contributes the most.
> RoPE adds a position-dependent rotation to keys. they remove it, fit the mapping in position-free space, then apply the target model's rotation again at inference.
across six model pairs from Qwen3, Llama 3.1, and Ministral 3, four retain 73 to 98% of the receiving model's standalone accuracy.
conversion is also 3 to 25x faster than processing the context again.
prior cross-model KV reuse methods either train a neural adapter for every pair or require architecturally identical models.
this approach is closed-form and training-free, but there are still important limitations.
every tested pair belongs to the same model family, such as Qwen → Qwen or Llama → Llama.
cross-family transfer is still future work.
the tested pairs also share KV head count and per-head dimension. mismatched configurations remain untested.
and the work currently covers dense full-attention models only, not sliding-window or attention-recurrent hybrids.
link to the paper: arxiv.org/abs/2608.03893
i wrote a first-principles breakdown of how KV caching works
the article is quoted below.

David Balbin retweeted

How do you keep Claude working until the job is done? Claude Code helps with this in a few ways, including one we shipped recently: /goal.
David Balbin retweeted

NEW POST
Will there be source code in the future? To wrestle with this, we have to understand what code is. Unmesh Joshi sees code as having two distinct but intertwined purposes: instructions to a machine and a conceptual model of the problem domain.
martinfowler.com/articles/wh…

David Balbin retweeted

La regla de oro de todo ingeniero: si tienes que hacer algo aburrido más de dos veces, automatízalo. 🛠️✨
Jules es la máxima automatización para tu flujo de trabajo.
Un agente impulsado por IA que gestiona las tareas mecánicas, las ejecuta en un entorno virtual y te entrega el código listo para integrar. ⚙️
Enfócate en crear; Jules se encarga del resto. 💜🐙
Conócelo aquí: jules.google/
David Balbin retweeted

Google acaba de hacer algo que Claude Design no esperaba.
Y lo hizo gratis, en abierto, para todo el mundo.
Se llama DESIGN.md.
Pero primero hay que hablar de lo que provocó esto.
Anthropic lanzó Claude Design con límites de uso ridículos.
Cerrado. Caro. Controlado.
La herramienta de diseño con IA más potente del momento, pero con la llave en su bolsillo.
Google vio la jugada.
Y respondió de la única forma que duele de verdad:
Abrió el código. Gratis. Para todo el mundo.
Se llama DESIGN.md.
Un estándar abierto que cualquier IA puede leer.
En cualquier herramienta. En cualquier plataforma.
El problema que resuelve es real:
Los agentes de IA no tienen ni idea de tu sistema de diseño.
No saben qué significa tu color primario.
No saben si ese botón es accesible.
No saben para qué sirve cada componente.
Cada vez que usabas IA para diseñar, empezabas de cero.
DESIGN.md lo resuelve con un solo archivo.
Tres cosas concretas que hace:
1️⃣ Tokens de diseño
Tus colores, tipografías y espaciados con descripciones en lenguaje natural.
La IA entiende para qué sirve cada valor, no solo cuál es.
2️⃣ Validación de accesibilidad
El agente comprueba sus decisiones contra las reglas WCAG.
Sin que tú tengas que revisar cada detalle manualmente.
3️⃣ Portabilidad total
Exportas e importas tus reglas de un proyecto a otro.
Un archivo. Cualquier herramienta. Cualquier plataforma.
Incluidas las de Anthropic.
Eso es lo que más duele en ese lado de la mesa.
Anthropic construyó muros.
Google tiró la pared entera.
El repositorio está en GitHub: github.com/google-labs-code/…
Esto es lo que pasa cuando los grandes se pelean.
Nosotros ganamos.

David Balbin retweeted

NVIDIA da acceso gratis por API a modelos de IA.
A DeepSeek V4, MiniMax M2.7, GLM 5.1, Gemma 4...
Perfecto para pruebas de desarrollo.
Puedes usarlo con OpenCode y OpenClaw
Puedes conseguir acceso aquí:
→ build.nvidia.com/models

ALT Captura de la web de NVIDIA Build en la sección “Models”, mostrando un listado de modelos de IA optimizados por NVIDIA con el filtro “Free Endpoint” activado. Se ven 156 modelos disponibles, tarjetas como deepseek-v4-flash, deepseek-v4-pro, glm-5.1 y glm-4.7, además de buscador, filtros por casos de uso y ordenación por “Most Recent”. NVIDIA sacando buffet libre de modelos como quien no quiere la cosa.
David Balbin retweeted

寝てる間も稼ぎ続けるGitHubリポジトリ10選:
1. AutoHedge
AIエージェントが市場分析からトレード実行まで全自動。数分で自分専用の自律型ヘッジファンドが作れる。
github.com/The-Swarm-Corpora…
2. Vibe-Trading
自然言語で取引戦略を指示できる個人用AIトレーディングエージェント。29の専門チームが分析から実行まで動く。
github.com/HKUDS/Vibe-Tradin…
3. Claude Ads
Google・Meta・YouTube・TikTokなど7媒体の広告を250以上の観点でAI監査。広告費のムダを最大35%削減できる。
github.com/AgriciDaniel/clau…
4. Toprank
Search ConsoleとGoogle Adsに直接アクセスし、トラフィック低下の原因を診断して修正案まで出してくれるSEOツール。
github.com/nowork-studio/top…
5. Fincept Terminal
Bloombergのオープンソース代替。37のAIエージェントが市場分析・投資調査を無料で担ってくれる。
github.com/Fincept-Corporati…
6. Agentic Inbox
Cloudflare Workers上で動く自己ホスト型AIメールエージェント。受信→分類→下書き作成まで自動。送信前に確認できる。
github.com/cloudflare/agenti…
7. ClawRouter
41以上のLLMモデルを1ms以下でルーティング。AIのAPI費用を最大92%削減できる。
github.com/BlockRunAI/ClawRo…
8. Camofox Browser
AIエージェント向けのアンチ検出ブラウザ。Webスクレイピングや自動化でブロックされなくなる。
github.com/redf0x1/camofox-b…
9. Open Higgsfield AI
Higgsfield・Krea・Freepik AIなど複数サービスの無料オープンソース代替。200以上のモデルでフィルターなしの画像・動画生成が使える。
github.com/Anil-matcha/Open-…
10. Hyperframes
HTMLを書くだけで動画をレンダリングできるフレームワーク。エージェントとの連携に最適。
github.com/heygen-com/hyperf…
保存して後で使いこなして。


David Balbin retweeted
New in Claude Code: /ultrareview (research preview) runs a fleet of bug-hunting agents in the cloud.
Findings land in the CLI or Desktop automatically. Run it before merging critical changes—auth, data migrations, etc.
Pro and Max users get 3 free reviews through 5/5.
David Balbin retweeted

Esto es increíble, modelos de 96GB serán reducidos al menos a 16GB. Modelos más poderosos se podrán ejecutar en máquinas de consumidor sin pérdida . Se reduce el tamaño DESDE 6 veces!

Introducing TurboQuant: Our new compression algorithm that reduces LLM key-value cache memory by at least 6x and delivers up to 8x speedup, all with zero accuracy loss, redefining AI efficiency. Read the blog to learn how it achieves these results: goo.gle/4bsq2qI
David Balbin retweeted

A simple Clawbot setup made me $6,700 in 3 days.
No coding.
No tech skills.
Just ChatGPT + Laptop + 2 hours daily.
This setup can generate up to $3,000/day if used right.
So I created a step-by-step guide anyone can follow.
Normally $349, But FREE for the next 24 hours.
Want exact guide?
1️⃣ Comment "Claw"
2️⃣ Like + Repost
Follow @Ejaz_bashir1 so, I'll DM you the guide. 📩

David Balbin retweeted

🔴 ¡OPENAI LANZA PRISM!
Un conjunto de herramientas pensadas para facilitar la vida a investigadores a la hora de redactar en LaTeX, buscar bibliografía, verificar información, etc. Todo potenciado por GPT-5.2 (y los futuros modelos que llegarán)
nitter.gq/OpenAI/status/20…
David Balbin retweeted
Problemas con Cloudflare otra vez.
Se cancela trabajar este viernes.

ALT Perro con cara de resignación sentado en una habitación completamente en llamas, sujetando su taza como si nada mientras arriba aparece el logo de Cloudflare, dando vibes de “todo arde pero seguimos sonriendo” aunque claramente no está nada fine.
David Balbin retweeted
¡Acaba de salir React Email 5.0!
La mejor forma de crear correos electrónicos.
✓ ¡Ahora con soporte para modo oscuro!
✓ Compatibilidad con Tailwind 4
✓ 8 nuevos componentes
Previsualización, linter y mucho más:
→ npx create-email@latest
David Balbin retweeted

Azure Fundamentals (AZ-900) (Quick Guide)
✍️Completed this guide (with 6 Days Learning Plan),and sharing it for FREE for just 24 hours!
✅Will share over DM to all requests, Only 179 Slots!
To get it (for FREE):
1. Follow me @TTechFusionist (So that I can DM)
2. Repost this post!
3. Reply "Azure"
Follow me so I will dm 💯

David Balbin retweeted
ASP .NET Rate Limiting middleware examples 🔥
#dotnet

ALT ASP .NET Rate Limiting examples


David Balbin retweeted
Zip files for AI/ML projects!
KitOps revolutionizes how teams package, version, and share AI/ML projects by creating a ModelKit, which is like a zip file containing the entire AI project—model, data, code, and settings.
100% open-source, Zero MLOps headaches.

David Balbin retweeted

.NET Aspire 9.3 is here with copilot.
devblogs.microsoft.com/dotne…
#dotnet #aspire #github #copilot
