
Senior Research Scientist @GoogleDeepMind, Previously Robotics @CarnegieMellon, EE @IITKanpur, StudApps (https://xitter.cf/t.co/iDVr86IjhA)
Mountain View, CA
Joined May 2009
- Tweets771
- Following1.9K
- Followers908
- Likes924





Pinned Tweet
Our Vision-Language-Action robot demo at #RSS2025 was eye-opening. The ultimate eval for any generalist model: new environment, new objects from audience, and new instructions.
For the first time it really hit me: what if we've been underestimating what these models can do?
Debidatta Dwibedi retweeted

Introducing Veo Robotics!
In this work, we show that an action-conditioned video model can be used as a general robot simulator for evaluation, safety, etc.
veo-robotics.github.io

Debidatta Dwibedi retweeted

🔥Gemini Robotics On-Device is here! VLA with similar generalization, instruction following, and fast adaptation as our March release, now fits on a 4090!
More exciting: we're 🚀an SDK and a model dev service (flywheel) alongside it 🎯= democratizing model development!
#DeepMind #robotics is collaborating with select Trusted Testers to refine the process. For everyone else, check the 🧵 below for videos showcasing.
We're just getting started—all suggestions and guidance are welcome!
deepmind.google/discover/blo…

What was once a dream is now real! ✨
Excited to announce Gemini Robotics On-Device: our VLA model that runs locally and shows impressive performance on 3 robot types. On-device intelligence, no internet needed!

Debidatta Dwibedi retweeted

Booster recovery controller from last night. Sim design, training and deployment on hardware took < 1 day. With @qiayuanliao
Debidatta Dwibedi retweeted

✨🤖 Today our team is so excited to bring Gemini 2.0 into the physical world with Gemini Robotics, our most advanced AI models to power the next generation of helpful robots. 🤖✨
Check it out! youtube.com/watch?v=4MvGnmmP…
And read our blog: deepmind.google/discover/blo…
We are looking forward to seeing how robot developers will use these models to continue to advance robot performance with Gemini at the core.

Meet Gemini Robotics: our latest AI models designed for a new generation of helpful robots. 🤖
Based on Gemini 2.0, they bring capabilities such as better reasoning, interactivity, dexterity and generalization into the physical world. 🧵 goo.gle/gemini2-robotics
Debidatta Dwibedi retweeted

✨New blog post✨: my attempt as a vision researcher at finally understanding RLHF -- a deep dive into PPO & DeepSeek's GRPO!
No hot take, I promise.
yugeten.github.io/posts/2025…
Debidatta Dwibedi retweeted
The ultimate test of any physics simulator is its ability to deliver real-world results.
With MuJoCo Playground, we’ve combined the very best: MuJoCo’s rich and thriving ecosystem, massively parallel GPU-accelerated simulation, and real-world results across a diverse range of robot platforms: quadrupeds, humanoids, dexterous hands, and arms.
Best of all? You can get started today with a single command: pip install playground
playground.mujoco.org/
Debidatta Dwibedi retweeted

Gemini 2.0 Flash's video understanding is here 🚀
Think: search in videos via timecodes, extract text from moving camera footage, analyze screen recordings in real-time interactions with native audio out 🔊
Come and try it aistudio.google.com/ 😀
youtu.be/Mot-JEU26GQ?si=buGM…
Debidatta Dwibedi retweeted

🧵1/8 So annoying when my 🤖 vacuum cleaner buzzes loudly during my Zoom meeting! Can we teach robots to be aware of their noise levels at home? Introducing ANAVI—a framework that uses indoor visuals to predict sound propagation! 🎶🏠
Debidatta Dwibedi retweeted

YouTube is a LARGE dataset of demonstration videos to train Generalist robot agents, but lacks action data.
How can we learn DEXTEROUS skills from them?
In #CoRL2024, we explore the problem of learning a Generalist Piano Playing agent from YouTube videos.
pianomime.github.io/

Debidatta Dwibedi retweeted

As we explore new opportunities and the future of this talented group, we’re grateful for all the support. Feel free to reach out—our DMs are open!
@mohito1905 @younggyoseo @iainhaughton @nc__dev @chrysalis_ai @eugene_teoh @JafarUruc @SridharSola
Debidatta Dwibedi retweeted

We just released PaliGemma-3B, a very capable Vision-Language Model. Do not waste any time, finetune it for your task:
Code: github.com/google-research/b…
Colab: colab.research.google.com/gi…
Kaggle: kaggle.com/models/google/pal…
HF: huggingface.co/collections/g…
Vertex AI: console.cloud.google.com/ver…
Debidatta Dwibedi retweeted

We just released a big 🎁GIVT update!
📈 Larger models and improved image generation results across the board
💡 Improved GMM formulation and adapter module
💻 Code, model checkpoints, and a colab are now available at github.com/google-research/b…
More details below... 1/

Decoder-only models only work with discrete tokens, right? 🤔 Excited to present
🎁GIVT: Generative Infinite-Vocabulary Transformers,
a simple way to generate arbitrary vector sequences with real-valued entries using transformer decoder-only models!
arxiv.org/abs/2312.02116
1/

With Vid2Robot, we take a step towards developing robots that can perform tasks by observing humans do them in videos.
Check 🧵 below for more details.

What if we could show a robot how to do a task?
We present Vid2Robot, which is a robot policy trained to decode human intent from visual cues and translate it into actions in its environment. 🤖
Website: vid2robot.github.io
Arxiv: arxiv.org/abs/2403.12943
🧵(1/n)
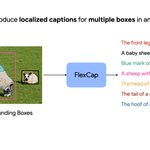
Can we train a model to describe different parts of images in varying levels of detail?
Introducing FlexCap, a VLM designed to output localized captions in N words where we can control N with special length tokens.
flex-cap.github.io/
FlexCap has been useful for robotics. We used it in AutoRT (auto-rt.github.io/) to find objects in the robot's environment. It also helped create the dataset used to train SpatialVLM (spatial-vlm.github.io/).
Project webpage: flex-cap.github.io/
Arxiv: arxiv.org/abs/2403.12026
This is joint work with @viddivj, @JonathanTompson, Andrew Zisserman and @yusufaytar .