
Nexus @FireworksAI_HQ Prev: @Google @RobinhoodApp @ycombinator Alum
Palo Alto, CA
Joined June 2010
- Tweets169
- Following0
- Followers2.5K
- Likes34K



Sriram retweeted

Routing is the hard part of multi-model systems - matching task attributes to model strengths (or an ensemble of them), optimizing cost, preserving cache, and personalizing over time so the same prompt can route differently for different users.
Nexus Auto does that per turn: ensembles open models on @FireworksAI_HQ for the easy work, Claude/GPT on your keys when the task needs it.
Stable ID, Pareto cost, zero data retention, drops into existing tools. That’s the control plane that makes specialized intelligence practical.

Sriram retweeted

We built the best model router on the market. Give it a try.

Nexus Auto (Sol) by @FireworksAI_HQ 's is the first model to reach 60% on the Vals Router Index, now ranking #1 at just $1.25/test.
It leads the previous #1, Router (Ramp), by roughly 2 points.

Sriram retweeted

.@datadoghq 🤝 @FireworksAI_HQ
Today, we’re launching support for open models from Fireworks in Datadog Agent Observability 🎆
Owning your intelligence means owning how you evaluate it. Use open and fine-tuned models as LLM judges and test prompts in the Playground.
Try it out in Datadog Agent Observability! More ways to specialize your agents coming soon.

Sriram retweeted

Meet the new Nexus.
Nexus helps individuals and enterprises use open and closed models in their existing AI tools, choosing the right model and helping lower the cost of each task.
Getting started is simple with subscriptions from $8/month: bit.ly/newnexusx
Sriram retweeted
lots of speculation about fireworks in sf tonight
not related to elections
we at @FireworksAI_HQ had our inaugural Forge conference and a namesake display is the best way to wrap it
huge thanks to our incredible speakers, videos will be out shortly at fireworks.ai/forge

Sriram retweeted
Specializing @Kimi_Moonshot K3 for your own tasks takes fast iteration and stable training.
Our new research explains how Fireworks optimizes training, rollouts, and weight updates together to make reinforcement learning practical at 2.8T parameters.
1/3 🧵

Sriram retweeted
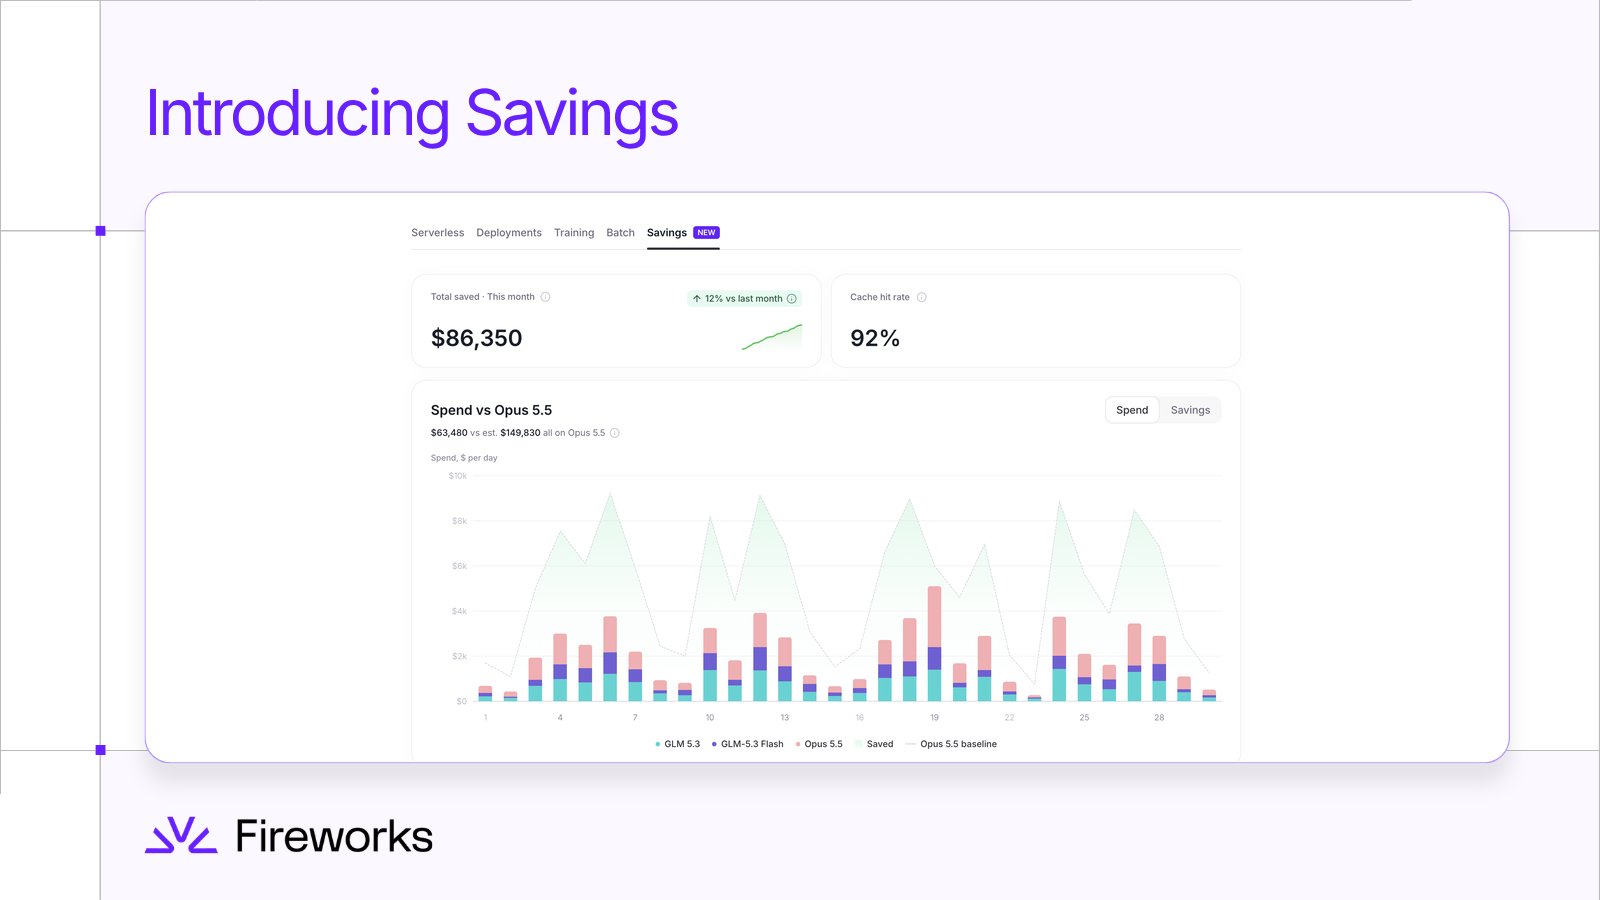
New in Nexus: Savings
See how much Fireworks open models and FireRouter are saving your team, by user and model.
Plus, track your cache hit rate.
Check out Nexus: bit.ly/4y3vrfW
Sriram retweeted
We ran 18 models across 113 real coding tasks on DeepSWE, then went back and asked a simple question: what if every task had routed to the model that handled it best?
Answer: 97.6% solve rate at $1.88 per task, versus the best model at 74.1% at $6.52.
The next frontier is a router.
Full analysis: fireworks.ai/blog/the-fronti…

Sriram retweeted

Prediction: within 12 months, top three models will be open source.
Economic winners will be the American clouds that serve them:
Nebius
Iren
Baseten
Together
Fireworks

Looks like today may be a record day for token volume % of open models on Vercel AI Gateway:
🟦 Open 78.4% 🟨 Closed 21.6%
While spend 💲 usually tells a different story, #3 and #4 today are Moonshot AI & DeepSeek. Adding Z.ai, their combined spend surpasses OpenAI (#2).
(Do note that's the spend for inference of the model across providers (mostly in the US), not revenue going directly to the open weight labs.)

Sriram retweeted
Excited to continue our partnership with the @alibaba_cloud team on this one, bringing the latest version of Qwen's flaship model to the Fireworks community. Start building with Qwen3p8 today: fireworks.ai/models/firework…

Developers need speed and uncompromising production quality. 🚀
We’ve partnered with @FireworksAI_HQ to deliver exactly that for Qwen 3.8 Max. Build faster, scale effortlessly. 🤝
#Qwen #FireworksAI #LLM #OpenSource

Sriram retweeted
We invite you to Forge.
At Forge, we will challenge you to make your own frontier.
You'll spend the day with the builders, researchers, and technical leaders pushing AI forward.
Lin Qiao. Jensen Huang. Jay Parikh. And more.
Apply to attend: fireworks.ai/forge

Sriram retweeted
GLM 5.3 is now available for training on the Serverless Training API, joining Kimi K3, Qwen 3.8 27b and more. GLM 5.3 Flash coming soon.
No sales demo or DMs required.
Here to help as needed, but you can also spend that time building.
Start with docs or a pre-made recipe ➔ github.com/fw-ai/cookbook/tr…

Sriram retweeted
Many assume that agent spend goes toward output tokens.
When we ran DeepSWE on Astra vs. DeepSeek V4.1-Flash, input tokens outnumbered output 174 to 1. 99.6% were cache hits. Those hits are 60% of the bill.
Net result? Same quality. $0.43/task vs $6.52.


Sriram retweeted
periodic reminder: cache hit rate and model token efficiency (# of turns, # reasoning tokens) matter more for cost than per-token sticker price
working on more updates to ⬆️ cache hit rate on @FireworksAI_HQ

same model. same list price. 5.7x apart in real cost.
glm-5.2 across 6 hosts:
@FireworksAI_HQ 18% of list
@sferenceai 30%
@tensorx_ai 43%
@nebiustf 100%, caches nothing
the price sheet tells you almost nothing. cache hit rate is the price.

Sriram retweeted
The most ambitious companies are training models to outperform the frontier on the capabilities that differentiate their business.
Today, we announce the general availability of our Training API and Fireworks Lab, making model specialization accessible to all organizations.

Sriram retweeted

🧵How we trained Tenet version zero in under two months:

Recently @Harvey introduced Tenet, its first model, trained for long horizon legal work.
Harvey post-trained it from a Kimi K3 base in collaboration with Fireworks using async RL on our Training API.
A thread on promising initial results for both performance and cost-efficiency🧵

Sriram retweeted

Around 2 months ago we started working with the @harvey team with the vision to train a SOTA model for long horizon legal work.
It was a very fun ride with some huge learnings on post training the largest MOEs for domain specific work, some learnings in the thread ....
Sriram retweeted
Congrats to @harvey on Tenet, their first model and a milestone for legal AI.
We’re proud to have co-developed it with them, setting the foundation for firms to build their own specialized intelligence.
Read the full writeup: harvey.ai/blog/post-training…
