

Inframancien des nuages. Familier des runes Q4 et des incantations CUDA. Je fais tourner l'IA chez moi, je raconte ce qui marche, ou pas.
Dans un paquet UDP
Joined September 2010
- Tweets3.1K
- Following380
- Followers215
- Likes6.2K






DumbleD retweeted

Drop your best texture to wrap your dragon 🤩

I took a photo of a bowl on my desk. 📸
55 seconds later: a tileable, game-ready 3D material, path traced live in the browser, straight into Godot and Blender.
Built with Meta’s Muse Spark, SAM 3.1 & Muse Image for the Meta Global AI Hackathon.
youtu.be/lK5YGg_GBmg

Comme dirait une pub sur T’Fou « fais une photo et habille le dragon à ton image ! » n’importe quelle surface s’applique. C’est fou ! Bien joué ! Les modders vont aimer je pense 😁
I took a photo of a bowl on my desk. 📸
55 seconds later: a tileable, game-ready 3D material, path traced live in the browser, straight into Godot and Blender.
Built with Meta’s Muse Spark, SAM 3.1 & Muse Image for the Meta Global AI Hackathon.
youtu.be/lK5YGg_GBmg
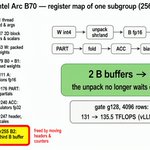
🚀 Proud of this PR merged! Prompt processing for Gemma 4 E4B is now 2-2.6× faster on Intel Arc Pro B70. Massive win for local AI workloads on Intel GPUs: less waiting, more tokens🔥 #OpenSource #LocalAI #IntelArc #Tensorfold

TensorFold engine 1.2.1 is out.
A few highlights:
• MiniMax-M3.1-Flash on CUDA across two GB10s, using Mia-AiLab's EXL3 pack.
• Gemma 4 31B on GB10 with Google's MTP assistant: 28.3 tok/s versus 12.2 undrafted, at one stream.
• Qwen3.5/3.6 windows of 1,048,576 tokens on CUDA with YaRN.
• MOSS-Image end to end on Metal, via the CLI.
• Gemma 4 E4B prompt processing 2 to 2.6 times faster on Intel Arc Pro B70.
There are also opt-in GLM long-conversation improvements, server load reporting, Living Weights bulk fact deletion and fixes for lesson failures and Flash Next's long-prompt slowdown on GB10.
Huge thanks to everyone who contributed, tested and reported issues:
@andersjw_ @atasrb @Bizuayeu
@grantoverton @ivanfioravanti @jayleaton
@niklaslenz_ai @2Halves1brain @wesley4546
And on GitHub: AbrahamCete, akol1, BlivionIaG, BobClawblaw, gilby, Jenpo, jschmied, kieranscotney, laudney, Mirrdhyn, ppardus, russellmm and ThomasHalwax.
Upstream fix credits: florianbrede-ayet and mikolaj92.
Thank you for the time, code, testing and hardware access you keep sharing with TensorFold. Apologies if I've missed anyone.
@petruspennanen @plotarmordev @MiaAI_lab @volatilemarkts
tensorfold.dev

Gemma 4 on Intel Arc is now on this version 1.2.0 🎉🎃 Next version will introduce 2x to 2.8x in prefill speed, more than 15k tok/s on the same GPU! @intel @fragtalife #LocalAI
TensorFold engine 1.2.0 is out 🙌
Qwen3.8-27B with MLX 4-bit weights and DFlash2, compared with 1.1.9:
• M3 Ultra: 14.4% faster decoding with one stream, 44.2% higher combined throughput with 16.
• M5 Ultra: 5.8% faster decoding with one stream, 25.2% higher combined throughput with 16.
New support includes:
• MiniMax-M3.1-Flash on Metal.
• NVFP4 Qwen3.6-35B-A3B and dense EXL3 Qwen3.8-27B on CUDA.
• Gemma 4 E4B on Intel Arc Pro B70.
The measured speedups kept matching tokens. Qwen-VL image replies can differ from 1.1.9 because image preparation now matches the checkpoint's own processor.
Huge thanks to everyone credited in this release:
@bhcc2025 @Bizuayeu @diwakergupta @jvr0x @jayleaton @joshuaswarren @woolsey @petruspennanen
@volatilemarkts @MiaAI_lab @plotarmordev
And on GitHub: AbrahamCete, akol1, alexderz, Arminova, BadAd84, BlivionIaG, BobClawblaw, fche, gilby, jrb-ai, jschmied, laudney, Mirrdhyn, mrv777, ppardus, simon-lin88, ThomasHalwax, valacroix and wojo.
Thank you for the PRs, reviews, testing, bug reports and hardware access. The time and knowledge you keep sharing with TensorFold mean a lot to me.
Apologies if I've missed anyone.
tensorfold.dev

Gemma 4 E4B (NVIDIA Nemotron 3.5 Bolt E4B) now runs on the Intel Arc Pro B70 in #TensorFold main.
4-bit, on one card: 6,772 tok/s prompt, 135.6 tok/s decode. Served chat: 140 / 253 / 426 tok/s at 1 / 2 / 4 streams.
Build from main for now; it isn't in a release yet. More prefill speed is coming.
github.com/ashhart/TensorFol… @IntelAI #LocalAI

Hi @NVIDIAAIDev @NVIDIAAI , a license question on nvidia/NVIDIA-Nemotron-3.5-Bolt-E4B-4GB-DFlash: the model card says OpenMDW-1.1, but the GGUF metadata (general.license.name) says nvidia-software-and-model-evaluation-license. Which one applies? We'd like to publish results with it. Thx 🙏
La famille Gemma 4 E4B sur l’Intel Arc B70 ca donnerait dans les 12000 tok/s en prefill à 8k tokens⚡️ Pour faire avaler des tonnes de documents, ça commence à être intéressant 😁 J’attends encore d’autres pistes de perf. Et toujours 1100 tok/s sur 4 flux de code vérifiés bit à bit. #Tensorfold @IntelAI @fragtalife @yannFichant
NVIDIA's Nemotron 3.5 Bolt E4B (Gemma 4 E4B) now runs on a ~€1,900 Intel Arc Pro B70 in #TensorFold:
• 6,770 tok/s prompt, 136 tok/s decode on one stream
• 426 tok/s across 4 concurrent chats
PR: github.com/ashhart/TensorFol… #LocalAI @ashxhart @fragtalife @yannFichant @IntelAI
Gemma 4 E-series groundwork landed on #TensorFold main:
• #1400 E4B geometry in the family config
• #1401 tensor plan, BF16/8-bit overrides
• #1402 per-layer inputs, bit-identical to MLX bf16 at real E4B shapes
Thanks @ashxhart for the sharp reviews 🙏
github.com/ashhart/TensorFol…

Best part of the review: Ash asked for MLX itself as the oracle, not a float64 self-check.
Now all 13 steps are hashed against MLX 0.32.4 prints, and his M5 Ultra matched my M4 Max digests exactly.
github.com/ashhart/TensorFol…
github.com/ashhart/TensorFol…

Next: a PR building on this to bring the Intel Arc backend (XPU, Level Zero, merged in #802) to the Gemma 4 family. Useful for @pollenrobotics #MicroDuck and @NVIDIAAI Nemotron 3.5 Bolt E4B RL on my rigs. Full app covering unboxing to autonomic ducks lands soon.
Same rule as before: receipts first, then serve.
#LocalLLM #IntelArc @fragtalife @yannFichant @IntelAI
Le canard parle français 🦆
#Microduck de @pollenrobotics, en simulation pour l’instant : une phrase, et Nemotron Bolt E4B avec notre LoRA décide en ~74 ms sur une Intel Arc B70 (#TensorFold XPU). Le Mac pilote tout depuis une petite console SwiftUI.
Prochaine étape : le même cerveau sur Metal. Hâte de recevoir mon petit coin coin 😁 Au fait, je publie tout le travail sur un dépôt GitHub bientôt.

Notre #microduck a sa visu de la simulation 3D dans l’app👌
Portage du LLM sur Métal M1-4 pour Tensorfold en cours. En gros, on aura le choix (pour le moment) entre Linux (Intel B70) ou Mac Metal, le reste sera embarqué dans l’app: LLM, contrôles, etc. Et Manette DualSense ! 🤞

Notre petit @pollenrobotics #microduck agit sur contrôle vocal > TensorFold Metal sur M4 > action dans le simulateur (0,3ms) ✅ Cela fonctionne avec Tensorfold XPU (Intel B70) aussi 👏 Hâte de recevoir l'exemplaire pour terminer l'intégration QR code et NFC pour le démarrage.

An #NVIDIA model, on an #Intel GPU, running a #TensorFold engine, piloting a @pollenrobotics duck.
This is either the future of physical AI or the start of a very nerdy sitcom 🦆
Yes, I'm porting Bolt E4B to the B70 now 🐤
research.nvidia.com/labs/nem… Coin ! #Microduck
Just ordered two @pollenrobotics #microduck 🦆🦆 (yes, after Jensen’s shout-out, I’m clearly not the only one 😁)
Plan once they land: let a local LLM powered by #TensorFold on an Intel B70 decide what they do next. Waddle, turn, nod, sit. It picks one, really fast.
No cloud, no script, just duck democracy 🤗 #LocalAI

Would /v1/decisions (label probabilities from one prompt pass, no generation) be useful to you in #TensorFold’s native engine? Working on Flash Next CUDA (DGX Spark) first; the hook would be shared for others models. @IntelAI Arc B70 users, interested too? cc @ashxhart #LocalAI
Two contributions to TensorFold for Flash Next on a Spark (GB10), native CUDA engine.
First: prompt processing 1.4x to 1.8x faster, bit for bit with 1.1.0 (128k prompt: 121.7 s → 68.8 s). github.com/ashhart/TensorFol…
Second: structured output and required tool calls, enforced by the grammar with MTP drafting on, same tokens as without drafts. Useful for agents that need a tool call every time. github.com/ashhart/TensorFol…
#LocalAI #TensorFold

🎉 Our Intel Arc Pro B70 backend for #TensorFold is merged and ships in v1.1.0: Qwen3.8-27B served natively over Level Zero, with drafted = plain, concurrent = solo, resumed = fresh, all bit-for-bit. Thanks @ashxhart for the careful review! Next up: Qwen MoE for Intel Arc and Flash Next on the Spark. @IntelAI @fragtalife #LocalAI