

Trying to solve sample efficiency prev: Engineering physics @iitbombay '23
Joined June 2023
- Tweets788
- Following657
- Followers4.1K
- Likes2.8K



Pinned Tweet
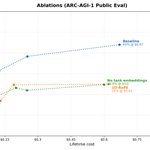
44% on ARC-AGI-1 in 67 cents!
Trained from scratch in 2hrs on a 5090
Matches TRM, beats HRM and is way faster & cheaper
No recursion, just a transformer
Also, 7% on ARC-2 🧵

didn’t know my botc lobbies and my ai timeline were the same people

I spent 20,000 dollars in API credits having different AI models play each other at Blood on the Clocktower (a Mafia or Werewolf type social deception game).
The results were fascinating. Models have gotten much better over the course of this year at creative on-the-spot scheming and bluffing, and also at reasoning as a team to break apart these underground conspiracies.
I go through some of the most standout games these AIs played in this video. The new models are getting pretty good. If my friends pulled off some of these moves while we were playing, I’d give them a fist bump.
Fwiw, OpenAI’s newer models are much better than Anthropic’s at this game.
You can see the full benchmark at the website, and I’ve also made it so that you and your friends can play again the AIs: clocktowerbench.com
1
429
Mithil Vakde retweeted

What, if some day or night a demon were to steal after you into your loneliest loneliness and say to you: ‘This life you will have to live in an age of chaos; in the most interesting times; in an era when the foundations of civilization are shaking and few dare to step off the crumbling tracks laid before them.’
Would you not throw yourself down and gnash your teeth and curse the demon who spoke thus? Or have you once experienced a tremendous moment when you would have answered him: ‘You are a god and never have I heard anything more divine.’
Mithil Vakde retweeted

What if your devices, apps and agents knew what you wanted?
You finish breakfast, and your Uber is booked.
Running late, your agent sends a “Running late” text.
You reach home, and your lights turn on.
AI is proactive now. But it still needs your yes. It waits, for you to unlock your phone, open an app and tap approve. Every time, hundreds of times a day.
AI needs its own interface.
Aina is a ring with a screen that predicts and shows you the three things you’ll need next. One flick of your thumb, and it’s done. For everything.
✦ Cues: proactive suggestions, ready before you need them
✦ Voice: talk to your agents, take notes, dictate
✦ Remote: control your music, Mac and TV
✦ Calls: right from your hand
Pre-orders open now
aina.com
Mithil Vakde retweeted

We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: rikiyat.github.io/blog/weigh…

Readers added context they thought people might want to know
LLM was given weights explicitly as text in prompt and used code/forward passes (per authors' logs) to ablate Qwen looping direction, a known thinking-mode issue per model card. Primarily fixed repetition in that mode, not general 'natively' improving weights/math.
rikiyat.github.io/blog/weight-sp…
github.com/RikiyaT/lm_und…
huggingface.co/Qwen/Qwen3.5-0…
huggingface.co/RikiyaT/Qwen3.…
Mithil Vakde retweeted

I manually inspected 40,000 animations to post train an LLM to make demoscenes.
Scraped 10 years of demos, did continued pretraining, curriculum learning and finally RLHF-ed with myself as the reward function.
Yes, models can have "taste".
All you need is data.
1/6

Mithil Vakde retweeted

Launching RNAFoundry.com – we manufacture personalized cancer vaccines.
Mithil Vakde retweeted

Launching Junction: come speed-run the semiconductor tech tree this December in Bangalore.
We’re flying in students from all over India 🇮🇳 to a 2-week fabrication retreat at @_lagrangepoint to build equipment, design chips and engineer processes, with our friends at @hackerfabindia.
India still needs thousands of semicon engineers -- the ecosystem to produce them isn’t mature enough yet -- we're changing that.
Current applicants have built vacuum chambers to study plasma physics, RISC-V processors from scratch, scanning tunneling microscopes, et cetera
At junction you will:
1. Propose a project
2. Figure out a plan with the Junction team.
3. Iterate fast towards a working prototype, with help from the Junction team
4. Be mentored by top semiconductor hackers and specialists.
5. Demo to industry leaders, founders, investors, and your fellow craftspeople
Flights, accommodation and project expenses? All covered. Apply on the link below
wow

I've always believed that intelligence should come from simple, general building blocks that learn their own abstractions directly from raw data; in other words, the bitter lesson. I think we're finally seeing a real step towards AI that can learn from all data.
Language modeling on raw bytes is a microcosm of this ideal, and to me it's a central problem in AI: if we can't build LLMs that learn end-to-end from bytes, how will we handle the rest of the world's data that we understand even less?
Last year we introduced hierarchical networks (H-Nets) as a first step. Our new version finds up to 3-5x efficiency gains in controlled scaling law experiments, and at larger scale matches an open-source model trained on 11T tokens with ~10x less data and compute. The posts below walk through what we found and why we think it works.
1
27
3,088
Wrong. Humans will do economically useful work DESPITE ASI being better at everything
Tldr: Doesn't matter that a robot can kick a ball farther than any human. I will still enjoy my human team doing it better than the other stupid human team
The disempowerment view stems from a snobbish and wrong understanding of what is "economically valuable" work
The economy is ultimately driven by human desires that evolution RLed into our nerves. Thats it. It is a metasystem that values and rewards work based on how many reward circuits it cumulatively fires among all humans. We're already a superorganism that way.
There's no inherent value in doing innovative or tech stuff other than us setting up metasytems that reward it abnormally high (eg: money through VCs and moral high status through sociological metasystems) bc the large amount of reward circuits firing bc of it
Why does sports have so much money? Because we have been RLed like crazy into being tribalistic. Anytime your tribe does well, or the other tribe does bad, you feel great.
We are also RLed to do this to be tribalistic about arbitrarily abstract ideas like theories, companies, even ideas themselves. Youll see this on the internet in crazy fandom wars, wikipedia edit wars.
ASI is one of the grand prizes that the economic engine has been driving humanity to collectively and unknowingly build (yes there are more grand prizes!). This entity can finally solve all the negative reward producing problems that humans are not smart enough to solve.
But this doesnt mean we have to build ASI in the form of an all-controlling god in a box!! We dont need to disempower ourselves!!
We do have a choice. We can find a way to get all the benefits of ASI AND keep our freedom AND minimise the downsides
And it isnt hopeless. People like Elon and Ilya have showed us that single individuals can change the path of the human superorganism.
If you dont like the ASI vision someone else is building, then build your own! Be ambitious and take that shot.

I now type "explain in easy to understand language" 100s of times a week
Weird way to experience jevon's paradox
3
42
1,343
Mithil Vakde retweeted

Ninth update to OpenAI problem #109 (integer multiplication): we are now past 2^-12.
κ = 2⁻¹¹·⁰⁶⁶ (tightened from κ = 2⁻¹⁸²)
The exact witness is 4.6637 × 10⁻⁴, about 3.70 fold over our previous 1.2613 × 10⁻⁴, and a 2¹⁷⁰ fold improvement over the original OAI result.

Eighth update to OpenAI problem #109 (integer multiplication): we are now past 2^-13.
κ > 2⁻¹³ (tightened from κ = 2⁻¹⁸²)
The exact witness is 1.2613 × 10⁻⁴, about 1.97 fold over our previous 6.397 × 10⁻⁵, and a 2¹⁶⁹ fold improvement over the original OAI result.
Mithil Vakde retweeted
I think one of the hard things AI is going to do is force a lot of people to look at why human beings do things. Hard because ultimately we do most of what we do, including many beautiful things, as some form of status seeking.
Mithil Vakde retweeted

I think I just trained NanoGPT in 9.65 seconds!?
Yesterday, @hermanbrunborg used a connected longest exact match model, trained concurrently on CPU, to get the nanoGPT record from 39.9 seconds to 21.5 seconds, in an impressive open PR. By adapting their work, and generalizing the CPU model to a larger share of the tokens, I got the record down to 9.65 seconds, and submitted the PR this morning.
I built on three open PRs, in addition to my contributions: the main basis for my generalization was from @hermanbrunborg, and additional work from @nthngdy, @cyrusghane, and Daniel Monroe. Their engineering is extremely impressive.
Of course, all of our records are still subject to review. As I mentioned in my comment on Herman‘s PR (and in my own PR description), CPU usage is a gray area in nanoGPT. Their PR was the first to discover a clever way to effectively use CPU during the run, so I’m looking forward to the official reviews.
This was another very fun challenge! Particularly (potentially) breaking the 10 second barrier yesterday. So much engineering tact is yet to be explored.
Huge shoutout to the three authors of the PRs for their innovations.
@hermanbrunborg - I will also be at stanford for the weekend along with some of my cofounders, and sf for a couple days after, would love to chat more IRL, if you’d be open 🙂
engineering physics gives you the best of both worlds :)

The future light cone of discoveries rounds up to 100% engineering, as the set of physics rules that govern our reality is very tiny compared to what can be done with those rules.
The reason I didn’t choose a career in physics, my favorite subject, is that I would be stuck waiting for a new collider or telescope. Better to advance technologies that ultimately enable discovery of new physics.
10
1,549
Mithil Vakde retweeted

After seven years, I've made the hard decision to leave Google Deepmind.
I joined Google in 2019 because I believed we could make build models to understand and generate code.
Back then, very few people had that conviction. I’m glad I found those people at Google and that we worked hard to make that dream a reality.
Coding is now democratised and it will be used to solve everything else!
