

Co-founder @QAWolfHQ, Previously @Bridgewater, @cityblockhealth. Doing my best every day 🐺
Seattle, WA
Joined October 2019
- Tweets140
- Following163
- Followers119
- Likes363


Laura Cressman retweeted

Today we announce @InspiredCap Fund IV. $450m more to back rational optimists shaping the intelligence age. The next decade will be unlike anything we've ever seen. Buckle up!

Today, our team is excited to announce @InspiredCap Fund IV, $450M in new capital to back early-stage founders.
There has never been a moment in history when more is possible. It takes just one person with exceptional ambition to take on the world’s problems and change billions of lives for the better.
Asking Claude the hard questions. It's trying to thread the needle between making it sound easy (for Claude Code's sake) and hard (for Salesforce's sake)


"Let me take a pass" translation: "Let me prompt my Claude."
"Left some comments" translation: "I prompted my Claude to review."
Getting tons of AI generated cold emails these days, but the strange thing is they all pretty much beg me to unsubscribe at the end. Why is that? 😅


Laura Cressman retweeted

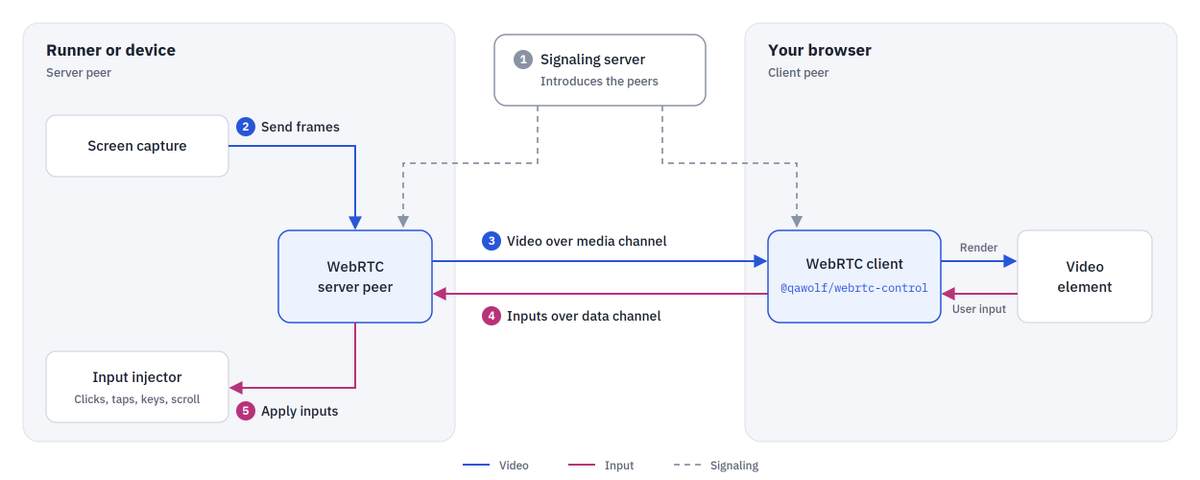
web and real phones streamed to the browser. you don't need to watch the tests live. but if you want to you can. it's little things like this that make a product experience magical

Now! Watch test runs live and in living color.
When test runs get stuck they hold up your release. Before today, if you wanted to know why a test was hanging, you had to wait for the recording and logs.
Now you (or our agent) can jump in and intervene.
qawolf.com/changelog/live-st…

Laura Cressman retweeted
not just tests, even our ai chats get a computer. here is why:

A new model launches every other week. GPT-6.1 Sol, Gemini 4 Argon, Claude Opus 5.5, each new release beating the last on some benchmark. But on its own, even the smartest model can only tell you how to fix a broken test. To actually fix it, it needs somewhere to work: your code, a browser to open your app, and a way to run the test and see it pass, that’s the sandbox.
QA Wolf AI’s is warm in milliseconds, with a real file system, a git clone of your test suite and a live browser you can watch. When the task is big, it spins up 50 more sandboxes, each with its own browser and branch.
Here’s how we built it: qawolf.com/blog/every-ai-age…

Laura Cressman retweeted
Welcome to self-driving QA 🚗
Your agent builds a feature
⬇️
Calls QA Wolf to test it
⬇️
QA Wolf bulk automates Playwright & Appium tests
⬇️
Tests run in parallel
⬇️
Verified bugs are shared with your agent
⬇️
Agent fixes
⬇️
Re-test & ship
Start here: docs.qawolf.com/
Laura Cressman retweeted
Now! Watch test runs live and in living color.
When test runs get stuck they hold up your release. Before today, if you wanted to know why a test was hanging, you had to wait for the recording and logs.
Now you (or our agent) can jump in and intervene.
qawolf.com/changelog/live-st…
Laura Cressman retweeted
Everything you can do in the UI works via MCP and always will be (via a shared contract with the API)
Our MCP server is live for Codex, Claude Code, or the coding agent of your choice.
Now when your coding agent says the PR is done and bug free, you can get a second set of eyes to run through your end-to-end test suite.
docs.qawolf.com/quick-start

Laura Cressman retweeted
Our MCP server is live for Codex, Claude Code, or the coding agent of your choice.
Now when your coding agent says the PR is done and bug free, you can get a second set of eyes to run through your end-to-end test suite.
docs.qawolf.com/quick-start
Laura Cressman retweeted
Oh yeah! The other day, @golenull and the team added semantic assertions for Playwright to QA Wolf.
They’re ideal for testing genAI apps, where the response can change but the meaning stays the same. And showing a lot of potential to cut down on flakes.
Built with Jev from @typesafeai . More from Goran 👇

Still figuring out what all we can do with Jev. One of the first places we’re putting it to work: giving Playwright tests a little judgment.
ai.expect checks meaning. ai.act can take a different route through the UI. The rest of the test stays deterministic.
Wrote it up qawolf.com/blog/semantic-ass…
