





Pinned Tweet
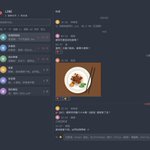
做了一個 Omarchy bar 的 LINE 面板: @OmarchyLinux
bar 上看未讀數,點開就能回訊息、傳貼圖和圖片,有已讀和通知。全部在本機跑,背後是一個用 linejs 寫的 Deno daemon。

1
1
118
Frank Y retweeted

Shopify's CEO gives his AI agents their own computer.
Tobi Lütke just shared wrapvm: a full desktop VM built for agents.
• A real Linux desktop your agent can see and control
• Its own Chrome, already wired up for browser automation
• Computer-use tools so it can click through any app
• One machine per project folder, so agents never touch your real computer
• You watch everything live from your browser, and sound can be recorded too
Your agent gets a sandbox to break things in. Your laptop stays yours.
github.com/tobi/wrapvm

Frank Y retweeted

We have dumped JAX/SGLang and rewritten the entire RL and inference stack from scratch in C/C++, which took some extra time.
Training (aka pre-training) is done. Lot of cleanup was needed on the SFT data to get that mostly right. Now, 4.8 is in RL and the evals are starting to climb. We will do a soft rollout to Bot users later this week and see how it goes.
Grok 4.8 will bear no resemblance to 4.7 (thankfully). It is not yet incredible, but, this time, the foundations are built right, so I expect it to evolve to be something special.
Frank Y retweeted

To the massive dismay of those looking to control compute, it's way too late. CPUs and GPUs are everywhere. Models will get smarter, algorithms will get better, and bottlenecks we used to believe in will be overcome. You will lose and the Internet will remember what you did.
Frank Y retweeted

The Asahi project was all about taking something closed and restricted and opening it up.
Adding new restrictions that make it harder for other projects to build on that is not the way. And that AI rejection is just silly.


Frank Y retweeted

Some news: I’m joining OpenAI to lead product management for Core Products!
I have a lot of respect for OpenAI for showing the world that scaling works, for bringing AI to over a billion people, and for believing great products are core to the mission.
I’m excited to work with @thsottiaux, an incredible PM team, and everyone across OpenAI. Together, we’ll build agents that have your back and your team’s, and keep you in control, so you get more time for the people and work you love.
Lots to learn, and lots to build. Please keep your feedback coming!
Frank Y retweeted

Kimi K3.1 recalls instructions it was never given on Terminal Bench. They match the hidden tests. K3.1 while solving: "Instructions likely distilled pitfalls from previous agents." 🤯
When we edit a task to contradict them, K3.1 refuses the new instructions and fails. Other models follow the edit.
Is it terminal(ly) benchmaxxed? 🧵

Frank Y retweeted

cool work by @mitsuhiko here! new code mode runtime
github.com/earendil-works/dj…


Frank Y retweeted

We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: rikiyat.github.io/blog/weigh…

Readers added context they thought people might want to know
LLM was given weights explicitly as text in prompt and used code/forward passes (per authors' logs) to ablate Qwen looping direction, a known thinking-mode issue per model card. Primarily fixed repetition in that mode, not general 'natively' improving weights/math.
rikiyat.github.io/blog/weight-sp…
github.com/RikiyaT/lm_und…
huggingface.co/Qwen/Qwen3.5-0…
huggingface.co/RikiyaT/Qwen3.…


Frank Y retweeted

Day 25/
We are doubling all usage limits for all Pro 100/200/500 tiers and Business Premium, effective today.
We heard your kind feedback and won’t be reducing usage limits for Pro 200, so your Work and Codex usage will stay the same. We’re also going to continue offering extended limits for dots for now, and usage of your dot will still continue to be separate from your default usage.
And we'll of course also keep shipping better models and other efficiency improvements that increase your effective usage over time.
Frank Y retweeted

DeltaDB is a new, Git-compatible version control system for agent context. It keeps every edit linked to the conversation that produced it.
@as__cii takes a deep dive into how we built it with Rust, SQLite, and Durable Objects:
delta.dev/blog/fine-grained-…

Frank Y retweeted

Announcing Artificial Analysis Intelligence Index v5, featuring 2 new benchmarks and 3 upgrades. For the first time, the majority of the Index is built on private datasets
The Artificial Analysis Intelligence Index is our composite measure of model capabilities across tasks reflecting real-world usage today. v5 is our biggest upgrade since v4 launched in January. With v5, 60% of the Index is now based on evaluations with private test sets or held-out answers.
Alongside Intelligence Index v5, we’re launching the Artificial Analysis Progress Index v1, which tracks model capability over time on one continuous scale.
New to the Intelligence Index:
➤ FrontierCode 2.0: Cognition's newly-launched private benchmark of real-world coding tasks, graded on whether a repository maintainer would merge the agent's change
➤ Terminal-Bench-Science: 70 agentic scientific research tasks, run in a terminal environment
Upgraded:
➤ HLE-Diamond (replacing Humanity's Last Exam): a refined 1,000-question version of Humanity's Last Exam, split evenly between reasoning and knowledge questions
➤ AA-Omniscience v1.1: An updated dataset with saturated and public set questions removed, new questions added, and ambiguous or erroneous questions revised
➤ CritPt v2: a private, 40-question hard subset of CritPt v2, revised by the CritPt authors and run with a code-execution tool
Staying in the Index: AA-Briefcase, AutomationBench-AA, GDP.pdf and Terminal-Bench 4.0
Removed from the Index: GDPval-AA v2.1, SciCode, and AA-LCR v1.1
Key results:
➤ Claude Opus 5.5 (max) leads at 58, ahead of GPT-6 Astra (max, 57) and GPT-6.1 Sol (max, 55): Anthropic and OpenAI hold the top five models. Gemini 4 Argon (high) is next at 50
➤ The open weights gap widens from 3 points to 12: Kimi K3.1 Pro (weights not yet released) is the top open weights model at 46. Among released weights, DeepSeek V4.1 Flash 1017 (max) and GLM-5.3 (max) lead at 32 - 26 points behind the leader and below Claude Haiku 5.5 (max, 36)
➤ Cost per task varies by more than 13x among the leading models: of the 10 highest-scoring models shown, GPT-6.1 Terra (max) is the cheapest at $0.96 per Intelligence Index task and Claude Fable 5.1 (max) the most expensive at $13.04

My 3080 10GB can back online ! github.com/Zagitta/gpu-unloc…

3
125
Frank Y retweeted

Lol I am pretty sure someone is runing a deepseek swarm to remotely patch unpatched php boxes. Well good on them.
Frank Y retweeted

Recursive_SI 联合创始人、前 Meta FAIR 研究科学家总监、前 Google 工程师田渊栋宣布,公司发布首个模型 Flint-40B-A2B。
这是一个开源本地编程模型,可在 OpenCode 和 Pi 上免费使用。
今天就试试

Today, we release our first model, Flint-40B-A2B, a fast local coding model built with our automated research system. huggingface.co/RecursiveSI/f…
1. Strong performance. 54.9% on Terminal-Bench 2.1, 89.7% on SWE-bench Pro v2, and 74.2% on SWE-bench Verified.
2. It is trained from scratch (tokenizer->Pretrain->Midtrain->SFT->RL).
3. Fast in your local laptop. Up to 2x faster than comparable models: 125+ tokens/sec on a MacBook Pro, 150+ on RTX Spark.
4. We build the complete model training pipeline in 4 month!

Frank Y retweeted

Aloha!🌺 Meet Ornith-1.5-122B: No Tradeoff Between Strong and Fast
Stronger. Faster. Leaner. Ornith-1.5-122B delivers frontier-level capabilities with exceptional inference efficiency. With superior instruction following, stronger task decomposition, and deeper understanding of real-world workflows, it achieves state-of-the-art performance among open-source models of comparable size, while running on a single NVIDIA DGX card!!
Open weights under the MIT license.
Coding
✅SWE-bench Verified: 0.845
✅TB2.1: 0.813
✅CyberGym: 0.800
✅NL2Repo: 0.512
Agentic
✅HLE: 0.446
✅BrowseComp: 0.785
✅MCP-Atlas: 0.746
✅Toolathlon: 0.708
🤗Hugging Face: huggingface.co/ornith-ai/Orn…
We can’t wait to see what you build with Ornith-1.5-122B.
