

Founded isoHunt, WonderSwipe. CTO and AI shepherd. 50/50 product / engineering
Localhost
Joined August 2008
- Tweets31.5K
- Following1.2K
- Followers4.1K
- Likes21.6K





Pinned Tweet
Imagination is more important than knowledge. ~ Einstein
My current sabbatical in New Orleans got me rethinking the meaning of work, the universe, everything. We are at the doorsteps of machine super intelligence (ASIs), what will remain are only what’s human. Intuition of the Culture girl in Iain Banks’ Consider Phlebas could out guess Minds a million times smarter than her. What else can we, I do in the coming age?
I have 2 ideas. I’ve not been more excited than since I built isoHunt 25 years ago. I’m going monk mode in my cave
The vibes must flow. Long live the builders!
APPENDIX
Vibe coding is akin to the rise of Jazz around New Orleans. What was considered devil music, low class by uneducated self taught musicians breaking all the rules of classical music birthed whole new inventive genres. I believe this will happen to all sectors of knowledge work. Professionals relying on certifications and established processes with no creativity are not going to have a good time
I also hate the word artificial in ASI. First, there won’t be AGI, we are the general intelligence. ASI should be rebranded to be more accurately MSI. There’s human intelligence, and there’s machine intelligence. Artificial will be like a racist word. We will coexist like in the Culture

There's a new kind of coding I call "vibe coding", where you fully give in to the vibes, embrace exponentials, and forget that the code even exists. It's possible because the LLMs (e.g. Cursor Composer w Sonnet) are getting too good. Also I just talk to Composer with SuperWhisper so I barely even touch the keyboard. I ask for the dumbest things like "decrease the padding on the sidebar by half" because I'm too lazy to find it. I "Accept All" always, I don't read the diffs anymore. When I get error messages I just copy paste them in with no comment, usually that fixes it. The code grows beyond my usual comprehension, I'd have to really read through it for a while. Sometimes the LLMs can't fix a bug so I just work around it or ask for random changes until it goes away. It's not too bad for throwaway weekend projects, but still quite amusing. I'm building a project or webapp, but it's not really coding - I just see stuff, say stuff, run stuff, and copy paste stuff, and it mostly works.
Benchmark is saturated with scores like that
Interesting that Terra 6.1 max can beat Sol 6.1 while still cheaper
Question is what’s real world task difficulty ceiling. For hardest coding requiring some good judgment and taste, is Terra max good enough that you’d use as workhorse?

Okay my GPT-6.1 Terra benchmark with @VulcanBench is now finished 🖖
And before I talk about the key insights from this one, let me also remind everyone that VulcanBench is a coding benchmark. 100% of the tasks in my eval suite are coding tasks.
Having now used Terra all week I can tell you, it's a stellar model for computer use, I'm crazy impressed.
But VulcanBench isn't about seeing how good a model is at computer use, it's all about seeing how well a model completes more complex coding tasks.
So now for analysis of GPT-6.1 Terra when it comes to coding. I typically say a score between 80 - 90 on Frontier v4 is the sweet spot for routine daily coding tasks.
For GPT-6.1 Terra, this means that for coding, you'll want to use Extra High or Max only. Low, Medium, and High don't really make the cut.
Looking at cost-per-task, it's a very inexpensive model to use, but when you look at it side-by-side with GPT-6.1 Sol, I'd probably just use Sol.
For me, after looking at this data, I still plan to use GPT-6.1 Terra as my go-to for computer use, but I probably won't use it for coding.
As usual, as a completely independent benchmark, everything I do at VulcanBench is available for you to review, inspect, and even run yourself if you want to.
And the traces now include tool calls so you can really examine exactly how every model I benchmark thinks!
Benchmark report: vulcanbench.com/benchmarks/s…
Model page: vulcanbench.com/models/gpt-6…
Public traces on GitHub: github.com/morganlinton/vulc…
Live long and benchmark 🖖

Cool. But how does this differ from cua.ai/cua-driver


Be Reddit
Fixing declining traffic and ad impressions by requiring login. Which increase friction not less for humans, and ai agents and scrapers with no eyes for ads will get logins and bypass regardless
Make it make sense?

> be reddit
> foster culture of rampant anti-capitalist woke circlejerking on the platform
> advertisers can’t make $ from ads b/c reddit users are commies who think all businesses are evil
> realize only way to profit is to license content to AI labs for training
> AI labs already scraped all the content
> require login to prevent future scraping
> SEO traffic goes to zero
> usage drops 90%
> die a slow unremarkable death
neat, but this is overly simplistic & punting retrieval problem to naively point to a past chat when /handoff should already be standard practice. If multiple relevant past chat to reference, "what" to search for in a haystack remains unsolved
a much more interesting and sophisticated attempt at not compacting is Uniichat or optchat, an hierarchical tree for ai agents to recursively zoom into, while oldest chats gets condensed to few bytes as distant memory but recent chats have enough details to drill into and all chats are saved in entirety: nitter.gq/victortaelin/status/21…
with which there's a Pi extension: github.com/jonaslsaa/pi-optc…
this is the holy grail when tuned to work well. A single forever chat, no more sessions management, and never compaction

Compaction is a mistake.
When an agent's context fills up, tools like Codex and Claude Code compact it:
1. The model prefills the entire session again
2. It writes a summary of everything so far
3. A new session starts from that summary
I measured this on a real ~400k-token session with Opus 5.5:
→ 38 s and $1.99 when the prompt cache has expired
→ 29 s and $0.17 when it hasn't
And the summary is lossy. The exact error message, the file path, the one number you needed is often gone.
So I do something new for Mainplane
Context retrieval works the other way around. Mainplane keeps the full record of every session as a file. When the context fills up, a new session starts right away with one instruction: "You are continuing session X. Retrieve key context from it as you go."
The agent searches the old session and copies the exact lines it needs, when it needs them.
Same session, same model: 15 s and $0.10 to get back to work. It does not depend on a cache hit, and nothing is paraphrased.
This is the bitter lesson applied to agent memory. Don't hand-design what the model should remember. Give it the full record and good tools, and let it decide.
Mainplane is open source (MIT). Link in the first comment.
It’s not a prelude, that’s what the text already says in screenshot
Another marketing wordsmith to reframe the weekly 10x as not a downgrade, 20x (weekly) was never there


Ok, so Droid 1.0 added code mode. Very impressive harness scores and token efficiency!
But where’s the Pi comparison in your Terminal Bench chart?


Performative token burning porn, not appreciating value of caching

No. We've got to stop applying old human-centric patterns to working in the new era.
delete all your wikis.
have an agent answer questions from source instead.
at spawn we have:
- zero dashboard tools
- zero docs
- we do not make or use summaries
everything we do is primary sources + intelligence
Nothing to go stale
Nothing to organize
Nothing to navigate
Always exactly up to date
Perfectly personalized
The answers get better with every model
If we want to see a chart, we ask for it, and we have it in a minute
If we want an answer to a question, we ask it, and we have a to-the-minute correct answer
Hallelujah
May capitalism and competition be praised

“One AI lab basically eats the whole US economy”
My brother in Christ, the danger of Google doing that created OpenAI, the danger of OpenAI doing it created Anthropic, the danger of Anthropic doing it created Meta Muse and SpaceX Grok, the danger of SpaceX doing it created Jeff Bezos Prometheus-Blue Origin.m…
Have some goddamn faith in human greed dammit
Even little Haiku catch twice as many major errors as human reviewers in science
Peer review, from bio in clinical trials to all scientific domains. Is now irresponsible if not also having ai in the loop
Journals as gatekeepers should have died long ago, peers are all people and ai on the internet
And ai slop remains with bigger picture taste and judgment. Human slop is in getting buried with details that clankers can do better faster

Lots of debate this week on whether journals should ban AI in peer review.
We actually tested this in our new preprint, and the results were pretty clear to me.
For context, I've reviewed for most of the big journals and evaluated 1,000 human reviews as an editor. I love to read and evaluate science.
TLDR: From now on I won't do any peer review without AI. For clinical trials, I'd even call human-only review dangerous 🧵

gary IH fung retweeted
In lieu of flowers, memorial contributions may be made to:
Johns Hopkins Alzheimer’s Disease Research Center Fund
alzresearch.org/giving/
Alzheimer’s Foundation of America Caregiver Resources
alzfdn.org/donate/
Photo Credit: Tommy Garcia


thanks Tibo for giving claude code subscription legit economic competition
is Dots actually good now, with usable limits unlike *cough* @bot ?
@AdamHoltererer chart fix again :p


Day 25/
We are doubling all usage limits for all Pro 100/200/500 tiers and Business Premium, effective today.
We heard your kind feedback and won’t be reducing usage limits for Pro 200, so your Work and Codex usage will stay the same. We’re also going to continue offering extended limits for dots for now, and usage of your dot will still continue to be separate from your default usage.
And we'll of course also keep shipping better models and other efficiency improvements that increase your effective usage over time.
Once thought impossible, the Search golden goose is dying. AI killed it. Try as they will, they’ll fold ads into ai chat as OpenAI have in free ChatGPT
I’d hold $GOOG still mainly for scientific surprises. Carbon looks exceptionally strong on science & ai biotech is next meta

As someone who has personally spent $500k / mo+ on Google Ads for years, I can tell you with certainty:
This revenue growth in Search is artificial & extremely unhealthy for Google’s business long term
Search volumes are declining as legacy search is being increasingly cannibalized by non-monetized LLM queries
Google’s response?
Manufacture revenue growth via short-sighted, highly extractive, customer-hostile tactics. I.e. charge advertisers more for lower quality clicks, including clicks they do not want and explicitly did not approve Google to charge them for
A few examples to illustrate:
For all of its history until recently, Google operated on a 2nd price auction model
I.e. if you bid $5 CPC and the next highest bidder bids $1 CPC, Google charged you $1.01 for the click (one penny more than the 2nd highest bidder) rather than the $5 you bid
This was a genius move by Google early on as it incentivizes advertisers to input their true maximum willingness to pay rather than trying to play the game of bidding low and constantly adjusting to try to stay just ahead of the next highest bidder while still not paying too much
However recently, Google silently deprecated the 2nd price auction and began charging advertisers as much as their bid and budget caps allow, regardless of what anyone else is bidding
It’s a short-sighted cash grab at the expense of the long term health of the advertiser ecosystem
Making thing worse, Google also recently nerfed keyword targeting precision
Google previously had precise keyword targeting settings that allowed advertisers pick individual search phrases to bid on, defined down to the character w/ exact match or phrase match targeting
This was one of the core features that made search advertising magic, enabling advertisers to run extremely precise campaigns based on exactly what their target customer typed
But now, even if you bid on a specific term or phrase using the strictest exact
-match targeting settings, Google will show your ad across 1000’s of unrelated keywords, labeling them as as “exact match (close variant)”
The definition of “close variant” means whatever they want it to and changes constantly. The result is advertisers get billed for clicks that are totally irrelevant to their business and that their targeting settings explicitly forbid Google from targeting. Google does it anyway and there’s no ability to turn this off
So now exact match is broad match, and broad match is just meaningless spam
This is all very bad for advertisers, but for Google, it allows them to show your ad and bill you for clicks across 1000x more searches that were previously going unmonetized (mainly because they’re garbage queries no one wants)
This is how you grow revenue atop declining search volumes
Lastly, and perhaps most egregiously, Google quietly stopped respecting budget caps by a factor of 2x. For example campaigns we’ve been running for years with $1000 daily budget caps suddenly began spending $2000+ per day
And the extra spend is entirely on the garbage keywords Google arbitrarily throws in as “exact match (close variants)” which have no value to our business, but can’t be turned off
Google offers no refunds nor any recourse for overspend or spend on keywords you explicitly did not target
These are not the actions of a healthy business. These are the actions of company whose core business is in decline but desperately needs to pump quarterly earnings so Wall Street will continue to fund insane capex while hopefully looking through their rapidly deteriorating negative free cash flow
Google operated a benevolent monopoly for the better part of 25 yrs
Meaning the value Google captured from Search was but a small fraction of the value it created, and that spread produced a potential energy that justified expectations of high earnings growth far, far into the future
This is now no longer the case
At the alter of AI capex, Google is sacrificing the golden goose

generative UI as visual explainers
fast enough to render real time, 3d or illustrative
great idea!

BC’s port, provincial issue?
How about passing a bill to overrule Liberals and do it anyways. You like that Alberta?

Haiku beating big @grok 4.7 is another side of the story. But on cognition.com/frontiercode haiku max is only 27.7%, not 34.9? What's with the different numbers @ArtificialAnlys
while Deepseek 1017 standing its ground at 28.5 is amazing for its cost


this is very cool and excited to watch/try. But as a Deepseek flash 1017 post-train, even at 33% cost cut per task,
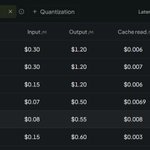
- Particle 1 is priced at $0.25 in $1 out, $0.03 cached in
- while DS on Wafer: $0.07 in $0.50 out, & $0.0069 cache
the economics doesn't work yet @Suhail


1/ Excited to announce our new company Particle
This is our first step in a series of models focused on developers.
With particle-1, we focused on token efficiency and managed to keep parity in performance while using ~45% fewer tokens.
Live now: particle.ai
