

The single platform to trace, evaluate, simulate & security test AI agents across text, voice, image & video.
Joined November 2025
- Tweets81
- Following2
- Followers9
- Likes4





𝗬𝗼𝘂𝗿 𝗮𝗴𝗲𝗻𝘁 𝗽𝗮𝘀𝘀𝗲𝗱 𝗲𝘃𝗲𝗿𝘆 𝘁𝗲𝘀𝘁. 𝗦𝗼 𝘄𝗵𝘆 𝗱𝗶𝗱 𝗶𝘁 𝗰𝗼𝗻𝘁𝗿𝗮𝗱𝗶𝗰𝘁 𝗶𝘁𝘀𝗲𝗹𝗳 𝗳𝗶𝘃𝗲 𝗺𝗲𝘀𝘀𝗮𝗴𝗲𝘀 𝗶𝗻?
Single-turn tests stop at one response. Conversations keep going.
We put together a guide on testing AI agents through multi-turn simulation, using Netra.
From first scenario to root cause in one read.
Link in the comments.

Read the full guide here: getnetra.ai/blog/ai-agent-si…

Do your evals stop the day your agent ships?
Testing before release covers the scenarios you planned for. Real users bring the rest.
We put together a guide on how to evaluate AI agents before and after deployment, using Netra.
Curious how it’s done?
Link in the comments.

Here’s the full guide 👉 getnetra.ai/blog/ai-agent-ev…

𝗧𝗵𝗮𝘁’𝘀 𝗮 𝘄𝗿𝗮𝗽 𝗳𝗼𝗿 𝗡𝗲𝘁𝗿𝗮 𝗮𝘁 𝗖𝘆𝗽𝗵𝗲𝗿 𝟮𝟬𝟮𝟲.
For three days, one question kept opening up conversations at our stall:
How are you testing your AI agents, and how do you know they’re reliable?
What we heard was interesting.
Most teams are familiar with observability and evaluations. But the conversations changed when we started showing how deep agent evaluation can go, and how reliability needs more than checking a response once.
We also met teams using separate platforms for observability and evaluations, building their own evaluators, or still relying heavily on manual testing.
That gave us the opportunity to show a different approach.
Netra brings AI agent observability, evaluation, simulation, and security testing together in one platform, built for text, voice, image, and video agents.
Simulation, Agent Insights, security testing, and online evals were some of the areas that sparked the most curiosity. People wanted to understand how these different layers could work together to help them build more reliable agents.
And we learned just as much from hearing about the reliability challenges teams are facing in the real world.
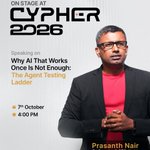
On stage, Prasanth, Co-founder and CTO of Netra, took that conversation deeper with “Why AI That Works Once Is Not Enough: The Agent Testing Ladder.”
From founders and CEOs to data scientists and AI agent builders, it was great meeting everyone who stopped by, played the AI Agent Evaluator quiz, shared what they are building, and spent time with us.
That’s Cypher 2026 for Team Netra.
Want to see how Netra helps you make your AI agents more reliable? Link in the comments.
#Cypher2026 #AIAgents #AIReliability #AgenticAI #AIObservability

𝗗𝗮𝘆 𝟮 𝗮𝘁 𝗖𝘆𝗽𝗵𝗲𝗿 𝟮𝟬𝟮𝟲 𝘄𝗮𝘀 𝗮𝗯𝗼𝘂𝘁 𝘀𝗵𝗼𝘄𝗶𝗻𝗴 𝗽𝗲𝗼𝗽𝗹𝗲 𝘄𝗵𝗮𝘁 𝗔𝗜 𝗮𝗴𝗲𝗻𝘁 𝗿𝗲𝗹𝗶𝗮𝗯𝗶𝗹𝗶𝘁𝘆 𝗹𝗼𝗼𝗸𝘀 𝗹𝗶𝗸𝗲 𝗶𝗻 𝗽𝗿𝗮𝗰𝘁𝗶𝗰𝗲.
One thing we heard repeatedly was how fragmented agent testing still is.
Some teams use one platform for observability and another for evaluations. Some build their own evaluators. Others still rely heavily on manual testing.
And despite all of that, the reliability challenges remain.
So we spent Day 2 showing teams how we approach it at Netra: bringing the different layers of agent reliability together in one platform, so teams can understand what their agents are doing, evaluate them, test how they behave, and keep improving them as they evolve.
The conversations also made one thing clear.
A lot of teams are building AI agents fast, but testing still tends to happen in parts, or not deeply enough.
That is where the reliability gap shows up.
Reliable agents need layers.
And that’s what we got to show throughout Day 2.
#Cypher2026 #AIAgents #AIReliability #AgenticAI #AIObservability


𝗗𝗮𝘆 𝟭 𝗮𝘁 Cypher 2026 𝗳𝗼𝗿 𝗧𝗲𝗮𝗺 𝗡𝗲𝘁𝗿𝗮 𝘄𝗮𝘀 𝗳𝘂𝗹𝗹 𝗼𝗳 𝗰𝗼𝗻𝘃𝗲𝗿𝘀𝗮𝘁𝗶𝗼𝗻𝘀 𝗮𝗯𝗼𝘂𝘁 𝗼𝗻𝗲 𝘁𝗵𝗶𝗻𝗴: 𝗵𝗼𝘄 𝗱𝗼 𝘆𝗼𝘂 𝗺𝗮𝗸𝗲 𝗔𝗜 𝗮𝗴𝗲𝗻𝘁𝘀 𝗿𝗲𝗹𝗶𝗮𝗯𝗹𝗲?
Our team interacted with founders, CEOs, data scientists, and AI agent builders working on very different problems.
Different teams. Different agents. Different use cases.
But one pattern was clear. A lot of AI agents are being built. Testing them with the same depth is still catching up.
We got to show people how we think about making AI agents more reliable, while also learning about the problems they are running into and how they are approaching testing today.
And in between the conversations, visitors got to try our AI Agent Evaluator quiz, an interactive game that put their agent evaluation instincts to the test.
We shared a lot. We learned a lot too.
A great first day at Cypher 2026, India’s biggest AI summit and expo.
Looking forward to more conversations on Day 2.
@Analyticsindiam


𝗪𝗲’𝗿𝗲 𝘁𝗮𝗸𝗶𝗻𝗴 𝘁𝗵𝗲 𝗰𝗼𝗻𝘃𝗲𝗿𝘀𝗮𝘁𝗶𝗼𝗻 𝗮𝗿𝗼𝘂𝗻𝗱 𝗿𝗲𝗹𝗶𝗮𝗯𝗹𝗲 𝗔𝗜 𝗮𝗴𝗲𝗻𝘁𝘀 𝘁𝗼 𝘁𝗵𝗲 𝘀𝘁𝗮𝗴𝗲 𝗮𝘁 𝗖𝘆𝗽𝗵𝗲𝗿 𝟮𝟬𝟮𝟲.
Our Co-founder & CTO, Prasanth Nair, will be speaking on “Why AI That Works Once Is Not Enough: The Agent Testing Ladder.”
For anyone building AI agents and asking the harder question: how do you know they’ll keep working reliably, every time?
If you’re at Cypher, catch the session on 7 October at 4:00 PM.
@Analyticsindiam

𝗪𝗲'𝗿𝗲 𝗰𝗼𝗺𝗶𝗻𝗴 𝘁𝗼 𝗜𝗻𝗱𝗶𝗮'𝘀 𝗯𝗶𝗴𝗴𝗲𝘀𝘁 𝗔𝗜 𝘀𝘂𝗺𝗺𝗶𝘁 𝗮𝗻𝗱 𝗲𝘅𝗽𝗼.
Team Netra will be at Cypher 2026, KTPO Bengaluru, from Oct 7 to 9.
We'd love to meet everyone building and deploying AI agents: founders, engineers, product leaders, researchers, investors, and anyone curious about how agents can be trusted.
Come talk to us, and we'll show you how to make your agents reliable.
Find us at Stall 40.

𝗪𝗲'𝘃𝗲 𝗯𝗲𝗲𝗻 𝗰𝗼𝘂𝗻𝘁𝗶𝗻𝗴 𝗱𝗼𝘄𝗻 𝘁𝗼 𝘁𝗵𝗶𝘀 𝗼𝗻𝗲.
The Netra team is coming to Cypher 2026, India's Biggest AI Summit & Expo.
We've got something to share and it's coming soon.
Drop a comment if you'll be there.
@Analyticsindiam
“𝘈 𝘨𝘰𝘰𝘥 𝘥𝘦𝘮𝘰 𝘪𝘴 𝘦𝘷𝘪𝘥𝘦𝘯𝘤𝘦 𝘵𝘩𝘢𝘵 𝘢𝘯 𝘢𝘨𝘦𝘯𝘵 𝘤𝘢𝘯 𝘱𝘦𝘳𝘧𝘰𝘳𝘮 𝘢 𝘵𝘢𝘴𝘬. 𝘐𝘵 𝘪𝘴 𝘯𝘰𝘵 𝘦𝘷𝘪𝘥𝘦𝘯𝘤𝘦 𝘵𝘩𝘢𝘵 𝘵𝘩𝘦 𝘢𝘨𝘦𝘯𝘵 𝘸𝘪𝘭𝘭 𝘮𝘢𝘬𝘦 𝘢𝘤𝘤𝘦𝘱𝘵𝘢𝘣𝘭𝘦 𝘥𝘦𝘤𝘪𝘴𝘪𝘰𝘯𝘴 𝘢𝘤𝘳𝘰𝘴𝘴 𝘵𝘩𝘦 𝘳𝘢𝘯𝘨𝘦 𝘰𝘧 𝘤𝘰𝘯𝘥𝘪𝘵𝘪𝘰𝘯𝘴 𝘪𝘵 𝘸𝘪𝘭𝘭 𝘦𝘯𝘤𝘰𝘶𝘯𝘵𝘦𝘳 𝘪𝘯 𝘱𝘳𝘰𝘥𝘶𝘤𝘵𝘪𝘰𝘯.”
As AI agents move from demos to real world deployments, testing them against the conditions they’ll encounter in production becomes increasingly important.
Caroline Wong, author of The AI Cybersecurity Handbook, shares practical guidance on navigating the evolving AI security landscape, helping teams understand the risks, controls, and security practices needed as AI becomes part of their systems and workflows.
In her latest piece, Caroline takes a closer look at what it takes to test AI agents once they move beyond the demo stage, and where Netra fits into that testing cycle.
Grateful to Caroline for taking the time to explore what we’re building with Netra and include it in this conversation.
Worth a read 👉 theaicyberhandbook.com/how-t…

Your agent gave a wrong answer. Can you tell which step caused it?
Nothing crashed. The logs look fine. The problem is still in there somewhere.
We wrote a step-by-step guide to finding it, using Netra.
From setup to root cause in one read.
Link in the comments.
Make your AI agents reliable.
#AI #LLM #AIAgents #LLMOps #Observability #Netra #OpenTelemetry

Here's the full step-by-step guide to AI agent observability in Netra:
getnetra.ai/blog/ai-agent-ob…

Ever wonder why your agent suddenly started behaving differently after a small prompt edit?
No crash, no error. It just changed.
We just published a guide on how to manage prompts the right way, from versioning to testing to evaluation.
Curious how it's done?
Full guide in the comments
#AIAgents #Netra #PromptManagement


Thanks for including us, @TestMetry.
We test agents against personas that don't behave the same way, frustrated, confused, friendly, neutral, plus real scenarios like fast speech, accents, and background noise. Then we score whether it actually solved the problem, not just how it sounded.
#AIAgents #VoiceAI #Netra


𝗧𝗵𝗲 𝗳𝗶𝗿𝘀𝘁 𝗾𝘂𝗲𝘀𝘁𝗶𝗼𝗻 𝘄𝗮𝘀 𝘀𝗶𝗺𝗽𝗹𝗲. 𝗪𝗵𝗮𝘁 𝗶𝘀 𝘁𝗵𝗶𝘀 𝗮𝗴𝗲𝗻𝘁 𝗮𝗰𝘁𝘂𝗮𝗹𝗹𝘆 𝗱𝗼𝗶𝗻𝗴.
Tracing answered that. But knowing what an agent did was not the same as knowing if it did the right thing. So we built evaluation.
Then came a harder question. What would this agent do on a day we haven't seen yet. Simulation answered that. Then a sharper one. How would this break if someone tried to break it. Red teaming answered that.
Each answer opened up the next question. That is how eight layers got built, one at a time, chasing a clearer picture of what reliable actually means.
That's what Netra has become. One platform to make text, voice, image, and video agents reliable.
Link in the comments.
#AI #LLMOps #AIAgents #Netra

Make your AI agents reliable.
Explore the platform at getnetra.ai