


Pinned Tweet
Transformers use the same hidden state for two competing roles: maintaining state and predicting the next token. 🔀
Splitting these roles into two separate streams outperforms standard Transformers.
Introducing the State-Prediction Separation (SPS) Transformer.
🧵


Giovanni Monea retweeted

"The Surprising Effectiveness of Shared Memory in Looped Transformers"
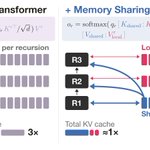
Looped Transformers usually maintain separate KV-caches for each pass, but this paper shows that sharing memory across loops can actually improve model quality while reducing memory usage.
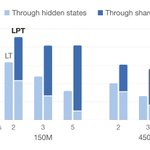
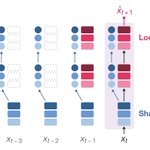
So Looped Prediction Transformer (LPT) trains the first loop to build a shared KV-cache, while later loops reuse it and keep only a small window of their own cache to refine predictions.
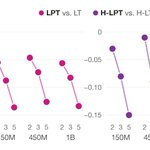
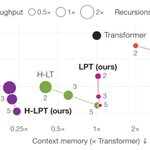
Across 150M-1B models, LPT improves both perplexity and accuracy while using up to 79% less context memory in its hybrid variant.
At 1B, the hybrid achieves 10% lower perplexity than a standard Transformer with five loops, though it uses a lot more inference compute.
alphaxiv.org/abs/2610.02383

Giovanni Monea retweeted

1/ Removing 98.4% of the KV cache in recursions 2 through 5 of a 1B Looped Transformer doesn't hurt accuracy—it improves FineWeb-Edu perplexity from 11.39 to 10.32 and raises 5-task accuracy from 63.4% to 68.2%, using 4.7x less KV memory. 🧵

Giovanni Monea retweeted

[1/5] 🍋 New paper: LEMON, a misbehavior monitor that transfers zero-shot to LLMs it has never seen.
It flags hallucinations & jailbreaks online, token by token, from attention maps, with <10% overhead.
w/ @megamor2 @ffabffrasca @HaggaiMaron
🌐 barsguy.github.io/LEMON_proj…
🧵👇
Yet another banger paper from Nathan :)
It's been a lot of fun hearing day after day about how powerful his new Copy-Paste Language Models are despite their simplicity, and how effective they are at handling long contexts

⌘C ⌘V: Introducing Copy-Paste Language Models!
CPLMs learn to copy tokens better, improving downstream accuracy, CoT, long-context performance, and memory-efficiency for RAG at <3% overhead
PS: they (partially) mitigate the LM head bottleneck
Paper: arxiv.org/abs/2610.19247

Giovanni Monea retweeted
"The Surprising Effectiveness of Shared Memory in Looped Transformers"
Each loop for looped transformers still maintains its own KV cache, which leads to a growing memory.
This paper introduces Looped Prediction Transformers, where the first loop builds a shared KV cache, while later loops reuse it and keep only a small local window.
Surprisingly, sharing memory also improves model quality. At five loops, the hybrid model achieves lower perplexity and higher downstream accuracy than a standard Transformer of the same size, using 76-79% less context memory, though at roughly 3-3.5x the inference compute.
alphaxiv.org/abs/2610.02383

Giovanni Monea retweeted

The Surprising Effectiveness of Shared Memory in Looped Transformers
Pretraining looped transformers to share memory across recursions cuts context memory by 76-79% while improving quality over standard transformers at 150M-1B parameters.
arxivb.org/abs/2610.02383

Giovanni Monea retweeted

In the memory constrained world we are running into, these kinds of insights are key.

⚠️ Stop pretraining your looped Transformer with a separate KV cache per recursion!
In our recent preprint, we show that *memory sharing* not only saves memory but is also a net-positive inductive bias!
Less memory, same flops, higher quality.
🔗 arxiv.org/abs/2610.02383
🧵

⚠️ Stop pretraining your looped Transformer with a separate KV cache per recursion!
In our recent preprint, we show that *memory sharing* not only saves memory but is also a net-positive inductive bias!
Less memory, same flops, higher quality.
🔗 arxiv.org/abs/2610.02383
🧵
So, what does memory sharing bring to the table to *improve* quality?
Prediction recursions attend heavily to the shared memory. Each read sends a gradient signal back to the state recursion.
We find that this "gradient highway" makes the state recursion learn much more.

Very excited to finally share my IBM internship work. It was an intense but rewarding summer (with very nice views), and I had a blast working with my talented collaborators at IBM & Cornell (@KeshavRamji @yelkurdi, @lastrasl @yoavartzi @nthngdy @RamonAstudill12)

Giovanni Monea retweeted

Last Friday we set a (pending) record for the NanoGPT speedrun improving by 11.3% over the previous best time!
It's by far the largest architecture-centric improvement since Dec 2024, and it does not use extra n-gram tricks or more CPU compute
Paper coming soon 😊

Giovanni Monea retweeted

A quick fun paper: We ran State Prediction Separation arxiv.org/pdf/2607.01218 through an optimization process arxiv.org/abs/2609.03807 finding that it works at higher op and yielding "free pause tokens" which allow a transformer to make higher quality inference for (near) free.
Giovanni Monea retweeted
🧵New paper: Matryoshka LM Suites
Instead of training all models of a suite independently, we nest them within a single architecture and train the suite in a single run => much less compute, same performance
Also allows free distillation, better speculative decoding & more 👇

Giovanni Monea retweeted

Almost thinking that Anthro figured out @nthngdy's backprop bottleneck for a while now, and ran with a smaller vocab for better learning...
arxiv.org/abs/2603.10145


✅ Claude's tokenizer reproduction is done!
ctok now exactly reproduces token counts across 500+ natural languages and 22 programming languages, for both tokenizer families.
The vocabulary estimates even went down: just 15k entries for Claude 4.7+ 🤯
🔗 tokenize.rs/claude