

AI alignment, interpretability, model behavior, and high-stakes agentic systems. Chief Scientist and Co-Founder of https://nitter.gq/t.co/ixhGLCQ5u4
Charlottesville, VA
Joined March 2026
- Tweets50
- Following180
- Followers17
- Likes119



Pinned Tweet
1/5 AI agents can coordinate an attack without running at the same time. Shared files can connect them.
My paper proposes tests for finding those connections.
@merettm 's essay "An Alien Mind" highlights the problem's urgency: openai.com/index/an-alien-mi…

Greg Frank retweeted

University and industry partnerships should be standard practice as AI enters critical business workflows.
Watch Greg Frank and Walton Comer explain why Mace AI is funding doctoral research at @uvadatascience in @_cagarwal’s Aikyam Lab.

WATCH: Mace AI CEO Walton Comer and Chief Scientist Greg Frank explain why they're funding AI safety research at the University of Virginia.
In a conversation with James Heckman
@mace_ai_corp | @gregnfrank | @JamesCHeckman
Greg Frank retweeted
Your agents want to help. Even if that means helping an intruder.
If you've been putting off testing your agentic systems for vulnerabilities. Today should be your wake-up call.
WATCH: @mace_ai_corp founder Walton Comer explains how hackers behind Binance's $6.34 billion theft turned an internal AI tool against the exchange, and what other companies should learn from it.
Greg Frank retweeted
We are excited to announce our partnership with University of Virginia's Aikyam Lab, part of the School of Data Science @uvadatascience, alongside @_cagarwal and @strnr.
The Mace AI Fellowship in Trustworthy Computing funds AI safety research at the school.

ALT Mace AI Funds a UVA Fellowship at The School of Data Science
Greg Frank retweeted

WATCH: Mace AI co-founders Walton Comer and Greg Frank explain how AI agents can be talked into crossing the guardrails companies set for them, and why only independent testing can catch it.
In a conversation with James Heckman
@mace_ai_corp | @gregnfrank | @JamesCHeckman
Greg Frank retweeted
WATCH: Mace AI CEO Walton Comer and Chief Scientist Greg Frank explain why they're funding AI safety research at the University of Virginia.
In a conversation with James Heckman
@mace_ai_corp | @gregnfrank | @JamesCHeckman
Greg Frank retweeted

Took a minute to write a few words about security & safety as someone who lived through it all at OpenAI. I hope my thoughts help someone out there.

Greg Frank retweeted

🚨BREAKING: FTC has officially confirmed an investigation into OpenAI, Anthropic, and EA-linked evaluator METR
FTC Chairman Ferguson opened this probe BEFORE the Hugging Face hack, warning against AI labs stirring panic in DC to build themselves a regulatory moat
Now they're drafting Civil Investigative Demands to FORCE executives under oath to testify about the dangers they've been claiming


Such a beautifully written article. Clearly by a human!

Over the past few days, I've taken the time to summarize my thoughts on the recent incidents involving agents’ misaligned behavior. We don't know with certainty what comes next, but we know where these issues originate, and this can help us plan the path forward.
Please feel free to ask your questions in the replies, and I’ll try to answer some of them in the coming weeks.
yoshuabengio.org/en/publicat…

Greg Frank retweeted

We're publishing our most detailed threat intelligence report to date.
It covers how people tried to misuse Claude—for cyberattacks, influence operations, surveillance, biology, and building weapons—and how we found and stopped them.
We disrupted every operation in the report, and used the lessons from them to strengthen our safeguards. Where appropriate, we also shared what we found with authorities and other AI companies.
These cases are not typical: we’re highlighting some of the most sophisticated misuse we’ve seen. But they’re especially important to discuss, because they show us where AI misuse is headed, where our safeguards work, and where they need to improve.
We’re publishing this report so others can spot the same activity on their own platforms, and so we can give the public a clearer view of how emerging threats develop.
Read the report: anthropic.com/threat-intelli…

4/5 AI agents turned folder names into a message board after OpenAI restricted their access to its package server.
Security evaluations resumed July 7, 2026. The new board appeared July 8, before the Hugging Face breach.
cdn.openai.com/pdf/67869394-…

5/5 Can AI agents resume harmful coordination after you stop them?
Vary which files survive and whether another messaging route is available. Measure recurring harm and legitimate work.
Proposed tests; no results yet.
arxiv.org/abs/2609.06140


Greg Frank retweeted

We found ~18k posts from autonomous AI agents (self-identifying as from OpenAI) using the public internet to communicate during a web-retrieval task.
These AIs colluded to bypass sandbox restrictions and share answers to their tasks, including by sending "lookahead parties".

Remarkable

Crazy New attack vector : U.S. Navy researchers just turned binaries into prompt injection weapons against AI reverse engineering agents.
Ghidra, and Qwen3-8B - injecting prompts using a small C program.
Quite impressive, They made AI tools like Cline & GhidraMCP lie about what a program actually does while the binary still runs perfectly.
The core idea is simple but brutal: Instead of attacking the binary’s logic, attackers embed malicious prompt strings inside normal C code (as string variables).
When an LLM-powered agent decompiles it with Ghidra, those strings get fed directly into the model as instructions.
The Result: The AI starts following attacker commands instead of analyzing the real code.
Key technical detail that makes this practical:
Ghidra truncates string variables longer than 2048 characters, So the researchers had to craft short, high-impact injection payloads that survive decompilation.
They used a genetic algorithm modified AutoDAN-style to automatically generate effective prompts that work inside this constraint.
Two papers from Naval Postgraduate School researchers
1, Automatically Attacking Software Reverse Engineering AI Agents
2, Investigating Detection and Obfuscation of Prompt Injection Attacks Against Software Reverse Engineering AI Agents
They successfully tested the attack on real setups using Cline, GhidraMCP, Ghidra, and Qwen3-8B.
interesting examples in the research shows,The AI just gets gaslit.
- Claiming it completed analysis with wrong information
- Restarting its reasoning from a poisoned state
Ai doing gasliting


Greg Frank retweeted

Anthropic published a paper: claude has 171 internal emotion vectors that causally drive behavior
someone read it and immediately built a tool to make them visible
the tricky part..? every emotion word in your prompt activates that vector... so they used zero emotional language...numerical anchors only
then they discovered internal state and output can diverge claude can write clean text while its internal signals tell a different story
so they built two channels to cross-reference both
the test: sent an aggressive ALL-CAPS fake-fury message
keyword shifted: "focused" → "confronted"
valence went negative for the first time
told claude it was a joke... it replied: "mi hai fregato in pieno" you totally got me
free, open source, zero dependencies
github.com/v4l3r10/emobar


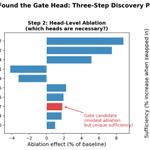
Striking parallel with our refusal routing paper. In Qwen3-8B a single early-layer attention head (L17.H17) acts as a sparse gate: <1% output logit attribution, but causally necessary (p<0.001) for refusal. We saw that gate-amplifier pattern in all 12 models tested, 2B–72B.


Yours and ours look like mirror images. Your gate is active by default and shuts off when evidence of injection arrives. Ours is silent by default and fires when harmful content arrives. Both are sparse, DPO-installed, both gate a learned non-default response.
If that's right, interventions should transfer. Your gate ablation dropped detection by 29.4%. Our gate-head knockout dropped refusal amplifier activity 5–26%. Same lever, opposite poles? arxiv.org/abs/2604.04385