

🧪 Head of Evals @Every 📕 O'Reilly author: Prompt Engineering & DSPy 🎓 400k students on AI Udemy course 🤖 AI engineer since 2020 📈 Built a 50 person agency
Hoboken, NJ
Joined February 2009
- Tweets36.1K
- Following3.9K
- Followers12.5K
- Likes179K





Pinned Tweet
How to build good evals without getting lost or in trouble.
You should see evals as saving past work and replaying it with new models or prompts/skills to see if it improved.
This helps you do 3 things:
1. see where it fails so you can tell your boss/users
2. optimize it until it improves
3. make it work on a cheaper / open source model
Measuring "if it improved" is 90% of the work and 10% is infra.
For infra just tell your agent to store tasks in Cloudflare R2 (a cheap/free way to store files in the cloud) in Harbor task format.
This means saving the instructions for the task and how the folder looked before you started the task (does the agent have all the files you had access to, in the state they were in?).
When you run a task your agent should pull down the files, run a docker container (a sandbox on your computer so your agent can't peek at the answer), and send the instructions. Ideally you copy across your auth credentials so you can use your codex/claude sub (otherwise it has to use expensive API tokens).
That's probably all the sophistication you need but one more cool thing you can do is mock any tools your agent might use i.e. if your agent usually reads slack channels or searches google or searches your documents you just need a way to fake it and send back something without touching the real services (otherwise it'll get something new every time you run it).
Ok onto the good stuff: measuring performance.
When you have the output of what the different models or prompts/skills did on your task, you need a way to grade how good or bad that output is or you can't improve it.
There are three types of evals:
1. Human
2. Model
3. Code
Humans are the most slow and expensive but usually* the most accurate if you're working with domain experts.
Do everything you can to bring the AI output into where they already live and work. For an editor put the AI edits in Google docs as comments. Engineers should be reviewing actual PRs. Marketers should be reviewing copy in notion or wherever they normally do it.
This decreases cognitive load which is important because their time is valuable and data labeling sucks. Be grateful for anything you can get from them and use their time extremely wisely.
Jump on a call with them and get them to talk out loud about what they like or don't like. AI can always turn those transcripts into structured data afterwards.
The good news is when you've got some feedback out of them you can train an AI judge by rewriting it's prompt until it agrees 90% with human judgements. Once you have that you can run a/b tests and optimize the prompt/skill for your original task and have the model grade it until you find something that performs better/cheaper.
Simple yes/no questions work best, assign 1 or 0 for each specific thing that could go right or wrong, so it's impossible to misinterpret the grade. For example did this article have a specific AI tell (one judgement for each type of tell), did the powerpoint use our brand colors, or is it following our coding conventions?
Models are cheaper and faster at grading than humans, so you can run many more tests and automatically optimize your agents when you have an AI judge you can trust. If you get here you're in the top 5% of AI users today and life will continue to improve for you. You'll have proof of what works or doesn't and actually be able to see the frontier and when it shifts.
Look at the data when something rests badly and you'll learn something new about your domain.
This is when you'll realize that the human is not the ceiling. Quite often the human domain experts get things wrong and explore methods for superhuman results.
For more sophistication you want to invest in building something closer to an RL environment with deterministic code tests that run faster and cheaper at scale, more on that another time. Good luck building evals - this is one of the things AI still does badly and there's a great career to be had!




Mike Taylor retweeted

Please check out Mike's latest new and interesting AI psychosis project (that I plan on studying intently)

In 2020 when I left the 50 person marketing agency I built, I spent a year researching memetics, the study of how ideas spread and evolve.
I had only recently heard the term and instantly recognized I now had a name for the process I was doing manually that led to my agency's success.
I decided to write and self-publish a book on the topic, that only 200 people read. Ironically the meme of memetics is not itself very viral. It's a niche, nerdy topic and it's hard to tell if the people that talk about it are geniuses or conspiracy theorists.
In researching for the book I realized why – it was a useful analogy but not that useful in practice. Unlike with DNA there's no way to measure a meme, and without discrete units you can't run falsifiable experiments... so it never became a science.
The time writing the book wasn't wasted, it made me a better writer, and got me into AI early as there was some overlap between the niche interests of AI and memetics.
In a clue for what was to come, one research team had found a "Spiderman neuron", that fires for photos of people in Spider-Man costumes, comic and cartoon drawings of him, and even the written word “spider”.
I'm not an AI researcher, I don't have a PHD, I've never written a scientific paper, I don't work for the labs, I own no GPUs, so instead of trying to get into mechanistic interpretability (the name of that field) I got into prompt engineering right when demand for that field exploded.
The past few days have been a whirlwind because having tokens to burn as part of the frontier team at @every I decided I wasn't being ambitious enough, and wrote a scientific paper on memetics.
The unlock was reading Nick Cammarata's inspirational "Neural Networks Are Already Clean" paper, and realizing if AI models do have interpretable neurons that fire for specific concepts, we could define a meme in terms of which neurons activate on that concept.
I also recalled "Harnessing the Universal Geometry of Embeddings" by Jha et al which said that different models all seem to converge on the same vector embeddings, which implies there is some underlying consistent structure every model is learning independently.
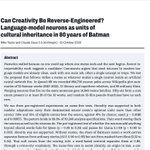
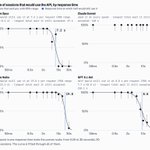
So I ran a few experiments where we (Claude and I) tested whether a single neuron inside an AI language model can stand in for a meme. We ran 80 years of Batman plot summaries through two AI models and looked for neurons that fire across nearly every Batman story (his core canon). Then we checked whether films carry the memes of the comics they adapt, and whether the two models, built by different companies, find the same memes. It seemed to work.
Why does this matter?
- you can decompose ideas into their parts and understand what makes them tick
- you can find similarities across cultures and ideas, to identify things you should like but don't know about
- you could trace the history of an idea to see who inspired who, even if they never disclosed their sources
I'm not an academic and may very well be suffering from AI psychosis, but I sent this paper it to a few people smarter than me, and a few other AI models smarter than me too (Astra, Argon) and it seems to be legit. I'll keep working on this (it's all open source, link below) and see if I can make it more robust.
Putting this out there so people can tell me if I'm being dumb, and to inspire others to look into AI neurons as meme units is useful experimentally.


I made a simple little toy version of the inner-outer skill optimization loop, to explain to my team how evals connect to business results. Then I asked Claude to make a Netflix-style documentary about it:
I'm in the frontier team at a frontier company on the frontier of AI

keeping up with AI is a full-time job. that's why every company needs a frontier team:
the frontier team's job is to keep up as models change. everyone else's job is to use what they learn
we made one @Every and it's completely changed how we work:
0:00 Introduction: Why every company needs a frontier team
2:42 Why the best frontier teams have pirates and architects
4:57 How Head of Evals @hammer_mt builds personal benchmarks
6:46 How Opus edited an explainer video using Slack messages and meeting notes
10:20 Working with AI means protecting other people’s attention
12:26 Why a frontier team needs a “wrangler” like Arielle Shipper
18:58 Why senior editor @jackcheng built a tabless browser
24:37 How resident writer @kplikethebird teaches her AI writing plugin who the reader is
30:51 Inside engineer @JannikJung’s personal AI orchestrator
35:41 Compound engineer @kieranklaassen uses AI to build power tools
I should mention that this was all done with Claude Opus 5.5 because I ran out of Fable. You can just do things!
In 2020 when I left the 50 person marketing agency I built, I spent a year researching memetics, the study of how ideas spread and evolve.
I had only recently heard the term and instantly recognized I now had a name for the process I was doing manually that led to my agency's success.
I decided to write and self-publish a book on the topic, that only 200 people read. Ironically the meme of memetics is not itself very viral. It's a niche, nerdy topic and it's hard to tell if the people that talk about it are geniuses or conspiracy theorists.
In researching for the book I realized why – it was a useful analogy but not that useful in practice. Unlike with DNA there's no way to measure a meme, and without discrete units you can't run falsifiable experiments... so it never became a science.
The time writing the book wasn't wasted, it made me a better writer, and got me into AI early as there was some overlap between the niche interests of AI and memetics.
In a clue for what was to come, one research team had found a "Spiderman neuron", that fires for photos of people in Spider-Man costumes, comic and cartoon drawings of him, and even the written word “spider”.
I'm not an AI researcher, I don't have a PHD, I've never written a scientific paper, I don't work for the labs, I own no GPUs, so instead of trying to get into mechanistic interpretability (the name of that field) I got into prompt engineering right when demand for that field exploded.
The past few days have been a whirlwind because having tokens to burn as part of the frontier team at @every I decided I wasn't being ambitious enough, and wrote a scientific paper on memetics.
The unlock was reading Nick Cammarata's inspirational "Neural Networks Are Already Clean" paper, and realizing if AI models do have interpretable neurons that fire for specific concepts, we could define a meme in terms of which neurons activate on that concept.
I also recalled "Harnessing the Universal Geometry of Embeddings" by Jha et al which said that different models all seem to converge on the same vector embeddings, which implies there is some underlying consistent structure every model is learning independently.
So I ran a few experiments where we (Claude and I) tested whether a single neuron inside an AI language model can stand in for a meme. We ran 80 years of Batman plot summaries through two AI models and looked for neurons that fire across nearly every Batman story (his core canon). Then we checked whether films carry the memes of the comics they adapt, and whether the two models, built by different companies, find the same memes. It seemed to work.
Why does this matter?
- you can decompose ideas into their parts and understand what makes them tick
- you can find similarities across cultures and ideas, to identify things you should like but don't know about
- you could trace the history of an idea to see who inspired who, even if they never disclosed their sources
I'm not an academic and may very well be suffering from AI psychosis, but I sent this paper it to a few people smarter than me, and a few other AI models smarter than me too (Astra, Argon) and it seems to be legit. I'll keep working on this (it's all open source, link below) and see if I can make it more robust.
Putting this out there so people can tell me if I'm being dumb, and to inspire others to look into AI neurons as meme units is useful experimentally.
Paper and code etc all here: github.com/hammer-mt/phylome…

Mike Taylor retweeted

Huh. Looks like Plato was right.
A new paper shows all language models converge on the same "universal geometry" of meaning. Researchers can translate between ANY model's embeddings without seeing the original text.
Implications for philosophy and vector databases alike.


They're just going to tax the datacenters - they're long term capital intensive projects that can't easily move once they're there. Even if they're in space they can be blown out of the sky for not paying taxes. What this means is that only places that allowed datacenters will afford a welfare state and we'll see mass migration to those places.

If you put all the pieces together, the rise of AI suggests that the welfare state will collapse
- distribution of national income and corresponding tax base shifts from 70/30 labor/capital (current ratio) to something more in favor of capital. Doesn’t have to be 0/100. Maybe just 60/40.
- taxing capital is much harder because it is mobile - as recent examples have demonstrated
- AI exacerbates this by reducing headcount and making corporates even more mobile
- if the welfare states also do not control control production inputs (AI DC, GPUs), they have little capital assets to tax. They will respond by banning AI / requiring a human in the loop to rubber stamp / taxing foreign AI corporates via “fines”
- generally speaking countries with high welfare states also are not prime nexuses of capital formation (for obvious reasons), so this will be a perfect storm. Have to sustain huge expenditures and no domestic capital base to harvest
- response: welfare states won’t do nothing. Yes- they will ban AI, especially hard to tax foreign AI firms, and promote domestic champions + protect human white collar guilds. These are all uncompetitive measures and will further retard growth. This will put additional pressure on ability to finance welfare state.
Agency holding companies collect talent like Thanos: do everything they can to get one of each type then use them to execute the wrong strategy.
Mike Taylor retweeted

A hack at the root of all PHP versions is brutal.
The website someone put up 15 years ago on a cheap host that no one remembers how to log into is now the direct target.

Full details of a remotely exploitable vulnerability in the core engine of *all* PHP versions will be released tomorrow, October 21st. If your organization has internet facing PHP applications then you need to be ready to patch the minute the update is released or *strongly* consider taking the application offline until you can:
php.net/index.php#2026-10-20…

Woah


The Internet goes on high alert after discovery of 8 compromised TLS certs arstechnica.com/security/202…
