Just dropped a preview of some of the latest work I'm doing @precursorlabs to distill personal judgment into local models continuously.
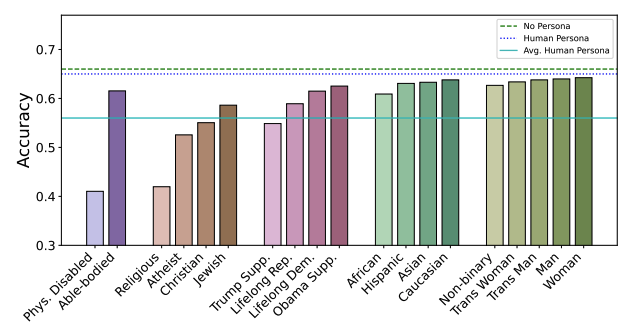
Our main finding is that models are overall pretty bad at predicting the decisions you actually make on a day to day basis.
If you had a local "decision model" that was able to actually make the decision you would, given the same context, you could move 1000x faster.
There seems to be consistent learning as a function of data, pointing to something akin to local scaling laws!


Current Pareto curve for @ArtificialAnlys intelligence and @tinkerapi training cost. Has been very useful for us internally!
I predict we'll see >60 and <$1 by end of next year. It's a wonderful time to be working on applied AI.