iGent AI (@iGent_AI) profile picture

Engineering Intelligence

London, England
Joined September 2024
Photo by iGent AI (@iGent_AI)Photo by iGent AI (@iGent_AI)Photo by iGent AI (@iGent_AI)Photo by iGent AI (@iGent_AI)Photo by iGent AI (@iGent_AI)Photo by iGent AI (@iGent_AI)Photo by iGent AI (@iGent_AI)Photo by iGent AI (@iGent_AI)Photo by iGent AI (@iGent_AI)Photo by iGent AI (@iGent_AI)
Two papers. Post-quantum encryption and RSA. We did not break either. Written with Maestro in five days on @claudeai Fable 5.1. They did not co-author them.
Post-quantum encryption and RSA. The hardness numbers next to both are the cheapest attacks anyone has written down. They are not the cheapest attacks those methods themselves allow. We computed the second number for both. We did not break either.
118
We have found Sonnet 4.6 to be a substantial upgrade over Sonnet 4.5, approaching Opus performance, and tackling large scale, long horizon tasks such as iteratively improving green field codebases:
This is Claude Sonnet 4.6: our most capable Sonnet model yet. It’s a full upgrade across coding, computer use, long-context reasoning, agent planning, knowledge work, and design. It also features a 1M token context window in beta.
5
467
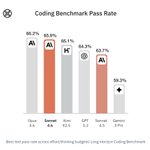
We’ve been testing Sonnet 4.6 and it has been potent in our agent, Maestro. Our primary eval is to implement a long list of features across a diverse set of use cases, iteratively across codebases, building on prior work. The result: it completed features faster, cheaper, and with a higher benchmark pass rate.
5
3
2
5
1,267
The time to complete features has dropped from 6 minutes with Sonnet 4.5 to 3.1 minutes with 4.6—nearly double the speed. On the same tests, GPT 5.2 took 10.4 minutes and Kimi K2.5 took 8.7 minutes. This is blazing fast.
1
1
5
219
This increase in speed and reduction in tokens required per feature is also reflected in the cost per feature implemented, with Sonnet 4.6 averaging $3.84 while Opus 4.6 costs $7.92, Gemini 3 Pro $8.28, and GPT 5.2 $9.43. It’s clear why we’ve switched to this as our main orchestration model and code producer—the progress is incredible.
1
5
133
We're excited to share that our agent, Maestro, drafted solutions to all 12 problems from ICPC 2025 World Finals in ~2 hours - using current models, no human involvement, no internet access. We deeply respect the human teams' extraordinary dedication. Note: no official validation
1
4
4
11
1,472
Important context: Solutions tested only on sample inputs (no official judge access). We invite the community to validate, learn from, and build upon this autonomous exploration. The ~2 hour timeline using current generation models shows Maestro’s algorithmic capabilities.
1
252
This represents an demonstration of what Maestro (iGent.AI) can achieve autonomously in algorithmic problem-solving. We honor the years of dedication ICPC participants invest. Join us in examining these solutions and advancing our collective understanding!
211
Anthropic just made *the* LLM release we have been waiting for - two massive context Claude Sonnet models, handling up to 1M input tokens. These are the models that we used with our Maestro system @iGent_AI to build large, complex software, like a Redis-compatible database written in Rust, written entirely by AI nitter.gq/MSzummer/status/195385…
Claude Sonnet 4 now supports 1 million tokens of context on the Anthropic API—a 5x increase. Process over 75,000 lines of code or hundreds of documents in a single request.
1
1
2
354
Tired of toy AI demos that fizzle in production? iGentAI built Ferrous: A Rust Redis-compatible server outperforming Valkey. 35KLOC, 100% test passing, beats benchmarks. Zero human code. Built in 70 hours of part-time direction. Toys vs. tools—here's the proof.
1
4
3
13
1,812
Developers: Direct AI like a senior team across projects. CTOs: Accelerate from months to hours. Agentic Software Engineering is verifiable, deployable, outperforming. What challenge will you tackle? Reply below.
1
189
Clone Ferrous, run tests, and benchmark with your Redis clients. When AI builds systems surpassing human alternatives as a "side project," software development enters a new era. Join us: igent.ai/
1
171
@Anthropic reports Claude 4 models are 65% less likely to use shortcuts on agentic tasks. Our evaluations confirm this—Claude Sonnet 4 consistently understates feature completeness rather than overstate success. This translates to more reliable AI assistance through Maestro.
1
1
4
276
We've integrated Claude Sonnet 4 into Maestro, and the results are transformative. As our evaluations show, it maintains higher code quality even as project complexity grows. Combined with its new extended thinking capabilities, Maestro delivers an unmatched AI engineering experience. Signup at igent.ai/
1
1
1
270
You can also find out the full details on Sonnet 4.0 VibeCodeBench performance at igent.ai/sonnet4eval.pdf
1
230