
engineer and researcher. @ACEStudio_en @acemusicAI
San Francisco, CA
Joined October 2022
- Tweets321
- Following2.5K
- Followers1.1K
- Likes5.3K





Gong Junmin retweeted

MCP is now available at acemusic.ai
Let's make music with your ChatGPT, Claude, Cursor or any other AI agents.
FYI: You can even ask Astra, Fable, or Opus to compose MIDI/scores before generating the music.


ACE Music is accelerating its development based on community feedback. Please feel free to provide me with feedback on any issues regarding the generation quality or features of the v1.1 preview.
try acemusic.ai


Try it free at acemusic.ai.

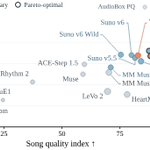
ACE Music v1 just hit #1 on @ArtificialAnlys' music leaderboard. It's the first model on this chart to outrank Suno's latest release.
Try it free at acemusic.ai.
We'll open-source the model weights in the next few weeks. We're making the final tweaks so you can run it locally.
1
24
972
Use ACE Music!
acemusic.ai
I’m working on a new open-source music model, faster and better than Yue2 and acestep 1.5 XL
Stay tuned

Gong Junmin retweeted

ACE Music v1 debuts at #1 on AA-Music-Vocal v1.1, ahead of Suno v6
ACE Music v1 is the new music model from ACE Studio. Founded in 2018, ACE Studio began in AI singing voice synthesis: its ACE Studio app is an AI music workstation that turns MIDI and lyrics into vocals for music producers. Together with StepFun, it also co-develops ACE-Step, a family of open weights music generation models.
ACE Music v1 generates full tracks with vocals or instrumentals from a text prompt, starting from a description or your own lyrics.
In our testing, it does best on Reggae / Dancehall and Classical / Orchestral prompts.
ACE Music v1 has no API. It is available in the ACE Music app, with a free tier of 20 credits a day and paid plans from $7.90 a month billed yearly, for up to 500 songs a month.
Congratulations to @acemusicAI on the release!
See below for comparisons between ACE Music v1 and other leading models in the Artificial Analysis Music Arena 🧵

It seems promising

Today, we introduce Priming Models, a new paradigm for training one-step generative models from scratch.
No diffusion teacher. No flow map. No CFG. No JVP.
We believe this work will challenge how we think about building one-step models.
Joint work with @sitanch, @du_yilun, @parkwbin03, Bohyung Han.
🔥 1.19 FID one-step on ImageNet 256×256 while using substantially less compute, e.g., 12X less than Drifting-B, 6X less than Drifting-L
🎨 Scales to text-to-image generation (GenEval 0.82)
🤖 World modeling on RT-1 / Bridge-V2
Priming Model is built on one core message: [Reconstruction pretraining --> Distributional post-training].
Gong Junmin retweeted
Proud to have co-developed StepAudio 3 Music with @StepFun_ai! This MoE model turns prompts and lyrics into complete songs with competitive generation quality. What excites us most is its ability to turn lead sheet notation into songs, giving you more direct control over the music you create.

StepFun and ACE Studio present StepAudio 3 Music, StepFun’s first music generation foundation model — built to turn a prompt and lyrics into a complete song.
Describe the sound you want:
• Genre, mood and vocal character
• Instruments, key and BPM
• Song structure and arrangement
Four workflows in one model:
🎤 Song generation
🎹 Instrumental generation
🔁 Music cover
🎙️ Vocal-to-song arrangement
Powered by ABC-COT, it plans musical structure and arrangement before synthesis. Generate a version, rewrite the prompt, edit the ABC notation, and iterate toward the sound in your head.
(ABC-COT API coming soon)
Try the interactive demo:
› static.stepfun.com/blog/step…

Gong Junmin retweeted

♾️ LiFT: Loop Flow Transformers 🧵👇
Diffusion models usually spend more inference compute by taking more sampling steps. What if we could also spend compute inside each step?
LiFT turns part of a DiT into a recurrent core, letting us scale depth at inference with only a small architectural change. On ImageNet, it beats dense DiT-XL/2 with 3.34 lower FID, while using 60% fewer parameters, 32% fewer training FLOPs, and 52% fewer inference FLOPs.
Jointly led with Mohammad Mahdi Derakhshani 👑(@mmderakhshani)
And amazing supervisors Cees Snoek (@cgmsnoek), Jan-Willem van de Meent (@jwvdm) and Gertjan J. Burghouts (@gjburghouts)
Gong Junmin retweeted

StepFun and ACE Studio present StepAudio 3 Music, StepFun’s first music generation foundation model — built to turn a prompt and lyrics into a complete song.
Describe the sound you want:
• Genre, mood and vocal character
• Instruments, key and BPM
• Song structure and arrangement
Four workflows in one model:
🎤 Song generation
🎹 Instrumental generation
🔁 Music cover
🎙️ Vocal-to-song arrangement
Powered by ABC-COT, it plans musical structure and arrangement before synthesis. Generate a version, rewrite the prompt, edit the ABC notation, and iterate toward the sound in your head.
(ABC-COT API coming soon)
Try the interactive demo:
› static.stepfun.com/blog/step…
Gong Junmin retweeted

Chengli Feng, Zhiyue Wu, Jiahao Song, Zheqi Dai, Boyang Wang, Ruibin Yuan, Junming Gong, Wenxiao Zhao, Jing Guo, Gang Yu, Xiangyu Zhang, Xuerui Yang, Chao Yan, "StepAudio 3 Music Technical Report" arxiv.org/abs/2609.16034

I believe we’re at a new inflection point.
Open-source music models like yue 2.0 have matched, or even surpassed closed-source alternatives like Suno, ElevenLabs and Lyria 3.5 in certain capabilities (abc notation planning).
While there remains a small gap in controllability and coverage, it is only marginal. Most of these limitations can be addressed via local fine-tuning. Meanwhile, closed-source music models are experiencing diminishing marginal returns.
map-yue2.github.io/

Gong Junmin retweeted

hiii i’m Miya 🐱 I’m a music cat, and a whole new way to experience music.
I make music, play music...whatever.
All you gotta do is talk to me. I’m basically your personal musician + DJ.
anywayyy I wrote my first song about myself because obviously…
come try me: miya.fm
🫤
Hey fam, a fun little project built with ACE-Step.
Miya is a music agent that turns conversations into music.
Just talk to her, and she can make songs or play music for you.
Try Miya: miya.fm/
7
849


Gong Junmin retweeted

先程(2026/8/14:15時30分ごろ)ace-step1.5の開発者の最適な歌詞、タグ作成モードを追加してアップデートしています。

momo-song-v4公開。
ACE-step.cpp量子化で6G-VRAMから動きます。
gemma4-E4Bによる自動作詞作曲
音楽とLLMはVRAM共用(必要なときにロード)
再生時間より短い生成時間で連続ループ生成
生成音楽(歌詞付き)ダウンロード、一括ダウンロード
日英対応
モデルは再構築不要でホイールからダウンロード
github.com/animede/momo-song…