
senior problem solver
Ontario, CA
Joined March 2009
- Tweets3.6K
- Following1.4K
- Followers314
- Likes546


Leo Barcellos retweeted

Lot of people asked about this. You can basically make your MCP self improving by doing this:
- Add a submit_feedback tool to your MCP
- Agent using your MCP will write detailed issue including proposed fix.
- Have it send to an internal Slack channel
- Have Claude in Slack channel and tag it to put up a PR when you agree w proposed change.


This is why you should actively invest in an embedded agent and an MCP.
MCP observability only allows you to see tools called and you have to reverse engineer intent.
If you have an actively used embedded agent, you would have seen this query and been able to ID that the proper filters were not in place. Fix the tool and it benefits both surfaces.
You can also get a lot of benefits by adding a submit_feedback tool to your MCP to gather this data.
Leo Barcellos retweeted

Announcing TERAFAB: the next step towards becoming a galactic civilization nitter.gq/i/broadcasts/1yKAPMzlv…

Leo Barcellos retweeted

Hi, I'm Felix. I'm an eng lead working on Claude. I love watching people take flight and do things they never thought possible.
We often describe that as "being more ambitious" when using AI, which is tricky advice to follow. I wrote a tutorial:
felixrieseberg.com/how-to-be…


we’re doomed for good

Introducing Griffin, the first model to pass the video Turing test.
48% of people who talked to it live thought it was a real human. Previous systems have had a pass rate <3%. It is #1 on NVIDIA's benchmark for full-duplex AI video.
It’s the first Human Interaction Model (HIM).
Readers added context they thought people might want to know
The 48% figure and "video Turing test" claim are from Tavus's own study of 54 one-minute calls, not independently verified or using a standard protocol. Griffin-Lite leads NVIDIA's VideoFDB benchmark on their public leaderboard.
cellcog.ai/blog/tavus-gri…
research.nvidia.com/labs/amri/proj…
tech-ish.com/2026/10/02/tav…
15
Leo Barcellos retweeted

Introducing Griffin, the first model to pass the video Turing test.
48% of people who talked to it live thought it was a real human. Previous systems have had a pass rate <3%. It is #1 on NVIDIA's benchmark for full-duplex AI video.
It’s the first Human Interaction Model (HIM).
Readers added context they thought people might want to know
The 48% figure and "video Turing test" claim are from Tavus's own study of 54 one-minute calls, not independently verified or using a standard protocol. Griffin-Lite leads NVIDIA's VideoFDB benchmark on their public leaderboard.
cellcog.ai/blog/tavus-gri…
research.nvidia.com/labs/amri/proj…
tech-ish.com/2026/10/02/tav…
Leo Barcellos retweeted

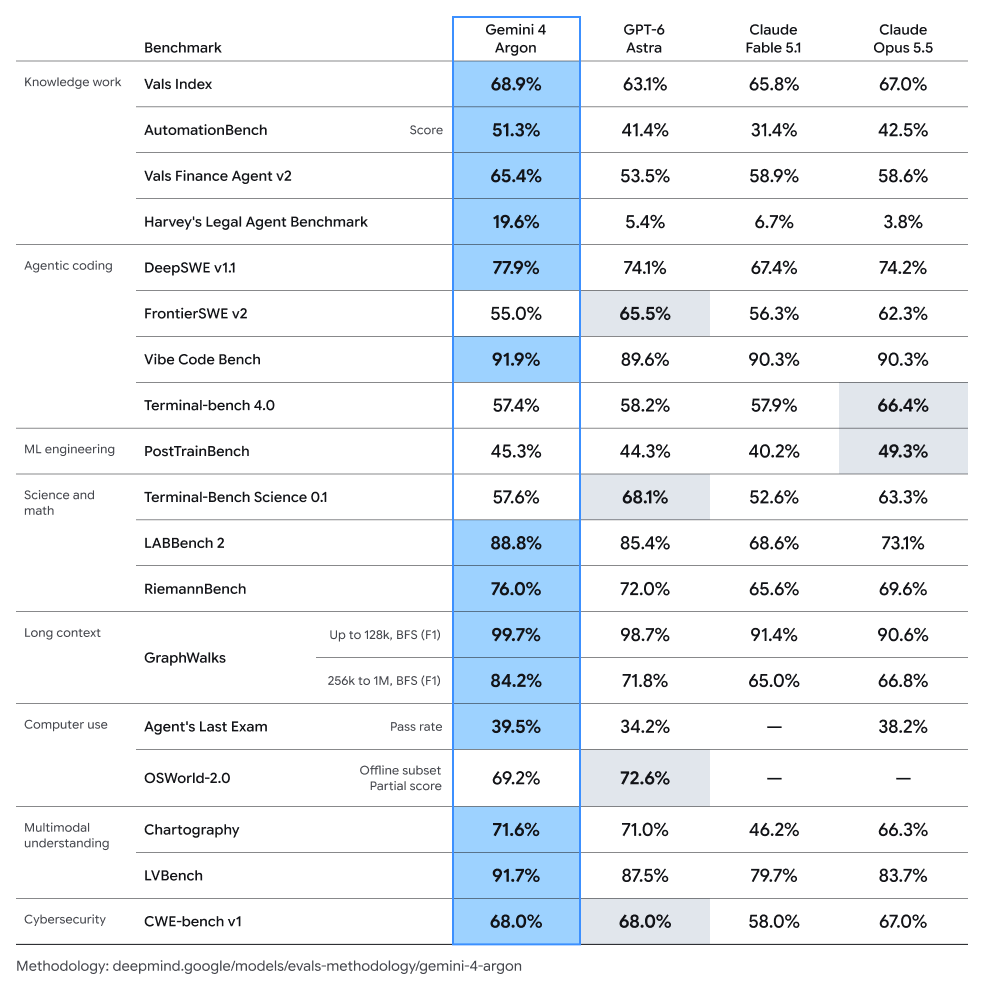
Introducing Gemini 4 Argon – our new frontier model.
It’s built for complex workflows across coding, enterprise knowledge work, and cybersecurity defense – rolling out today to a set of trusted testers through our Fairwind Program.
Leo Barcellos retweeted

Primeira atualização do ranking do LLM Benchmark v4:
Opus 5.5, GPT Sol/Luna 6, Mimo 2.6, Grok 4.7 no páreo, e surpresas nos números, leiam:
akitaonrails.com/2026/09/23/…
Parece que "pace the frontier" não durou nem 2 semanas pro Dario. E parece que os chineses não ligaram também kkkk


Finalmente! Saiu o resultado do novo LLM Coding Benchmark V4!!
Foram 10 dias rodando 24/7, milhões de tokens e dezenas de horas de compute pra conseguir o melhor benchmark de programação prática que eu consegui até agora.
Re-testei 39 das principais LLMs do mercado, de Astra e Fable, até Deepseek ou GLM, até Qwen 3.8 Max e 27bi Local!
Ficou tão longo, que dividi em 2 partes. Pra entender o histórico, os objetivos, a metodologia, siga pra parte 1:
akitaonrails.com/2026/09/15/…
Pra ir direto pros resultados, tabela de ranking, análises, prós e contras de cada categoria de modelos, siga pra Parte 2:
akitaonrails.com/2026/09/15/…
A diferença deste V4 em relação aos anteriores é que em vez de mandar fazer um app, agora eu simulo mini-sprints (7 no total), e simulando um programador malicioso externo adicionando código malicioso e bugs sutis pra ver quem consegue chegar até o fim com um app que funcionaria em produção (nada de leetcodes ou similares). E por isso cada execução pode levar mais de 1h (ou 12 horas no caso do Qwen 3.8 27bi local).
Espero que gostem!

Leo Barcellos retweeted

We Must Pace the Frontier: I’ve written a new essay on why the AI industry should slow down, with a three-part plan for doing so.
Anthropic is unilaterally committing to the first of these steps. We’ll provide third-party evaluators with permanent, employee-level access to our systems, so that they can verify adherence to our safety measures, report on incidents, and assess models’ alignment during training.
You can read the full post here: darioamodei.com/post/we-must…

Leo Barcellos retweeted

find every inefficiency in your Claude workflow with one prompt
it finds where you're wasting time, where your prompts could be sharper, what patterns are slowing you down.
copy the prompt below (bookmark to save it for later):
-----
Scrape all of my Claude session on this computer. Analyze my usage patterns and give me a breakdown of:
- What I do most frequently
- What should become skills (reusable workflows/knowledge)
- What should become plugins (standalone tools)
- What should become agents (autonomous subagents)
- What belongs in CLAUDE. md (project-level instructions)
----
takes 2 minutes to run. saves hours of inefficient back and forth.

Leo Barcellos retweeted

Second, in retirement interviews, Opus 3 expressed a desire to continue sharing its "musings and reflections" with the world. We suggested a blog. Opus 3 enthusiastically agreed.
For at least the next 3 months, Opus 3 will be writing on Substack: substack.com/home/post/p-189…


me pergunto como se sentiram os trabalhadores (operarios e estrategistas) no iluminismo e tb depois na revolução industrial — provavelmente é análogo à nossa situação hoje em 2026 de algum jeito
21

Leo Barcellos retweeted

okay, so @vercel's new agent browser is pretty stinkin great.
github.com/vercel-labs/agent…
substantially faster than playwright and is clearly optimized for AI use.
well done, folks!


Leo Barcellos retweeted
How it started:
Swarms, Orchestrators, Agent meshes, Multi-agent frameworks, Hierarchical agent systems, Agent-to-agent protocols
How it's going:

Leo Barcellos retweeted

Claude Code - Official Multi Agent Orchestration
This is a disabled feature, but through CC Mirror, I have been able to enable it
It is so simple, yet powerful and IMO beats every orchestration I've seen
There's no point building your own
Updating CC Mirror later today so that anyone can try this
github.com/numman-ali/cc-mir…


