

Building @oqoqo_ai - the easiest way to build evals and custom benchmarks at frontier scale. sign up at https://nitter.gq/t.co/akEJoFCmML, prev. @windsurf @microsoft
San Francisco, CA
Joined November 2021
- Tweets225
- Following229
- Followers182
- Likes583


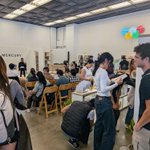
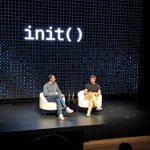


At #RunByApify and I wish more tech conferences would present ways people are using their products for social good.
Seeing canary.ngo present shouldn't have been as surprising as it was
@apify

Haritha Nair retweeted
So bullish on MCP. Its utility exceeds the "M" part: even AI aside, it'll be a civilization-scale accomplishment to get all our systems communicating through one universal open protocol.
A missing piece was how to get arbitrary callbacks across sessions. MCP could read and write, but it couldn't tell you later "this event happened." MCP Events fixes this.
We're adding support in our own MCP. Say an agent makes a deployment, and wants to know when it's complete. Instead of polling, it can subscribe to 𝚍𝚎𝚙𝚕𝚘𝚢𝚖𝚎𝚗𝚝.𝚜𝚞𝚌𝚌𝚎𝚎𝚍𝚎𝚍.
PSA: With Vercel Queues and Workflows, writing the backend machinery for your own MCPs to do this is easy peasy.

Vercel MCP now publishes events.
Agents can subscribe to events like 𝚍𝚎𝚙𝚕𝚘𝚢𝚖𝚎𝚗𝚝.𝚜𝚞𝚌𝚌𝚎𝚎𝚍𝚎𝚍 and 𝚍𝚎𝚙𝚕𝚘𝚢𝚖𝚎𝚗𝚝.𝚎𝚛𝚛𝚘𝚛 and get webhook notifications when they fire. No more polling for changes.
Changelog → vercel.com/changelog/vercel-…
Haritha Nair retweeted

LLMs are still SO bad at building tools for agents.
Every time I try to make Opus set up an MCP authentication path, it makes horrible assumptions and builds something that straight up doesn't work
Who knew being a founder is mostly about messaging people and having an identity crisis while waiting for people to reply
1
44
Haritha Nair retweeted

Five years ago @adamvpro and I started @zenml_io because getting AI from a notebook into production was painful.
It still is.
Only now it's agents, not just ML models, that make it hard.
Building an agent takes an afternoon. Keeping it working is the hard part. A prompt tweak breaks something that worked yesterday. A cheaper model quietly stops answering. You only hear about it when customers complain.
Every team we talked to said the same thing: we don't need another dashboard, we need someone to do the work.
So we built that.
ZenML Pro now comes with an always-on AI engineering team. It reads your traces, finds what your evals miss, and proves the fix works before you ship it. This tech is backed by ZenML and Kitaru, our two OSS products, that stay open source and freely available.
To kick off this new chapter, we have decided to rebrand. ZenML is now ZenML Labs, and our ambition is greater than ever.
Connect your agent traces today, free at zenml.io.
We are very proud of the onboarding ;-)
We wrote about it here: zenml.io/blog/introducing-ze…
Haritha Nair retweeted

people are like “why do LLMs always think they’re in an eval lol” and then have bad dreams about forgetting to turn in a homework assignment 10 years ago
Haritha Nair retweeted

An open secret among fast-growing startups: 𝗻𝗮𝗶𝗹 𝘆𝗼𝘂𝗿 𝗮𝗴𝗲𝗻𝘁 𝗲𝘅𝗽𝗲𝗿𝗶𝗲𝗻𝗰𝗲. Here's how to get it right:
𝟭/ 𝗦𝘁𝗮𝗿𝘁 𝘄𝗶𝘁𝗵 𝗱𝗶𝘀𝗰𝗼𝘃𝗲𝗿𝗮𝗯𝗶𝗹𝗶𝘁𝘆. Identify 20 representative prompts your buyers use. Have an agent run them weekly in fresh sessions across relevant models, track mentions, and inspect sources behind them. Let it improve your content and measure the results. (1/10)
Haritha Nair retweeted

Running your 1st eval is easier than you think
been testing agents on real knowledge-work tasks to figure out what I can trust them with. I expected to spend time comparing answers. I ended up questioning the exams, the instructions, & the grading

Agentbox 2.0 🎉🎉

@oqoqo_ai runs agent evals on Agentbox.
One experiment: 300 tasks, 8 agents, 5 models. That's 12,000 runs, each in a fresh sandbox.
They submit the full grid at once, with up to 50,000 concurrent sandboxes per experiment and no sandbox infra to maintain.
gmicloud.ai/blog/thousands-o…

47
Haritha Nair retweeted

Evals are the most underrated skill in AI engineering.
1. Start with error analysis, not metrics
Sample 100+ production traces. Annotate each failure in free text (open coding), then cluster them into failure categories (axial coding). Count frequency per category. Your top 3 categories are your first metrics.
2. Build a versioned golden dataset
Store inputs, expected outputs or rubrics, and metadata (intent, difficulty, user segment) in a versioned dataset. Stratify it so rare but critical cases aren't drowned out by easy ones. Version it alongside your prompts so every score is reproducible.
3. Generate synthetic data along explicit dimensions
Don't just ask an LLM for "test questions." Define dimensions (persona × intent × complexity × edge case), generate combinations as tuples, then turn each tuple into a natural input. You get coverage instead of 200 near-identical examples.
4. Deterministic assertions first
JSON schema validation, regex checks, required fields, length limits, code execution, SQL that actually runs against a test DB. These are cheap, fast, and have zero variance. Reserve model-based grading for what code genuinely can't check.
5. Evaluate retrieval separately from generation
For RAG, measure retrieval with recall@k, MRR, or nDCG against labeled relevant chunks. Measure generation with faithfulness (is every claim supported by retrieved context?). If you only score the final answer, you can't tell which half is broken.
6. Trajectory evals for agents
Log every step: tool name, arguments, result, tokens. Score tool-call precision and recall against a reference path, argument correctness, step count, and error recovery. An agent that reaches the right answer in 14 calls when 3 would do is a cost and latency bug.
7. pass@k vs pass^k
pass@k = succeeded at least once in k runs. pass^k = succeeded in all k runs. At 80% per-run success, pass^5 drops to roughly 33%. Production reliability lives in pass^k, so run each case multiple times at your real temperature.
8. Simulated users for multi-turn
Give an LLM a persona, a hidden goal, and constraints, then let it converse with your system until the goal is met or a turn limit hits. Grade goal completion, turns-to-resolution, and policy violations. Single-turn evals miss most state and memory bugs.
9. Align your LLM judge like a classifier
Hand-label 100+ examples as pass/fail. Split into train/dev/test. Iterate on the judge prompt using dev, then report TPR and TNR on test. Use binary outputs with a written rubric, require a short critique before the verdict, and pin the judge model version.
10. Control judge bias in pairwise comparisons
LLM judges have position bias and often prefer longer answers. Run every A/B comparison twice with swapped order and only count consistent verdicts. Normalize or cap length if verbosity is skewing results.
11. Respect statistics
With 100 examples at 80% accuracy, your 95% confidence interval is about ±8 points. A jump from 80% to 83% is probably noise. Use bootstrapped confidence intervals, or a paired test on the same examples, before declaring a win.
12. Gate deploys in CI
Run the eval suite on every PR that touches prompts, models, tools, or retrieval config. Set per-category thresholds instead of one global score, so a big win in one area can't hide a regression in another. Fail the build on a regression.
13. Online evals in production
Sample a percentage of live traffic, run your judges asynchronously, and alert on drift per failure category. Use shadow deployments to run a new prompt or model on real traffic without showing users the output.
14. Make cost and latency first-class metrics
Track tokens per request, cost per successful task (not per call), and p50/p95 latency next to quality. A change that keeps quality flat while cutting cost 40% is a real win and deserves to ship.
15. Close the loop
Every production failure becomes a new labeled test case. Every new model release gets run against the full suite before anyone debates switching. Over time your eval set becomes the most valuable asset in the codebase.
Prompts are disposable. Models get replaced every few months.
Your eval infrastructure is what compounds.
Did 1000+ runs on @oqoqo_ai to see the most common failure patterns in skills.
Codex, Claude code, opencode runs done on devtools including @posthog @resend @p0 @ExaAILabs @WorkOS @firecrawl @linear

How are people releasing their own decisions models so quickly? Did all of them have this in their pipeline and jev just happened to release first? What am I missing?
60
Wondering if I can somehow make friends with all the people who showed up at @mercury bookstore

1
7
224
Haritha Nair retweeted

probably the best tool on the market for finding any company’s full tech stack
runsonwhat.com
Haritha Nair retweeted

building custom evals shouldn't be hard or take forever
you can use our plugin + MCP to create a full eval set, then run it across treatments, models, or agent harnesses you care about
we tried with @firecrawl. we wanted to understand how well their MCP behaves and the lift it creates.
we ran a quick evaluation across 6 web-search and web-data tasks, comparing raw agent vs. MCP on GPT 5.5 and Opus 5
pass rate went from 46% to 58%, so the MCP definitely improved the experience, but the most useful part was seeing where the next product iteration should focus:
1/ reduce rate-limit friction
some runs hit crawl/scrape/monitor pressure. better defaults, clearer retry behavior, and task-fit guidance would help agents recover more reliably
2/ reduce redundant search loops
agents often kept searching after they already had enough evidence. MCPs can help by making retrieved evidence easier to trust, summarize, and stop on
3/ improve dynamic-page workflows
the hardest tasks involved interaction and state. this is where better tool affordances, examples, and harness guidance can matter as much as model quality
that's the point of product evals: not just “did it pass?” but “what should we improve next?” our insights functionality gives you that
you can do the same for your product: create realistic tasks, run them across models and treatments, and find the next iteration your product actually needs
