
stay hydrated
Amsterdam
Joined January 2017
- Tweets179
- Following257
- Followers447
- Likes1.1K


3) Frozen feature augmentation especially excels in transfer to small datasets. On transferring ViT-L + JFT and ViT-L + Siglip, to 7 downstream fewshot datasets, we observe significant improvements over linear and MAP classifiers.

2) We investigate 18 different image augmentations but applied on top of features. Interestingly, simple pointwise augmentations such as brightness, contrast and posterize provide consistent improvements over just training a MAP Head.

Training a simple classifier on top of "frozen features" from large vision models is now common and powerful. In our CVPR 2024 paper (arxiv.org/abs/2403.10519), we show that just applying simple augmentations on such frozen features can improve few-shot classification.

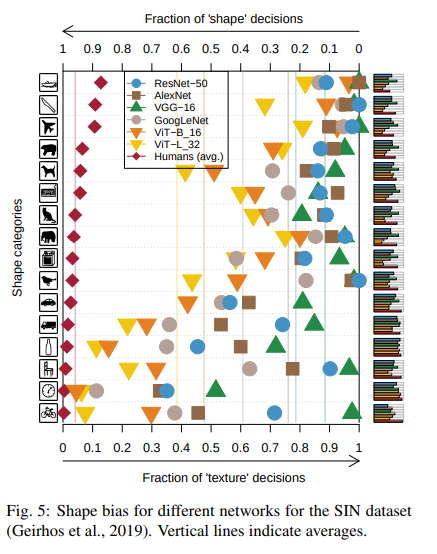
the tl;dr is that humans seem to make decisions based on shape, while traditionally networks on texture. for eg, in the image below, humans classify img c) as cat while networks classify this as an elephant.

this work by Geirhos also shows that standard architectures when trained with large amounts of data closes the gap on a number of metrics:
openreview.net/attachment?id…

Though we did not disentangle architecture vs data in this work, there is evidence to suggest it is both architecture and data. For example, this work by Tuli et al (arxiv.org/abs/2105.07197) shows ViTs have more shape bias than ResNets trained on the same dataset (ImageNet-21K).
Our previously observed phenomena where better classifiers achieve worse perceptual similarity (openreview.net/forum?id=qrGK…) is consistent with ViT-22B and remains a mystery. 🤔

