


Mike Pollard retweeted

we're helping a customer spending $60k/mo move from OpenAI & Anthropic to open source models
they use almost every model offered by the labs, so we needed to find replacements for all of them
after generating evals, this is what we landed on
new cost: $12k/mo, 80% savings

Mike Pollard retweeted

META BRAIN MODEL | NEW AGENT BILL | FABLE BACK SOON? nitter.gq/i/broadcasts/1nxeLLOWp…
Mike Pollard retweeted
HALO is on the front page of HN :)


Mike Pollard retweeted
We’re releasing HALO Desktop 😇
it's the best way to find bugs in your agents
import traces from Langfuse or Arize & have HALO create a report with failure modes
give the report to your favorite coding agent to build it
runs locally on your machine. 100% free and open source
Mike Pollard retweeted

Shout out to @samhogan @AmarSVS @francescodvirga @atbeme @mikepollard_dev and the rest of the Inference dot net team

Mike Pollard retweeted
We're releasing Schematron V2, a family of Specialized Language Models for converting messy HTML to structured JSON
frontier performance at 1/10th the cost
Schematron V2 was designed in partnership with some of the largest web-scraping companies in the world to meet the demands of their heaviest workloads
Schematron-V2-Turbo and Schematron-V2-Small are available today on @inference_net
Get started: docs.inference.net/workhorse…

I found out today that two of the largest web scraping companies in the world are using a custom Llama 3 model we released last year to process millions of webpages per day.
Schematron-3b: HTML -> JSON parsing
Frontier quality at dirt-cheap prices.
huggingface.co/inference-net…

Mike Pollard retweeted

Day Zero fine-tuning & hosting support for Nemotron 3 Super by @nvidia is now live
Fine-tune on real production traces & deploy on high-performance infrastructure optimized for Nemotron 3 Super
Your data, your weights, your performance edge
Learn more: inference.net/blog/nemotron-…

Mike Pollard retweeted
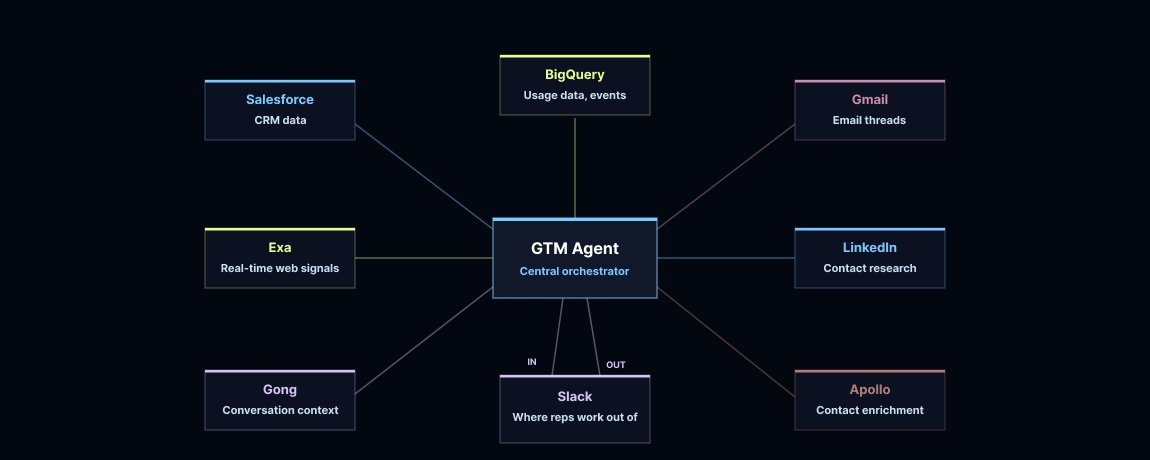
Going to open source our own internal version of this soon. It’s called Gator and it rocks

Mike Pollard retweeted
What if a codebase was actually stored in Postgres and agents directly modified files by reading/writing to the DB?
Code velocity has increased 3-5x. This will undoubtedly continue. PR review has already become a bottleneck for high output teams.
Codebase checked-out on filesystem seems like a terrible primitive when you have 10-100-1000 agents writing code.
Code is now high velocity data and should be modeled at such. Bare minimum, we need write-level atomicity and better coordination across agents, better synchronization primitives for subscribing to codebase state changes and real-time time file-level code lint/fmt/review.
The current ~20 year old paradigm of git checkout/branch/push/pr/review/rebase ended Jan 2026. We need an entirely new foundational system for writing code if we’re really going to keep pace with scale laws.
Mike Pollard retweeted

Introducing our new Schematron benchmark. We took some time to compare all of the latest open source models to see which one takes the crown.
The benchmark essentially measures the ability of LLMs to take raw HTML along with a JSON schema, and then fill out that schema. We measure things like recall/precision, hallucinations, and ability to handle ambiguity.
The benchmarks are graded with an ensemble of frontier models on a 5 point rubric.
We can see that GLM 5 is the best open source model currently for schema extraction. Surprisingly, GPT-OSS 120B does very well at these type of extraction tasks as well.
Another interesting result is we noticed degradation of quality using Qwen3.5 Plus on this task versus the original Qwen3.5 397B MOE.
The inputs can be up to 120K tokens, so this is akin to a long context benchmark, with an additional reasoning layer.
We will be open sourcing this benchmark if it gains sufficient traction. Also, more benchmarks coming from our side!

Mike Pollard retweeted
We're welcoming @mikepollard_dev to @inference_net as our Founding DevRel Engineer!
Mike and I won a pitch competition for my first company nearly 7 years ago
Life is long. When you find someone you love to work with, keep them close. You never know when your paths may cross


Mike Pollard retweeted
Dinner Number 1 was a resounding success!
Dinner Number 2 is Sept 5.
10 seats. Private dining room at a classic spot in the heart of SF.
DM me to come :)
Going to do 5 more of these and then throw a bangin’ party with everyone


Mike Pollard retweeted

I'm sick of food products with long lists of ingredients that I don't understand.
Someone should make a protein bar with just the following:
-whey protein (50g)
-caffeine (300mg)
-nicotine (6mg)
-testosterone (200mg)
-adderral (20mg IR)
Mike Pollard retweeted
AI won't replace the entire profession, but it's replacing the bottom 20-80% in {translation, design, coding, content, marketing,sales,design, operation, account, law}
Small teams like mine beat big corporations
because AI brings huge leverage for A players
Real examples of AI:

Mike Pollard retweeted

OOP Design Patterns is a scam.
All you need is functions.

ALT "How men and women see colours" meme converted into "How OOP programmers and FP see design patterns"


Mike Pollard retweeted
The future of building startups:
- MVP speed (1x per month)
- AI-accelerated
- Superniche is the new niche
- Community 1st, software 2nd
- No-code 1st, some code 2nd
- 10x more automated
- Global teams, localized products
- 95% dominated by solopreneurs and microentrepreneurs (teams less than 12)
- Pop-up digital experiences (apps that only work on certain times)
- Needs the marketing holy-trinity to hit escape velocity: 1. product/market fit, 2. content/market fit and 3. community/market fit
- Team is half robots 🤖, half humans 👨🦰 (cc @youneedarobot)
- Accelerated by "boring marketing" (cc @boringmarketer)
- Multiple revenue streams
- Design matters. The bar is high
- Partnered w/ creators (creators are the distribution)
- Feels like a game (levels, status, badges, in-app currency, challenges, collectibles/items)
- Purpose-driven moonshots: societal impact matters
- Productized agencies to generate cashflow (ex design agency @DispatchDesign)
- Product studios become the norm
- 99% of MVPs won't need VC