
Machine Learning Scientist @ Netflix | PhD @ UNC Chapel Hill | 2× Meta AI | Computer Vision • Video Understanding • MLLMs • GenAI
Chapel Hill, NC
Joined April 2016
- Tweets420
- Following309
- Followers273
- Likes599



Mohaiminul (Emon) Islam retweeted

Embodied models don't just think in text, they can think in visual plans, and fast.
Introducing VFlash, System-1 VLM for Physical AI.
Joint work by @YuCheng_Chou_, Shihao Wang and Jin Huang, LPR Team (@jankautz), GEAR Lab (@DrJimFan), and many other collaborators.
🌐 Website: research.nvidia.com/labs/lpr…
🧵[1/8] More details in the thread👇
Mohaiminul (Emon) Islam retweeted

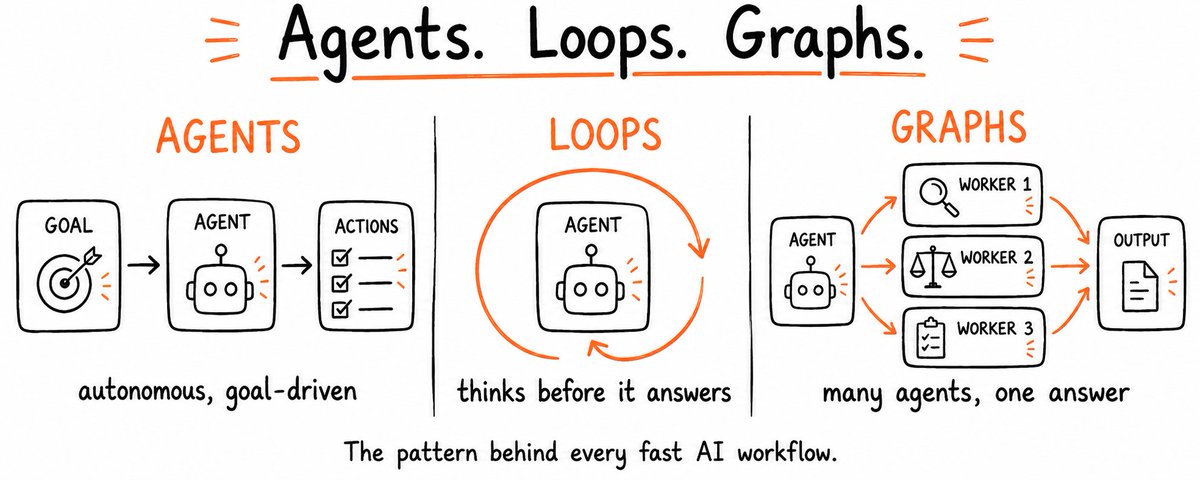
Anthropic just reliesed the best 1-hour workshop on Loop engineering: from one prompt to a Loop that improves itself
5:31 - loop memory
11:02 - check, build, commit
13:06 - one feature per loop
33:03 - MVP in 1 hour
Free, the best thing on Loop engineering I've come across.
Watch it, then try your first loop with the step-by-step guide below

Mohaiminul (Emon) Islam retweeted

Video models have become good at recognizing actions but still struggle to infer what people are trying to accomplish, why they chose a particular action, and what they will do next. We built SVI-Bench to measure this gap. We'll present it at #ECCV2026 next week. The video below gives a short overview of the work. I also wrote a short post on the broader research direction: gedasbertasius.com/post/from…
Mohaiminul (Emon) Islam retweeted

Join us today @CVPR rooms 704/706 #CVPR2026 at the EgoVis workshop - a long tradition of workshops on egocentric vision from #ECCV2016 10 years ago!
This edition features great keynotes, talks from relevant CVPR papers, accepted contributions&abstracts, challenge&award results.


Mohaiminul (Emon) Islam retweeted

🎥🪄 What should happen when you remove an object from a video?
Example 1:
A domino chain is falling → remove the middle blocks → the last block should remain standing
Example 2:
Two cars are about to crash → remove one car → the other should drive away 🚙
Current video object removal models fail at these dynamic scenarios.
We introduce VOID: a model that removes objects and updates the scene as if they were never there.
🏆 Preferred 64.8% of the time vs Runway Aleph, Gen-Omnimatte, ProPainter, and more.
🌐 Project page: void-model.github.io
💻 GitHub: github.com/Netflix/void-mode…
🤗 Demo: huggingface.co/spaces/sam-mo…
📄 arXiv: arxiv.org/abs/2604.02296
w/ @willarvey @ZhuoningYuan @ChengTim0708 and collaborators at @NetflixResearch and @INSAITinstitute
Mohaiminul (Emon) Islam retweeted

Introducing Ego2Web from Google DeepMind and UNC Chapel Hill, accepted to #CVPR2026.
AI agents can browse the web. But can they act based on what you see? Existing benchmarks focus only on web interaction while ignoring the real world.
Ego2Web bridges egocentric video perception and web execution, enabling agents that can see through first-person video, understand real-world context, and take actions on the web grounded in the egocentric video.
This opens a path toward AI assistants that operate seamlessly across physical and digital environments. We hope Ego2Web serves as an important step for building more capable, perception-driven agents.
🧵👇
Mohaiminul (Emon) Islam retweeted
If you're curious about the background that inspires a lot of our group's research on skill learning and video understanding, check out this great piece by UNC Research. It covers some of my journey from being a basketball player to an AI researcher.
research.unc.edu/story/readi…

Mohaiminul (Emon) Islam retweeted

Train Beyond Language. We bet on the visual world as the critical next step alongside and beyond language modeling. So, we studied building foundation models from scratch with vision.
We share our exploration: visual representations, data, world modeling, architecture, and scaling behavior! [1/9]

Mohaiminul (Emon) Islam retweeted

DeepSeek just dropped a banger paper to wrap up 2025
"mHC: Manifold-Constrained Hyper-Connections"
Hyper-Connections turn the single residual “highway” in transformers into n parallel lanes, and each layer learns how to shuffle and share signal between lanes.
But if each layer can arbitrarily amplify or shrink lanes, the product of those shuffles across depth makes signals/gradients blow up or fade out.
So they force each shuffle to be mass-conserving: a doubly stochastic matrix (nonnegative, every row/column sums to 1). Each layer can only redistribute signal across lanes, not create or destroy it, so the deep skip-path stays stable while features still mix!
with n=4 it adds ~6.7% training time, but cuts final loss by ~0.02, and keeps worst-case backward gain ~1.6 (vs ~3000 without the constraint), with consistent benchmark wins across the board

Mohaiminul (Emon) Islam retweeted
Hard to believe it’s been almost 5 years since I started at UNC. 2025 was an exciting year for our group!
🎓 My two PhD students—who joined me when I had an empty group—are graduating. Watching them grow into experts has been the best part of the job.
🏀 We are branching into Robotics & Sports (combining my personal passions with work!).
🎥 Our new video systems, BIMBA & SiLVR, achieved excellent performance across many challenging benchmarks.
🏆 Grateful for the awards we received across academia and industry this year.
I used to worry about making it in academia. Now, I'm just happy to be here. Huge thanks to my group for an incredible 2025. Here is a snapshot of what we accomplished! 📸

Mohaiminul (Emon) Islam retweeted
So well deserved! It was a pleasure watching you grow from having no prior CV experience to developing leading models in long video understanding. Fun fact: @mmiemon had all of his first-author papers accepted on the first attempt —a rare feat I haven't witnessed before. Excited to see what you do next!

I defended my PhD on October 6, 2025. Yesterday, my professor @gberta227 treated me to a wonderful lunch and surprised me with a thoughtful gift!
I’m truly grateful for the support, guidance, and kindness throughout these years. Feeling excited for what comes next 😊🙏


Mohaiminul (Emon) Islam retweeted
My student Han will be presenting our new video-language benchmark for expert action analysis (ExAct) on Wednesday. Be sure to stop by and chat about it at the poster session!

Come to our poster at #NeurIPS2025 !
📝 ExAct: A Video-Language Benchmark for Expert Action Analysis
🗓️ Wed, Dec 3 | 🕒 11:00 AM–2:00 PM (PST)
📍 Poster #4712 | Exhibit Hall C, D, E
📝 Paper: arxiv.org/abs/2506.06277
🌐 Project: texaser.github.io/exact_proj…

Mohaiminul (Emon) Islam retweeted

🚀 Hello, Kimi K2 Thinking!
The Open-Source Thinking Agent Model is here.
🔹 SOTA on HLE (44.9%) and BrowseComp (60.2%)
🔹 Executes up to 200 – 300 sequential tool calls without human interference
🔹 Excels in reasoning, agentic search, and coding
🔹 256K context window
Built as a thinking agent, K2 Thinking marks our latest efforts in test-time scaling — scaling both thinking tokens and tool-calling turns.
K2 Thinking is now live on kimi.com in chat mode, with full agentic mode coming soon. It is also accessible via API.
🔌 API is live: platform.moonshot.ai
🔗 Tech blog: moonshotai.github.io/Kimi-K2…
🔗 Weights & code: huggingface.co/moonshotai

Mohaiminul (Emon) Islam retweeted

🎉 Excited to share that 5/5 of my papers (3 main, 2 findings) have been accepted at #EMNLP2025, in video/multimodal reasoning, instructional video editing, and efficient LLM adaptation & reasoning!
🚨 I’m recruiting Ph.D. students to join the Multimodal AI Group at NTU College of Computing and Data Science (CCDS), starting Fall 2026.
✈️ + I’ll be at #EMNLP2025 in Suzhou, China; happy to chat about research, PhD positions, or just hang out!
🧵👇

Mohaiminul (Emon) Islam retweeted

Fei-Fei Li (@drfeifei) on limitations of LLMs.
"There's no language out there in nature. You don't go out in nature and there's words written in the sky for you.. There is a 3D world that follows laws of physics."
Language is purely generated signal.

Mohaiminul (Emon) Islam retweeted
Is language a "terrible abstraction" for video understanding?
Many in the video community often dismiss language-driven approaches in favor of complex, video-native solutions. However, I believe this resistance stems more from internal bias—validating a research identity as a "vision/video researcher"—than from empirical reality.
Simple, language-driven systems often dominate complex, video-native solutions. Over the last two years, our group at UNC has developed a series of such language-driven frameworks (LLoVi, VideoTree, VidAssist, and SiLVR) based on a simple, modular pipeline:
Video Input → Dense Captioning → LLM Reasoning
Empirically, these simple systems frequently outperform sophisticated video-focused solutions across numerous benchmarks while offering significant advantages:
Scaling: By decoupling vision and reasoning, we can leverage the most powerful LLMs (even 1T+ parameters). Video-native approaches hit GPU memory walls, often limited to <256 frames, making long-form video analysis very difficult.
Adaptability & Flexibility: Better captioners or LLMs (released very frequently these days) instantly improve the system with minimal effort.
Training-Free: They work out-of-the-box and easily incorporate diverse data (bboxes, audio/speech, etc) as textual captions. This avoids the complex, resource-intensive training regimes used by many recent approaches (e.g., particularly RL-based video reasoning systems).
While end-to-end systems may eventually prevail, these language-driven frameworks currently offer the most performant and practical approach to video reasoning. They shouldn’t be dismissed just because they are driven by language; they should be used as strong baselines to advance the field.
SiLVR: arxiv.org/pdf/2505.24869
LLoVi: arxiv.org/pdf/2312.17235
VideoTree: arxiv.org/pdf/2405.19209
VidAssist: arxiv.org/pdf/2409.20557
Mohaiminul (Emon) Islam retweeted

🎉Our Video-RTS paper has been accepted at #EMNLP2025 Main!!
We propose a novel video reasoning approach that combines data-efficient reinforcement learning (GRPO) with video-adaptive test-time scaling, improving reasoning performance while maintaining efficiency on multiple video reasoning benchmarks (VideoHolmes, VideoMMMU, MMVU, VideoMME, LongVideoBench).
Great collaboration with: @jaeh0ng_yoon (co-led) @shoubin621 @mmiemon @gberta227 @mohitban47.

🚨Introducing Video-RTS: Resource-Efficient RL for Video Reasoning with Adaptive Video TTS!
While RL-based video reasoning with LLMs has advanced, the reliance on large-scale SFT with extensive video data and long CoT annotations remains a major bottleneck.
Video-RTS tackles this challenge by:
▶️Replacing costly SFT with pure RL using output-based rewards (GRPO) - no extra annotations required!
▶️Introducing a sparse-to-dense video TTS strategy that adaptively adds frames based on output consistency for efficient & effective inference.
▶️Outperforming existing video reasoning models by large margins on benchmarks like Video-Holmes (+4.2%) and MMVU (+2.6%) using only 3.6% training samples.
Thread 🧵👇

Mohaiminul (Emon) Islam retweeted

🤔 Can we bridge MLLMs and diffusion models more natively and efficiently, by having MLLMs produce patch-level CLIP latents already aligned with their visual encoders, while fully preserving MLLM's visual reasoning capabilities?
Introducing Bifrost-1: 🌈
> High-Fidelity Generation: Patch-level CLIP latents natively aligned with MLLM visual encoder
> Training Efficiency: Outperforms other architectures in image quality over architectures using non-MLLM-aligned visual features, under controlled settings
> Preserves Visual Reasoning: Retains the strong visual understanding capabilities of backbone MLLM
🧵


