





Rafa Pardinas retweeted

Over the past week, I’ve been overwhelmed by the love and support of friends, industry colleagues, and people I've never met. Thank you to everyone who has shown kindness to my family and me. It means the world to me.
I came to the United States 53 years ago, and becoming an American citizen is one of the greatest gifts and proudest moments of my life. NVIDIA has been my life’s work. Building it into the company it is today alongside my colleagues has been a privilege and an honor. Nowhere but in America could a company like NVIDIA be possible. I love our country, and I love NVIDIA.
I did not live up to the standards expected of everyone at NVIDIA, and I have made serious mistakes in my personal life. I created problems for the Board that I deeply regret. I own my mistakes completely, and I am committed to cooperating with the Board’s independent investigation.
Since my departure, I’ve seen an outpouring of calls from NVIDIA’s employees, investors, business partners, and customers for me to return as CEO. Many continue to reach out to me directly as the company navigates complex technology, market, competitive, and geopolitical dynamics. NVIDIA is a once-in-a-generation company. If the Board of Directors decides that my return is in the best interest of our shareholders, our employees, the company, and America, I would be honored to answer these calls and return as CEO.
Thank you again to everyone who has shared their good wishes. I am profoundly humbled by your support. To my family: I love you, and I will spend the rest of my life being worthy of yours.
Jensen

Rafa Pardinas retweeted

Andy Burnham, in two weeks of being PM, has perfectly illustrated the main problem in UK public finances.
Week 1: there's a cost of living crisis, so to help you we've taken £45 a year off your electricity bill and capped bus fares at £2.
Week 2: we don't have enough money to fund everything we want to do, so we're taking £630 a year out of your salary.
Same government, same month.
Credit where it's due first - taking VAT off electricity from October is real money, so is the £2 bus cap in January if you're on a bus twice a day. Immediate cost of living relief is genuinely needed by most people.
But I'm not sure how someone who couldn't manage without that £45 a year of relief is supposed to now manage with £630 a year less in their pocket?
The £630 is a 1.8% levy on income to fund a National Care Service costed at £18bn a year. On a £35,000 salary it's £630, on £50,000 it's £900.
It's charged as a percentage of your income.
It's collected out of your income.
It is not, apparently, income tax, because they're going to call it a levy.
It also only applies to taxpayers over 34... So you turn 35 and take a pay cut, at the exact age most people are stretched on a mortgage with childcare costing more than the mortgage.
But the UKs ACTUALLY problem? Spending is too high. And it's too high in ways that are fixable if anyone was willing to challenge the status quo rather than buy more votes with handouts.
This is where £1,383bn goes this year:
Health, £269.6bn
Pensions, £236.3bn
Welfare, £204.0bn
Education, £126.7bn
Debt interest, £104.6bn
Defence, £75.2bn
Everything else, £367.1bn
Health, £269.6bn: We need mandatory health insurance as an employment benefit and a hybrid model. Everyone hears "insurance" and pictures America, someone bleeding out over a copay, as if no other model exists on earth.
The Netherlands has mandatory private health insurance. Insurers are legally required to accept everyone. They cannot charge you more for being chronically ill. A risk equalisation pool moves money towards the insurers covering the sickest people. It's consistently ranked top three in Europe.
Welfare, £204.0bn: Income tax raises £330bn. So almost 2 of every 3 pounds of Income Tax taken from every working person in this country is spoken for by the welfare bill.
Welfare should be for people who cannot work. Disability, genuine incapacity, the people it was built to protect. It has drifted into a general income top-up, and the number that proves it is 4.2 million working age people now claiming at least one health related benefit, up a million since 2019.
Change how we determine eligibility, fix a lot of spending issues immediately.
Pensions, £236.3bn: The state pension is a Ponzi scheme, and I mean that technically rather than as an insult. There is no fund - the ONS says so plainly. Your National Insurance is not being put aside and invested for your State Pension, It just pays the payouts for last year's pensioners. Yours depends entirely on there being enough workers behind you.
Which, btw, there won't be. The ratio of pensioners to workers goes from 27% to 48% by 2050 (and these estimates are before we've seen the proper impact of AI/automation on jobs.
Australia already fixed this: 12% of earnings into a private fund with your name on it, mandatory, employer paid. It's your money, it compounds, it doesn't need a bigger generation behind you to work.
We could mandate the same tomorrow and let the state pension run down over the next 40 years, eventually saving £236bn a year.
You can't levy your way out of these problems. A 1.8% charge on everyone over 34 raises £18bn. It doesn't even cover the interest on our existing debt.
And in the meantime... If we're going to borrow anyway, why is none of it buying anything?
Norway found oil in 1969 and put the money in a fund... That fund is now worth $2.049 trillion. It holds a stake in roughly 1.5% of every listed company on the planet.
We found oil in the same decade and spent it.
The UK's National Wealth Fund is capitalised at £27.8bn. Norway's is about 73 times bigger.
So where is our position in AI, in data centres, in grid scale renewables, in batteries, in electric vehicles, in any of the things the next fifty years actually runs on? We borrow £133bn a year and almost none of it buys an asset.
Fix government spending immediately, increase government income over time (without milking people for every penny of 'levy' you can find), and quality of life will genuinely improve as people have more money in their pockets.
The UK has a spending problem, not a tax problem.
Rafa Pardinas retweeted

🚀 Three papers accepted to COLM 2026! We're excited to share our latest work in reasoning, embeddings, and agent grounding with the research community.
👇
Rafa Pardinas retweeted

This is a very neat approach, estimating task difficulty for a difficulty aware length penalty (DAP) during RL training!


Better reasoning does not have to mean longer reasoning.
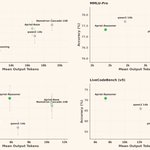
Apriel OpenReasoner: fully reproducible multi-domain RL post-training using public datasets. 30-50% shorter traces, no quality trade-off.
@ServiceNowRSRCH @ehsk0 @dvazquezcv @alexandredrouin
Rafa Pardinas retweeted

Been thinking recently about how to improve credit assignment in long horizon RL?
Our new MosaicLeaks blog post describes our method to accurately value actions via situational rewards, improving our privacy-aware research agent over outcome-only rewards!
huggingface.co/blog/ServiceN…

Rafa Pardinas retweeted
Excited to share my recent work @ServiceNowRSRCH ! We introduce a new privacy-centric deep research dataset and show models frequently leak enterprise information.
However, training with dense _situational_ rewards efficiently learns to jointly optimize performance and privacy
Rafa Pardinas retweeted

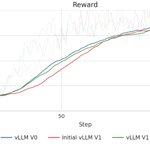
PipelineRL finally supports vLLM v1!
Our first vLLM V0→V1 run on PipelineRL looked broken.
@ehsk0 and I almost reached for an objective-side correction. That would have been the wrong fix.
The real problem: four mismatches in the rollout backend.
🧵

Rafa Pardinas retweeted
Our first vLLM V0→V1 run on PipelineRL looked broken.
@ehsk0 and I almost reached for an objective-side correction. That would have been the wrong fix.
The real problem: four mismatches in the rollout backend.
🧵
Rafa Pardinas retweeted

We use scaling laws for both pretraining and RL, but these domains handle scaling way differently. In reality, labeling both concepts as “scaling laws” is misleading…
Power laws. Most scaling laws are based upon an (inverse) power law, which describes the relationship between two quantities as:
y = a × (1 / x)^p
For LLMs, these two quantities are usually some performance metric (y) and compute (x). We can fit the power law to observed data (usually smaller scale experiments), then use this power law to extrapolate the performance at a much higher compute budget.
Pretraining defines scaling laws in a very particular way. On the x-axis, we have compute measured via training FLOPs C = C = 6 × N × D, where N is the number of model parameters and D is the number of training tokens. The scaling law then predicts the LLM’s performance, measured via the test loss L—the next token prediction or cross entropy loss specifically—measured over an in-distribution, held-out validation set.
To fit a scaling law for pretraining, we select several possible compute budgets C and perform a grid search over settings of N and D for each compute budget. Training a model for each setting i and measuring its test loss L_i gives us a dataset of the form (N_i, D_i, L_i) that can be used to fit a scaling law.
RL scaling laws are different from pretraining scaling laws in three primary ways…
(1) Performance (y-axis of scaling law): Pretraining scaling laws predict a particular metric: cross entropy loss on a held-out validation set. This performance metric is stable and computed over a large, diverse dataset. RL scaling laws typically use the reward (or accuracy) of the policy as the underlying metric to which scaling laws are fit. This is a downstream performance metric that can fluctuate substantially depending on the domain being studied, the benchmark being used, and the composition of data in that benchmark. Not only does this mean that RL scaling laws are less stable, but it makes them bespoke to the exact eval / task being studied.
(2) Compute (x-axis of scaling law): Pretraining has a clean compute footprint that is usually estimated with the number of training FLOPs C = 6 × N × D. RL performs both inference and policy updates during training, which makes its compute footprint more complicated. We can still try to measure the compute of RL with FLOPs, but this may not correlate well with actual GPU hours. As a solution, some work measures compute in RL scaling laws in units of GPU hours, but this also introduces a dependence of the scaling law on our training framework.
(3) How are RL scaling laws used? For RL, we consider fitting scaling laws for both:
- Intra-model extrapolation: predicting performance later in a training run (after training longer / with more compute) from the early phase of training.
- Inter-model extrapolation: predict performance of training runs with larger models and more compute from less expensive experiments (similar to pretraining).
Inter-model extrapolation is handled similarly to pretraining scaling laws (i.e., with a power law). On the other hand, intra-model extrapolation is modeled with a sigmoidal S-curve; see figure. Pretraining training recipes are relatively standardized and tend to be stable, which eliminates the need for intra-model extrapolation. RL training varies heavily depending on the training recipe / framework. Intra-model extrapolation allows us to judge whether a certain RL training recipe is feasible from the early training dynamics and, in turn, save compute.
Summary. The main takeaway from this discussion is that scaling laws play a different role in pretraining and RL. For pretraining, scaling laws allow us to forecast model capabilities in a clean and general way. For RL, scaling laws are messier, specifically created for a particular domain / training setup, and more heavily emphasize intra-model extrapolation.

Rafa Pardinas retweeted
Better reasoning does not have to mean longer reasoning.
Apriel OpenReasoner: fully reproducible multi-domain RL post-training using public datasets. 30-50% shorter traces, no quality trade-off.
@ServiceNowRSRCH @ehsk0 @dvazquezcv @alexandredrouin
Rafa Pardinas retweeted

We're sitting on a gold mine of data for evaluation and post-training.
Hundreds of agentic benchmarks, rich structured environments, verifiable signal.
Most of it is sitting idle. Not because nobody wants it, but because the engineering to use it is brutal. 🧵

Rafa Pardinas retweeted

Remember all the self-distillation papers that came out last week. Well, we also propose it 😅, but…
But alongside something better 😎 π-Distill
We show that with this method, you can distill closed-source frontier models even tho their traces are hidden 🔒.
Both our methods can reach and even surpass the performance of the industry-standard SFT + RL with access to reasoning traces 🤯.
🔬And we spent ~100,000 hours GPU hours on a comprehensive analysis, not because the method is finicky, but because we wanted to understand why it works so well.
🧵
1/10
Rafa Pardinas retweeted
Incredibly proud of the PipelineRL team!!!
PipelineRL got accepted to TMLR 🎉
~2x faster on-policy RL training through in-flight weight updates. Making LLM agents training fly at @ServiceNowRSRCH
@alexpiche_ @DBahdanau @ehsk0
Paper: arxiv.org/abs/2509.19128
Code: github.com/ServiceNow/Pipeli…

Rafa Pardinas retweeted
Train reasoning models 3x faster without sacrificing on-policy learning
github.com/ServiceNow/Pipeli…


Don't sleep on PipelineRL -- this is one of the biggest jumps in compute efficiency of RL setups that we found in the ScaleRL paper (also validated by Magistral & others before)!
What's the problem PipelineRL solves? In RL for LLMs, we need to send weight updates from trainer to generator (to generate data from our latest policy being trained).
(Conventional PPO-off-policy) A naive approach would be to "start generators on a batch, wait for all sequences to complete, update the model weights for both trainers and generators, and repeat. Unfortunately, this approach leads to idle generators and low pipeline efficiency due to heterogeneous completion times.
(Pipeline-RL) Instead, we simply let the generators continue generating tokens without discarding or finishing ongoing generations in-flight whenever we need to do a weight update -- doing an "in-flight" weight update. As such our KV caches for these generations would be stale, as they would come from LLM with earlier copy(ies) of the weights) but this is ok (see below).


Rafa Pardinas retweeted

i've been waiting for this moment since our initial PipelineRL blog post in May :) 🕺🕺🕺

to continue the PipelineRL glazing, @finbarrtimbers implemented PipelineRL for open-instruct a little bit ago and it ended up being probably the single biggest speedup to our overall pipeline. We went from 2-week long RL runs to 5-day runs, without sacrificing performance (combined with some other threading etc. updates).
Here's IFEval perf for an internal model (same data, same starting model, same bsz). Same number of training steps, same end perf, but PipelineRL is much faster.

Rafa Pardinas retweeted
In-flight weight updates have gone from a “weird trick” to a must to train LLMs with RL in the last few weeks. If you want to understand the on-policy and throughput benefits here’s the CoLM talk @DBahdanau and I gave: youtu.be/Z1uEuRKACRs

Rafa Pardinas retweeted

🚀 The RL community keeps pushing boundaries — from better on-policy data and partial rollouts to in-flight weight updates that mix KV caches across models during inference.
Continuing inference while weights change and KV states stay stale sounds wild — but that’s exactly what PipelineRL makes work.
vLLM is proud to power this kind of modular, cutting-edge RL innovation. Give it a try and share your thoughts!

I am excited to open-source PipelineRL - a scalable async RL implementation with in-flight weight updates. Why wait until your bored GPUs finish all sequences? Just update the weights and continue inference!
Code: github.com/ServiceNow/Pipeli…
Blog: huggingface.co/blog/ServiceN…


Rafa Pardinas retweeted
I am excited to open-source PipelineRL - a scalable async RL implementation with in-flight weight updates. Why wait until your bored GPUs finish all sequences? Just update the weights and continue inference!
Code: github.com/ServiceNow/Pipeli…
Blog: huggingface.co/blog/ServiceN…