
Pinned Tweet
LongAnimateDiff: Our new AnimateDiff model that supports up to 64 frames!
We are excited to announce the launch of our advanced motion module, designed for long video generation.
This cutting-edge module, developed based on the #AnimateDiff model (v2) for Stable Diffusion, now enables video generation of up to 64 frames, surpassing the industry's current maximum of 25 frames set by @stability.ai's #SVD. Moreover, our model offers enhanced flexibility, allowing for a variety of video lengths ranging from 16 to 64 frames.
For creators and developers, the model is now available in #ComfyUI.
code: github.com/Lightricks/LongAn… @HuggingFace: huggingface.co/Lightricks/Lo…
@s_weissbuch Daniel Shalem @yoavhacohen @ofirbb @Lightricks
Watch white wild ducks glide smoothly across calm village pond surfaces, warm sunset sky soft hues melt fatigue from endless rushed weekly office paperwork and task schedules
SDR-to-HDR, lip-dubbing, and more, all can be solved using the right recipe on top of @ltx_model.
Frame the challenge around dataset formulation, and the solution becomes straightforward.
Shared our methodology at #SIGGRAPH2026! 🎤👇

Want to know how we solved lip-dubbing using @ltx_model?
If you are at #SIGGRAPH2026, go check out @antonch44379293's talk about our JUST-DUB-IT paper today at 16:25 in Room 403 A!
love to see our paper working so nice! arxiv.org/abs/2601.22143


Tested @LTX's new LipDub capability on Tarantino's strudel scene - 11 languages, one model, dramatic close-ups preserved. This is what streaming localization looks like with the new generation of AI video models.
🇫🇷🇷🇺 🇩🇪 🇪🇸 🇵🇹 🇯🇵 🇮🇹 🇨🇳 🇬🇧 🇮🇱 🇰🇷 🇸🇦
I love seeing our work @MedOumoumad out there all around the world!

It was a big pleasure to work on this together with @antonch44379293 and Gal Zeevi!

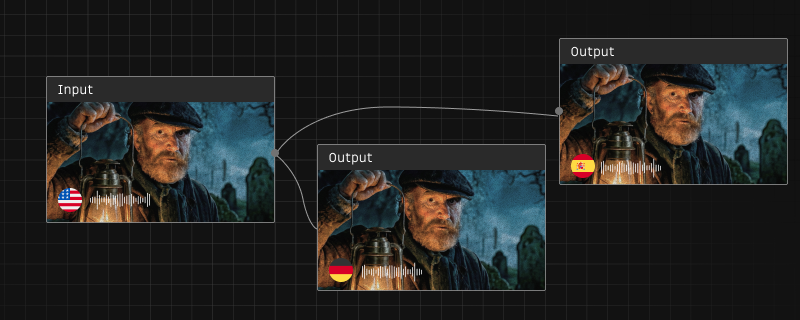
1/2 Excited to share my work with @antonch44379293 & Gal Zeevi: Just Dub It! 🎬🔊
We solve dubbing in one pass via joint audio/video on @ltx_model, handling extreme profiles & occlusions with ease.
Accepted to SIGGRAPH 2026! 🎓 🧵👇
This was a fantastic collaboration with @DanielCohenOr1 and @OPatashnik
We’re proud to open-source everything today for the community! 🌪️
🌐 Project: justdubit.github.io/
📄 Paper: arxiv.org/abs/2601.22143
💻 Code: github.com/Lightricks/LTX-2/…
🤗 Model: huggingface.co/Lightricks/LT…
1/5 Excited to share our latest: Bringing HDR to Generative Video! 🚀
The vision started with @AmirGa, who realized LTX should support HDR. Through a joint effort, @MedOumoumad and I brought it to life.
🔗 arxiv.org/abs/2604.11788
4/5 That’s the beauty of the generative domain: formulate the problem in the right space, and you get amazing results with very little data.
Proud to go from zero expertise to a full Beta in just 8 weeks! 🎬✨
5/5 An incredible academic and professional collaboration. Huge thanks to Prof. @DanielCohenOr1 and Prof. @OPatashnik for their guidance on the paper, and the whole team for pushing this through! 🤝
#GenerativeAI #HDR #AIResearch #LTX #MachineLearning
Creators here! Me & @MedOumoumad used @LTX to fix "camera corruptions" and unlock true HDR. 🚀
Check out also the project page : hdr-lumivid.github.io/

What this means is AI models that generate video are about to give us much better quality.
But this line caught my eye: “We teach the model to recover those details by training it through deliberate corruption.”
I love reading papers like this. Shows how the future gets better. And has creative thinking and engineering hidden inside.
Naomi Ken Korem retweeted

What this means is AI models that generate video are about to give us much better quality.
But this line caught my eye: “We teach the model to recover those details by training it through deliberate corruption.”
I love reading papers like this. Shows how the future gets better. And has creative thinking and engineering hidden inside.

Naomi Ken Korem retweeted

🎙️ Introducing ID-LoRA: the first open-source model to jointly generate a video with a person's appearance and voice in a single pass from just a reference image + short audio clip. No more cascaded pipelines where the audio can't follow your prompt.
youtu.be/6bWcMh18K6g?si=_Dgj…

צעדנו אתמול בשביל ביטחון המדינה. צעדנו כדי להזכיר לכולם. ביטחון המדינה הוא מעל הכל. אין מקום למתווה שיווקי. שנתיים לתוך לחימה, צריך חוק שיביא לגיוס נרחב מהיר ואפקטיבי. המגזר החרדי צריך לחזור להיות שותף בהגנה על המדינה.

גיוס הוגן ואמיתי לכולם הוא צו השעה 🇮🇱
צעדנו הערב יחד, משפחות מילואימניקים ומשפחות שכולות, דתיים וחילונים כאחד, כדי לדרוש חלוקה צודקת ונכונה יותר של הנטל לשמירה על בטחונה של מדינת ישראל.
המצב בו כל נטל הלחימה מוטל על קבוצה ספציפית של אותם האנשים שנקראים שוב ושוב ומשלמים מחיר אדיר, בזמן שאחרים זוכים ל״פטור״ - לא יכול להימשך.
נמשיך להיאבק יחד כל הדרך למען גיוס אמיתי וצודק.


Naomi Ken Korem retweeted

חנניה בין שמעון @hananiabsh מפרק טיעון סרק על צרכי כוח האדם של צה"ל: "למה לא מגייסים אנשי מילואים שקיבלו פטור?"
#מהצד_השני עם @guzyo הערב ב-23:30 בכאן 11 ובכאן BOX
Starting in 1 HOUR at #SIGGRAPHAsia2025!
Join us in Room S425 at 11:00 AM for our course: Master LoRA Training for Text-to-Video Models.
We’re showing how to train a LoRA in just 1 hour using our open-source tools at @Lightricks.
📍 Room S425 ⏰ 11:00 AM HKT (Today!)
See you!