

Intern @cartesia. PhD student under @francoisfleuret. Prev. Robotics @eth_en, @NVIDIA, @sony
San Francisco, CA
Joined July 2015
- Tweets45
- Following1.1K
- Followers195
- Likes1K




Ramón Calvo retweeted

1/8) Flow policies are Gaussian 😮
We replace their last layer with a Gaussian head fit on 0.02% of data:
• Similar task success
• Up to 2x faster inference
• Closed-form likelihoods
And behavior can still be diverse via diffusion in physical time.
(Xiaomi-Robotics-1, GR00T)
Ramón Calvo retweeted

"in-context tokenization"
I love it


I've always believed that intelligence should come from simple, general building blocks that learn their own abstractions directly from raw data; in other words, the bitter lesson. I think we're finally seeing a real step towards AI that can learn from all data.
Language modeling on raw bytes is a microcosm of this ideal, and to me it's a central problem in AI: if we can't build LLMs that learn end-to-end from bytes, how will we handle the rest of the world's data that we understand even less?
Last year we introduced hierarchical networks (H-Nets) as a first step. Our new version finds up to 3-5x efficiency gains in controlled scaling law experiments, and at larger scale matches an open-source model trained on 11T tokens with ~10x less data and compute. The posts below walk through what we found and why we think it works.
that's some interesting image chunking... 👀
I've always believed that intelligence should come from simple, general building blocks that learn their own abstractions directly from raw data; in other words, the bitter lesson. I think we're finally seeing a real step towards AI that can learn from all data.
Language modeling on raw bytes is a microcosm of this ideal, and to me it's a central problem in AI: if we can't build LLMs that learn end-to-end from bytes, how will we handle the rest of the world's data that we understand even less?
Last year we introduced hierarchical networks (H-Nets) as a first step. Our new version finds up to 3-5x efficiency gains in controlled scaling law experiments, and at larger scale matches an open-source model trained on 11T tokens with ~10x less data and compute. The posts below walk through what we found and why we think it works.
Ramón Calvo retweeted

another honest way of life im ngl

I've always believed that intelligence should come from simple, general building blocks that learn their own abstractions directly from raw data; in other words, the bitter lesson. I think we're finally seeing a real step towards AI that can learn from all data.
Language modeling on raw bytes is a microcosm of this ideal, and to me it's a central problem in AI: if we can't build LLMs that learn end-to-end from bytes, how will we handle the rest of the world's data that we understand even less?
Last year we introduced hierarchical networks (H-Nets) as a first step. Our new version finds up to 3-5x efficiency gains in controlled scaling law experiments, and at larger scale matches an open-source model trained on 11T tokens with ~10x less data and compute. The posts below walk through what we found and why we think it works.
Ramón Calvo retweeted

We're excited to share frontier research from @_albertgu and our team on H-Nets, a new architecture that learns directly from raw bytes instead of relying on a tokenizer.
Today's language models depend on a tokenizer that splits text into a fixed vocabulary of word fragments before training begins. H-Nets learn to form these units dynamically, end-to-end, on their own, adapting to the data and its context.
On pure language modeling, a 3B H-Net matched an open-source model using roughly 10x less training data. The approach also extends well beyond text, with early results on DNA and images.
For audio, this means speech language models that learn directly from raw audio and reason over text and audio natively. This remains a major bottleneck today, and this challenge is what first led us to this research.
More updates to come soon!
Blog:
Part 1: cartesia.ai/blog/from-tokens…
Part 2: cartesia.ai/blog/from-tokens…

I've always believed that intelligence should come from simple, general building blocks that learn their own abstractions directly from raw data; in other words, the bitter lesson. I think we're finally seeing a real step towards AI that can learn from all data.
Language modeling on raw bytes is a microcosm of this ideal, and to me it's a central problem in AI: if we can't build LLMs that learn end-to-end from bytes, how will we handle the rest of the world's data that we understand even less?
Last year we introduced hierarchical networks (H-Nets) as a first step. Our new version finds up to 3-5x efficiency gains in controlled scaling law experiments, and at larger scale matches an open-source model trained on 11T tokens with ~10x less data and compute. The posts below walk through what we found and why we think it works.
Ramón Calvo retweeted

What if embodied agents could learn to plan instead of just learning how to act? 🧠🤖
Introducing Generative Trajectory Planning (GTP)! 🚀
Instead of learning policies through RL, GTP imagines possible futures, plans ahead, and learns to plan better through experience.
Ramón Calvo retweeted
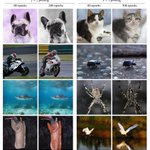
1/8) Better flow-matching samples.
No retraining.
Just multiply the velocity.
Same model.
Same 25 steps.
1.15× velocity takes FID from 28.0 to 8.7.
Unguided SiT-XL/2, ImageNet-256.
Velocity Scaling in Flow Matching, with @francoisfleuret.
Paper: arxiv.org/abs/2610.10823
Ramón Calvo retweeted

Awesome work from @noctrog and @YoussefMMSaied working in my lab at @unige_en.
After all those years I still cannot comprehend the amount of information packed in a few tokens [if you do your job well].


Your RAE does not need all of those tokens.
Meet PoolDINO: 4x-16x fewer tokens, similar generation quality, and both cheaper training and sampling.
Here's RAE vs. 8x compression on an M1 Pro CPU (no accelerator).
🧵
Good for generation doesn’t mean best for every task.
Learned pooling gives lower classification accuracy and worse performance on dense tasks (depth, segmentation) compared to simple baselines.

📄 Paper: arxiv.org/abs/2610.09242
🌐 Project: pooldino.ramoncalvo.com
💻 Code: github.com/noctrog/pooldino
🤗 Checkpoints: huggingface.co/noctrog/poold…
Work in collaboration with @YoussefMMSaied and @francoisfleuret

Ramón Calvo retweeted
❌Diffusion planners are missing a fundamental ingredient of classical control: an explicit model of the system dynamics.
📍We address this gap by introducing Model Predictive Diffuser, a new diffusion planning framework with a novel sampling strategy alternating between a planner and a dynamics model.
✅Achieving better performance, greater adaptability, improved sample efficiency and more!
