

Building pond - lossless archive + search for every AI agent session • pay-per-use APIs for AI agents (@glim_sh) • x402 + MPP contributor • 9yr eng
Portugal
Joined September 2024
- Tweets1.6K
- Following664
- Followers618
- Likes3.5K


Pinned Tweet
I made vector search the default in Pond when I just started developing it.
Then when I had a substantial usage data from my own daily interactions with it I could finally benchmark what are my real use cases and how agents actually do search sessions.
I judged all 1,126 searches my agents ran over 2 months:
- BM25 found what agent needed 61% of the time
- Vector semantic did worked in 37%
That allowed me with a light heart to remove all the added by embeddings bloat from default path in Pond and make everything faster and more reliable without sacrificing its main function - to quickly recall my earlier conversations.
Posted on HN: news.ycombinator.com/item?id…

I start every new conversation with “/compact”.
This is how I know I’m never late for compact.

almost every day i hear people ask "when should i /compact my session"
there's no easy answer because it depends on how likely your future action will need detailed context in the existing window
but we have Jev now! introducing compact-adviser - an agent plugin you can use in claude and pi today to help determine whether you're likely at a task boundary that's safe to compact
github.com/kunchenguid/compa…
i built a private eval set from 40 real sessions and manually labeled all the safe vs unsafe checkpoints to evaluate this, and hillclimbed the Jev prompt till it performed quite well
i also made it so that the classifier will
- optimize for precision (not triggering a compaction prematurely) when context window is small
- and gradually shift to optimize for recall (not missing an opportunity to compact) when context window fills up, because the cost of not compacting becomes higher, and at the end the agent will be forced to compact anyway
it supports a "hint" mode (just give you a hint and it's up to you to run /compact) vs "auto" mode which runs compaction whenever Jev says it's safe to do so
if you have Jev and want to put your compaction on autopilot, try this out and let me know how it goes! support for more harness is coming soon as well

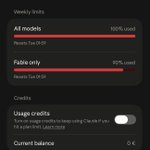
Reason 3 (open bug): messages sent to subagents that finished their task miss cache and all its context gets billed again on each request to it.
From 243K and 399K written tokens only ~16K get read from cache.
github.com/anthropics/claude…


Started building a tool for unified inbox/publish with analytics.
Starting with LinkedIn + X + Reddit + Hacker News support, keeping it extensible with a good interface/seam to add new custom adapters easily when needed.
Trying to solve an annoyance of having to juggle through different platforms when you post something, catching up with every comment/DM/mention/reply you may get after posting. It just eats too much of my time, and I tend to get into an endless loop of tracking everything instead of doing something useful.
I tried Typefully before; it's nice, but limited in the platforms I needed.
Last week I dived deep into what there is in the wild - openpost, brightbean, postiz, mixpost. I even tried openpost hosting it, but it all looks way too overengineered and buggy, and it simply doesn't give me the simple basis of what I need in one place. Some lack inbox, some lack platforms, some lack analytics for God's sake. And adding a platform is a nightmare of a task for all of them.
Is anyone interested in trying such a tool out if it would exist?
Trying to understand how much of a pain that really is, or is it just my gimmick.
Moved my posting to a small Go service I wrote this week. One binary, one SQLite file, REST only. X, LinkedIn and Reddit through Zernio, Hacker News read only. This thread is its first scheduled post.
Why there is still no unified standard file to describe all skills/mcps your harness should use?
Like we used to have all of that time before with docker-compose.yaml.
It would have been so neat to have agents.yaml in your repo and know it will be sourced by a harness you use.
If you can't fix the models you use, fix your workflows
It started as a small feature I wanted to implement for cuttle, a browser for agents. I spent some time planning it out, and then I thought that I could just get some Opus agents to implement it, and even if there would be some major problems, I would just do a few polish runs and it would work.
Polish is my pre-release review skill that hands the diff out to different review agents, then validates what they find and fixes everything after my approval. It was the thing I trusted most in my workflow.
The first round found 48 issues. I approved everything, everything checked green, and the next round found 22 more. Then I reviewed just the fixes that were applied, and that's where I found another 10. Each new polish run was just bringing me back more and more issues, and at some point it started feeling unbearable. I needed to dig in and figure out what was wrong.
I was confident the issue was with the lack of depth of what the subagents dig into. It had completely slipped my mind that the fixes themselves were so leaky. Transcript analysis showed that in reality everything in the initial report was actually fixed, but the fixes themselves had created almost half, or more, of the issues that the next review found.
The most ridiculous case was where each iteration of the reviewing agents was discovering the same masking issue, and each iteration of the fix agents was just rewriting the same code without fixing the actual issue. And that happened three times in a row. Especially when it was on a pretty critical path: masking the sensitive credentials.
What I learned is that no review can be trusted without two core pillars satisfied. First, there should be a ledger that tracks all of the issues and is persistent through all of the stages. Second, the review isn't done until a review of the fixes actually finds no more fixes left to be covered.
That's when I decided to create polish-new, a new version of my polish skill. It tries to improve on what the previous version did, with two main additions: a clean file ledger that gets maintained through all of the stages, and a new fix-review flow that keeps looping until all of the issues that were identified actually have the corresponding fixes.
I'm not sure whether my workflows changed or the models changed. But in any case, the only instrument I have to deal with that is to change my workflows.
Opus 5 started failing even simplest tasks for me this week.
I had asked it to copy CI release workflow from one repo to another and it spent 4 hours trying to make it work. In the end now I see that format of changelog still doesn’t match.
Anyone else feeling this?
Just added Grok and letta-code adapters support to pond.
I received a request for them from Kyle, who runs letta as an orchestrator on top of codex, pi, claude-code, omp and grok workers. At first I was thinking that I'm busy with many other tasks, but I used this opportunity as a possibility to implement the add-adapter skill that allows me to add new adapters much faster and in a much more reliable and predictable way, knowing that they wouldn't be able to break anything in the existing codebase. I've spent some time on that, but right now the new adapter addition is finally a straightforward process for me.
Should I add Cursor sessions import next? I've heard that many people use it, but I haven't seen Cursor users in the wild for a while.

Misha | opwizardx retweeted

Pond is a solid, easy to install, open source project that unifies your agent session transcripts into a single, searchable archive. Now with grok build and @Letta_AI transcripts.

Both shipped in v0.15.1 - letta-code and grok-build adapters,
One gotcha on an existing install: sync never enables new adapters by itself, run `pond adapters discover` once and it picks up ~/.letta/transcripts and ~/.grok/sessions.
I verified against letta-code 0.30.30 and grok 1.0.5 in a sandbox, your real archive is the first proper run. Tell me the first session that parses wrong 😉
Posted pond to Show HN on Aug 20. 1 point, 0 comments.
Not that I haven't expected that. I spent around 4 hours on the text. Researching how it should sound from the personal story side, researching the last 14 days of Show HN for what distinguished successful posts from unsuccessful. Got 400 words, still a mess, so I spent 2 more hours rewriting it so it wouldn't look ugly. Then posted and walked away, because that's what I was instructed to. Don't ask for upvotes, don't do anything.
From my perspective no one even saw it. So the text never mattered. I thought the title was the strongest thing. I don't even know what hasn't worked. It's magic for me.
Of course I still believe the pain is real. I really need this tool, it's a cornerstone of most of my sessions. People keep getting into the repository, asking for Windows support. I just cannot catch any traction from the platforms I expected it from.
So I just don't stop trying. r/ClaudeCode next, updates, reaching out to people one by one. Tiresome, but I don't see a better path.
How do you people make your post or product seen on Show HN? What do I miss in this whole process?

The thread, if you want to see what 1 point looks like: news.ycombinator.com/item?id…
Repo: github.com/tenequm/pond
Site: pond.locker