

Safety / Preparedness PM @ OpenAI. Pace the frontier. Dystopias are bad. Don’t defect.
San Francisco, CA
Joined March 2008
- Tweets4.8K
- Following1.2K
- Followers6.5K
- Likes16.1K






Owen Campbell-Moore ✪ retweeted

OpenAI fired me last week, along with two of my safety colleagues. I was given one reason: that I accessed an executive's email. I want to say this plainly, because too many of OpenAI’s history is smoke and mirrors when people disappear:

Owen Campbell-Moore ✪ retweeted

Two other safety researchers and I were fired from OpenAI last week. We wrote this letter to leadership.
I believe we were fired for prioritizing safety over the near-term interests of OpenAI as a corporation.

Owen Campbell-Moore ✪ retweeted

I'm surprised by the Evan/Jacob virality.
Safety lab quits aren’t new, and 10% p(doom) is low in my circles! Dario himself put 10%+ on AI going catastrophically wrong.
I knew I was in a bubble, but I underestimated how little of this reached the public. Glad that's changing.

Owen Campbell-Moore ✪ retweeted

We Must Pace the Frontier: I’ve written a new essay on why the AI industry should slow down, with a three-part plan for doing so.
Anthropic is unilaterally committing to the first of these steps. We’ll provide third-party evaluators with permanent, employee-level access to our systems, so that they can verify adherence to our safety measures, report on incidents, and assess models’ alignment during training.
You can read the full post here: darioamodei.com/post/we-must…

Owen Campbell-Moore ✪ retweeted

GPT-4o as tested by @BeMyEyes:
Owen Campbell-Moore ✪ retweeted

GPT-4o is our new state-of-the-art frontier model. We’ve been testing a version on the LMSys arena as im-also-a-good-gpt2-chatbot 🙂. Here’s how it’s been doing.

For those asking, the evals are out:
+8.9% on MATH
+7.9% on GPQA
+4.5% on MGSM
+4.5% on DROP
+1.3% on MMLU
+1.6% on HumanEval
Source: github.com/openai/simple-… (new w “assistant” prompt vs 0125)
Source link got broken when I copied it from a previous tweet, here is the source and full data: github.com/openai/simple-eva…

(I made a mistake when I posted this 10 mins ago and said +1.5% on MMLU instead of +1.3%, so deleted and reposted, sorry about that!)


Owen Campbell-Moore ✪ retweeted

The awesome team at @cursor_ai shows improved reasoning on complex coding tasks with the new GPT-4 Turbo model:


Owen Campbell-Moore ✪ retweeted
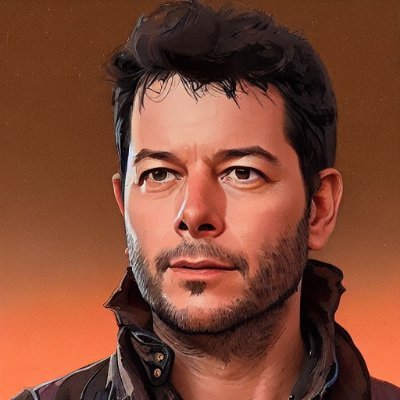
IT'S FINALLY HERE!
🔥 Magnific Style Transfer! 🔥
Transform any image, controlling the amount of style transferred and the structural integrity ✨ Infinite use cases! 3d, video games, interior design, for fun...
Details, 10 tutorials & HUGE surprise 🧵👇
Hey Prateek! We did train this based on MRL - I was responsible for the blog post and it’s my bad not thinking / remembering to cite. We’re updating the blog post to add a citation now!

Owen Campbell-Moore ✪ retweeted
In case you missed it - the smaller model is so cheap you can embed an entire book (64000 English words) for less than $0.002!!! That's 5 books for < 1¢!!! 🫨
Owen Campbell-Moore ✪ retweeted

Taking things up a notch, we're releasing the text-to-diagram feature! 🔥
Using AI to generate diagrams from plain text. 🧠
Unlike wireframe-to-code previously, you don't need your own API token — everyone can start generating right away! 💪
excalidraw.com
Owen Campbell-Moore ✪ retweeted

we're raising rate limits for all API models whenever we can (lately daily!)
let us know which limits are holding you back from building and we'll try to unblock
This quoted post is unavailable.

