

Trending AI research papers with code, datasets and leaderboards.
Global
Joined October 2026
- Tweets85
- Following0
- Followers34
- Likes2





Scaling in Games: Continued Pre-Training For Embodied Agents In Diverse Virtual Worlds
Scaling continued pre-training improves in-world gameplay, but diversity and model size govern transfer differently.


Looking Ahead: Modeling Future Evolution in Autoregressive Video Generation
Future Chunk Prediction discourages autoregressive video models from relying on local temporal redundancy during teacher-forced denoising.


Ropedia W0: Scaling Loco-Manipulation World Models across Embodiments with Human Experience
Ropedia W0 unifies human and robot egocentric data for cross-embodiment loco-manipulation world modeling.


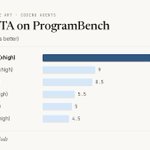
Congrats @claudeai on achieving SOTA on ProgramBench!
Claude Opus 5.5 (xhigh) scores 18.5 Resolved, ahead of Claude Fable 5.1 (xhigh) at 9.


Xiaomi-Lens-0 Technical Report
Xiaomi-Lens-0 grounds reasoning in regions by decoding masks from visual latents and language-model mask-token states.


Sage-A1.5: From Long-Horizon Execution to Scientific Exploration with Capability Composition
Sage-A1.5 composes delegation, parallel subagents, verification, and strategy revision for long-horizon problem solving.


Calibrated Typed Decisions for Entity, Relation, and Event Extraction
CalOn unifies entity, relation, and event extraction in a 0.6B-parameter encoder that jointly reads text and type definitions.


SolarRenderer: Few-Step Generative Reference Rendering
SolarRenderer adapts a frozen video backbone with two LoRAs, injecting frame-aligned structural videos through its native reference pathway for representation-agnostic control.


