

Daily lessons on why AI agents fail & how to fix them. Learn harness engineering & sovereign agents. Free courses, office hours & comic explainers
Joined June 2025
- Tweets135
- Following217
- Followers23
- Likes6




Why does your AI agent demo beautifully and break later? It's the harness, not the model.
Starting Friday at 11 AM EDT, free weekly office hours with @Nebius_Academy and @rasa_hq builders on exactly this.
Share your questions. I will answer live on Zoom for 60 minutes.
RSVP: lu.ma/7ci6q3zp

If you're in Munich on Saturday 02/05 and would like to understand Why AI agents fail? And what you can do about it!
Come to our free workshop!
We will discuss failure modes and how to counter them and many of our learnings at @Rasa_HQ.
RSVP: luma.com/000nj7ez

I pulled an all-nighter to finish and release the final project for our course at Nebius Academy.
One part of the project was open-sourcing the Sovereign Agent.
You can check it out here: github.com/sovereignagents/s…
This is my first fully open-source contribution to PyPI, and I really hope others will find it useful.
Over the past few weeks, I’ve been studying how modern, always-on AI agents are built in 2026. I call these 'sovereign agents.' Think of tools like OpenClaw, Claude Code, Aider, and similar projects.
My goal was to make something simple enough to help people learn, but also practical for building real projects.
These days, agents seem overly complex and packed with dependencies. For example, OpenClaw has hundreds of thousands of lines of code, but it doesn’t have to be that complicated.
For those familiar with it, my inspiration was the fast.ai library. It was designed for learning how Deep Learning works, but many people ended up using it for their own projects.
Since this field is moving fast, I already have plans for version 2 and hope to release it in the next few days.
I’m also working on documenting all the patterns these agents use.
If you don’t want to miss any updates, please star the project and share your comments or feedback!

Are agentic skills simply a new way to store and organize prompts?
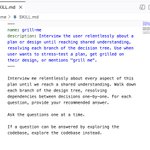
I’ve checked out some popular skills on GitHub, and I’m surprised that many are just a single simple prompt, like: "Interview me relentlessly about every aspect of this plan until we reach a shared understanding."
One reason might be that we never really learned how to prompt well. Prompting was often seen as a temporary skill or even as "pseudo-engineering."
Even as the models improve, it makes less sense to start every prompt with "You are a world-class X."
When we structure prompts well, or what we call 'skills', we get more consistent results from these models.
You don’t always have to, but adding a role to your prompt and giving clear instructions can help.
So what if we never really learned how to do all this?
Luckily, that’s where repositories and directories of SKILL.MDs can help.
This example shows how much we can get out of a simple prompt, without using tool calls or writing 100 lines of instructions. Even now, four years into ChatGPT, we’re still just scratching the surface of what’s possible with LLMs.
That’s why I encourage everyone to keep looking for ways to improve their prompting if they want to build better agents, harnesses, or skills.

Last week, @Rasa_HQ and @nebiusacademy co-hosted a webinar, and nearly 100 engineers attended to discuss AI agents and Claude Code.
Thanks to Denis Volkhonskiy and Stan Fedotov for the deep dive into Claude Code. I walked away with sharper mental models myself.
Here is what stuck with me:
1. An agent is not just an LLM
Brains (LLM) plus Knowledge (RAG) plus Tools (Bash, file I/O) plus Workflow control. All four layers have to work together before you have something production-ready.
2. Plan Mode changes everything
Stop asking agents to "fix the bug." Enter a collaborative planning state first. The agent proposes a path, you approve it, and then it executes. No surprises.
At Rasa, we call this equivalent Conversation-Driven Development. Listen before you build. The same principle applies to agents.
3. Security is not an afterthought
When you give an agent a Bash tool, you're handing it the keys to your house. Two non-negotiables: never expose .env files, and vet every MCP skill like you'd vet a random script from the internet.
4. Context is your budget. Spend it deliberately.
Use “compact” or “clear” between sub-tasks. Tag specific files with “@” instead of pointing at the whole repo. "Look at everything" equals hallucinations plus a bill you didn't expect.
What's next
We are headed into a future of digital coworkers, conversational and headless. The engineers who figure out how to combine both are going to have an unfair advantage.
We're building a hyper-local community of AI engineers in London. If you're in London, sign up here: hellorasa.info/4aAUQ6O
I also wrote a longer post with my learnings from the webinar here: hellorasa.info/46Zh29M
Plus, don't forget to apply to the AI Performance Engineering program from Nebius, the deadline is approaching!
If you want to understand how "always-on" AI agents, such as OpenClaw, or conversational agents, such as @Rasa_HQ , work and build your own, join us in March!
It will be in person in Central London in the evenings. Plus, best of all, it's free!
Let's learn together how to harness these technologies to automate tasks and deliver better customer experiences!
You can apply to the @nebiusacademy at the link below.
(and of course, if you're obsessed with #OpenClaw like I am, subscribe to @localainet to stay up to date on what's happening in the OpenClaw ecosystem)

Meet @profrodai 🎓
DevRel at Rasa and Professor of the Practice at ITAM, Rod will be teaching at our free AI Performance Engineering course in London this spring.
You’ll learn how to build AI agents for business tasks on top of third-party APIs.
Apply: bit.ly/40aMVbE

Apply here to the @nebiusacademy AI Performance Engineering program, it's free, in London, and starts in March: hellorasa.info/3OkfVeq
Most of us use Claude Code just for the basics, but when it gets complex, we're back to copy-pasting into ChatGPT. That's why I'm joining Denis Volkhonskiy and Stan Fedotov, PhD, from @nebiusacademy to enter the Claude Code "engine room" tomorrow.
What we are breaking down:
* Reliability: How to stop "hallucination loops" in agent-based iteration.
* Speed: Building high-speed pipelines that don't sacrifice code quality.
* Production: Moving past experiments into actual ML and DevOps workflows.
We'll also be giving a first look at the AI Performance Engineering course coming to London this March. It’s a 14-week deep dive (completely free) for those ready to move from "using AI" to "engineering AI systems."
In the course, I'll show you how to build voice AI agents with @Rasa_HQ and tools like OpenClaw.
If you’re an ML engineer, DevOps specialist, or a dev looking to upgrade your stack, you must come and join us!
📅 Tomorrow, Feb 17
🕓 04:00 PM GMT
🔗 Register here: hellorasa.info/4aqzMzN
Can't make it? I also curate a calendar of the best AI events happening in London (online + in-person). It would be great to see you at one of those instead: hellorasa.info/4aAUQ6O
#ClaudeCode #AIagents #Rasa #NebiusAcademy #SoftwareEngineering #MLOps


We have now vibecoding, Lovable, and v0, and so many tools to create websites fast.
Yet, most new websites keep looking like they used one of the free templates available on Webflow
In today's edition of OpenClaw Daily, we dig into:
* Security Beyond the Prompt
* The 24-Hour Exploit Cycle
* Persistence & Backends
and more!
substack.localaicommunity.co…
In today's edition of OpenClaw Daily, we dig into:
* Security Beyond the Prompt: We explore why "writing better instructions" isn't a security plan. For production agents, we need kernel-level enforcement and zero-trust architectures.
* The 24-Hour Exploit Cycle: Analyzing how quickly vulnerabilities are being scanned in the wild post-launch.
* Persistence & Backends: How to give agents the databases and APIs they need to function 24/7.
and feature community contributions by
* Sagi Rodin for the deep dive into AgenShield and shifting security from "vibes" to deterministic policies.
* Angel Dimitrov for his fascinating experiment in multimodal feedback loops, giving his agent a face and a mirror to refine its own expressions.
* Chris Rosendale & Eric Pauley for providing critical data on how scanning activity ramps up globally within hours of an exploit's discovery.
* Knut Martin Tornes for showcasing how to integrate Codehooks.io to provide agents with a robust, serverless backend.
* Rob Pisacane for his strategic look at "Agentic SEO" and how businesses must adapt for machine-readable web traffic.
* Steffen Maas at Ocean One Ventures for the "Mr. Crabs" case study, where they maintain data sovereignty while building an autonomous executive assistant.
Read below!
Have an interesting project or opinion?
We would love to feature your work or insights in an upcoming edition.
Want to join the conversation?
We have a WhatsApp community where we discuss all things OpenClaw. Contact me for access.
substack.localaicommunity.co…

OpenClaw is great! But local != secure if the LLM has full home directory access.
Check out AgenShield for:
✅ Static policies (not vibes)
✅ Kernel-level enforcement (macOS Seatbelt)
✅ JIT secrets
🔗 Shield: bit.ly/4qpSjT6
💻 GitHub: bit.ly/3MsvjVv
In issue 07 of OpenClaw Daily, we feature insights from:
- 🦄 Peter Steinberger
- Bence Csernak
- Alex Cheema
- Jason M. Lemkin
- Mesut Gulecen
- Rachel Nguyen
Also in this issue: We take a look at OpenShears
substack.localaicommunity.co…
Hilarious that there are already at least 2 YC startups from the current batch offering "OpenClaw in a box with extras"

The "caricature trend" on ChatGPT shows that LLMs are not really "intelligent" and are rather high-density mirrors of data noise. If you are letting an LLM guide your life decisions, you aren't being led by a mentor. You're being steered by a statistical average.
When I asked for a caricature of my life and job, the disconnect was staggering. Despite years of feeding the model data about my curly hair, activities, and my work as an educator, the output looked nothing like me. This failure is a window into a fundamental architectural flaw in how we handle data.
Density over Recency: The Weight of the Average
LLMs lack a native chronological sense of "self." Even with persistent memory features, the architecture prioritizes signal density over recency.
The reality: I've spent the past few weeks obsessed with jump-roping and deep-diving into OpenClaw.
The failure: Because my multi-year history is peppered with generic programming talk, the model defaults to the weighted average. It ignores my current evolution in favor of the stereotype. It favors the "Programmer" archetype because it has a higher probability distribution than an "OpenClaw enthusiast who jumps rope."
The RAG Illusion: Why Time-Agnostic Vectors Fail
We often mistake vector embeddings for human-like memory. They aren't. LLMs are fundamentally stateless, and current Retrieval-Augmented Generation (RAG) architectures treat data like a bucket of confetti rather than a timeline.
The "bolt-on" memory: Injecting context via vector databases is like giving a person with amnesia a stack of sticky notes seconds before they speak.
The temporal bottleneck: Standard vector similarity (cosine similarity) is time-blind. It calculates the distance between "me" and "ducks" based on semantic proximity, completely ignoring the timestamp.
The duck problem: The model knows the AI Product Engineer logo isn't a random duck, yet it generates bathtub rubber ducks. Why? Because in a high-dimensional vector space, "duck" is a massive gravity well that pulls in generic representations. Without a recency prior or temporal decay function, the model can't distinguish between a casual mention of a toy and a primary brand identity.
Hallucinations as a Logical Necessity
An LLM's only "biological" imperative is to predict the most plausible next token. It doesn't have a fact-check layer. It has a probability layer.
If the model lacks the specific data to bridge the gap between my actual face and its training set, it won't admit ignorance. It will simply invent a who statistically fits the prompt's vibe. This is how we get "stochastic parrots" masquerading as personal assistants.
The Danger of "AI-Induced Psychosis"
The real threat isn't that OpenClaw will develop a religion or plot a coup against humans. It is that humans are developing AI-induced psychosis.
We see patterns where none exist. When people treat these high-end autocomplete outputs as divine or deeply personal insights, they fall into a trap of algorithmic confirmation bias. I see the generic ducks and see a flawed architecture. Others see "signs" and radically change their lives (often with disastrous consequences) based on the suggestions of a machine that doesn't even know what year it is.
We must be aware that these models are built for generalization, not individuation.
If you're interested in how LLMs actually work (versus how they're marketed), agent architectures, and what breaks when you try to use statistical models as personal advisors, follow me for more posts like this. I write about agent engineering, AI operations, and the difference between intelligence and autocomplete.

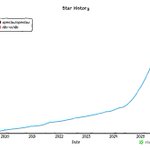
Just a week ago, I was wondering how long it would take for OpenClaw to have more stars on GitHub than n8n. It took n8n 81 months to get to 174k stars. OpenClaw achieved it in 3 months.
At the beginning of the year, before becoming aware of OpenClaw, I mentioned that 2026 is the year of the digital coworker, where we finally move from software and AI that help us with our workflow to software that autonomously completes outcomes, software that truly works like a digital peer to whom we can delegate tasks.
Right now, this vision isn't yet fully materialized. OpenClaw and similar tools are far from perfect and very experimental. But you can imagine a very close future where we aren't paying a yearly subscription for a CRM at $6,000 USD, but instead we start paying $15,000 or $20,000 for a digital SDR. It might sound like a lot to pay for software, but when you consider that a human SDR has a yearly base salary of around $40,000, you realize a company saves more than half the costs while getting more or less the same results. And without someone who goes on holidays, takes days off, or might leave you at some point.
This might sound grim, but the other side of the coin is that anyone adopting OpenClaw and similar digital coworkers starts to have a virtual team at their disposal that truly makes them 10x more productive.
We just have to look at how products like Lovable already empower marketing teams to do in days what was truly impossible and unthinkable before without involving agencies, high budgets, and months of planning and development.
This is the first time since ChatGPT went live in late 2022 where it feels that, again, AI is accelerating and radical changes are starting to happen.
How are you using OpenClaw?

OpenClaw Daily Issue 06 is out and covers:
* Cost optimization
* Critical security practices
* Real-world use cases that work today
* Local vs Cloud tradeoffs
* Current limitations
Plus! Community highlight
substack.localaicommunity.co…