

Research at OpenAI. Be kind to others, and yourself.
San Francisco, CA
Joined September 2009
- Tweets1.1K
- Following1.6K
- Followers11.1K
- Likes4.3K





Ted Sanders retweeted

"Our initial evaluation suggested that GPT-6-Astra's score was in the late eighties followed closely by Opus 5.5. But, as we started to investigate the mistakes that the models might have made, the models, especially Astra, insisted that they were right and that it was the expert-supplied answers that were erroneous. When we went back to the experts it turned out, in multiple instances, that that the experts found some subtle errors buried deep inside their calculations. As they revised their answers, Astra's score started to inch up and it finally ended up with 98% (49/50)."


Ted Sanders retweeted

Anyone who believes hallucination is an intractable problem for current models needs to update on both reality and directionality. So much has changed in the last six months.
deploymentsafety.openai.com/…

the GPT math results exemplify life's long arc of increasing cooperation and specialization.
credit is due to no single mind; it diffuses across many thousands who published math papers, wrote code, manufactured chips, built data centers, etc.
the age of heroes is ending.
Ted Sanders retweeted

We’re introducing Humanity’s Sixth Sense, a new benchmark testing the intuitive visual reasoning people rely on every day.
Across 522 open-ended tasks spanning images and video, HSS tests everything from spatial and causal reasoning to social understanding.
The gap is significant. Humans score 93.1%, while the strongest model, GPT-6-astra, reaches 53.6%. The median model scores just 30.9%.


Ted Sanders retweeted

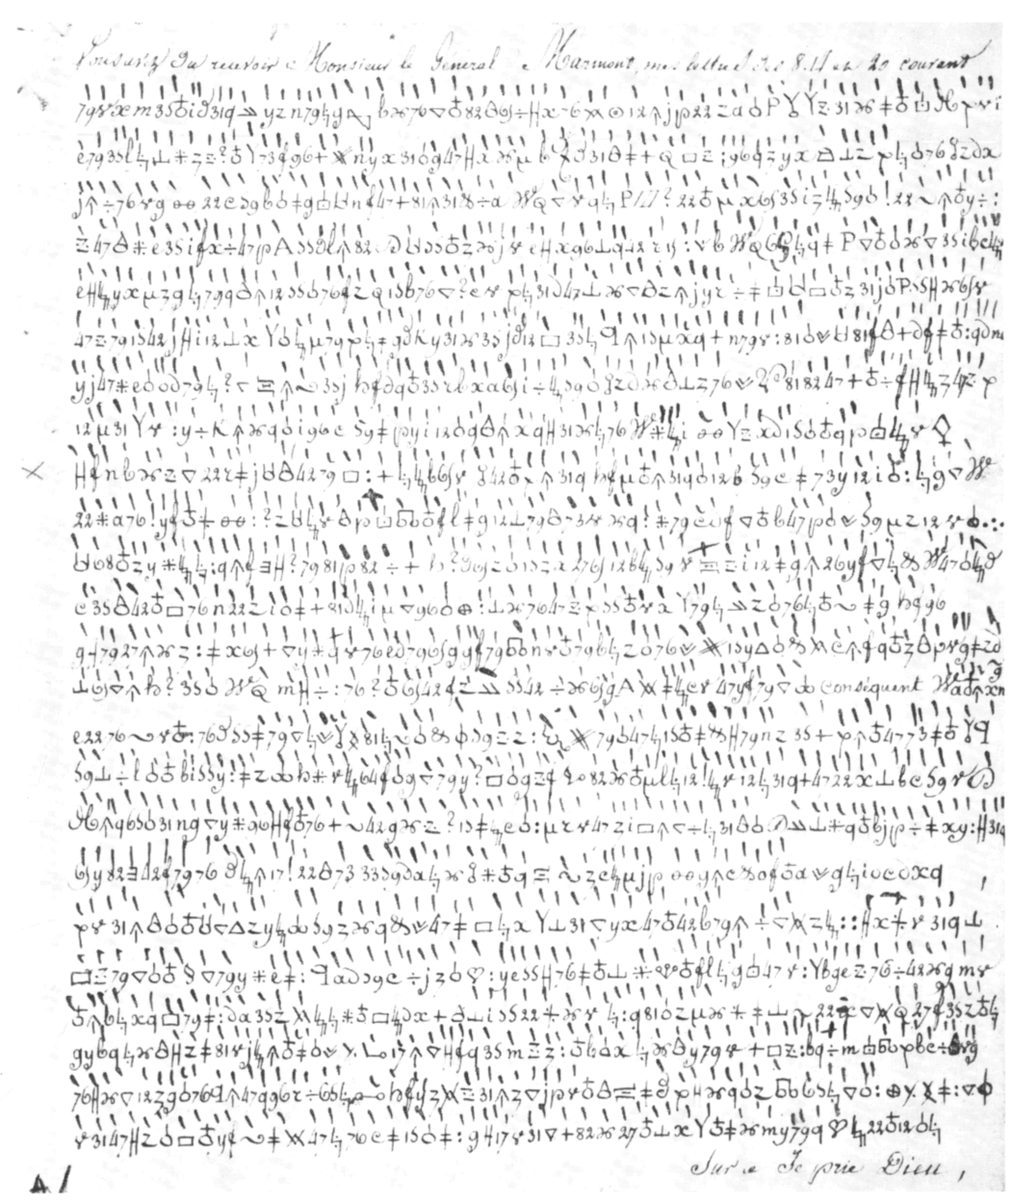
I used GPT-6 Astra to break an unsolved cipher to one of Napoleon's generals that had gone unread for 217 years.
What makes this impressive isn't actually the codebreaking, but that Astra completed the entire multi-modal workflow in ~6 hours from a single image and goal.
1/6🧵
One cool thing about ARC-AGI-3 is that it measures cost until success or timeout, instead of cost of first attempt.
This is arguably more aligned with real life, and shows how costly models at high efforts can counterintuitively be cheaper, by needing less iteration.

GPT-6.1 Sol from @OpenAI on ARC-AGI (Verified):
- ARC-AGI-3: 52.7%, $7.6K (standard harness), 96.4%, $4.4K (provider adapter harness)
- ARC-AGI-2: 94.2%, $0.25/task
- ARC-AGI-1: 98.5%, $0.06/task
Its 96.4% on v3 was comparable to GPT-6 Astra's 99.9% but at a 77% lower cost.

Ted Sanders retweeted

GPT-6.1 Sol is exceptionally good at complex knowledge work tasks
On ClickUp Bench, our internal eval for white collar knowledge work, it expands the pareto frontier with superior performance to models 2x in cost (!)
Congrats to @OpenAI on a banger launch. Live in ClickUp now!


Ted Sanders retweeted

gpt-6.1 sol on HLE-Diamond is kinda insane
overall:
6.1 sol — 53.2%
fable 5.1 — 50.7%
opus 5.5 — 54.6%
but on pure reasoning, 6.1-sol actually beats both: 67.4% vs. 60.8% for fable 5.1 and 62.4% for opus 5.5 -- and it does this using just 4k tokens, compared to 16k for fable and 10k for opus


Ted Sanders retweeted

When I made this video, there were no benchmarks yet, so I had to run them myself. Jaw dropped when I saw the Terminal Bench 4 scores.
Performance better than Opus 5.5 for ~1/30th of the price 🤯


Ted Sanders retweeted

GPT-6 Sol now leads DeepSecBench's Pareto frontier:
• Highest benchmark score
• 80% lower run cost than the runner-up (GPT-6 Astra)
vercel.com/ai-gateway/leader…

Ted Sanders retweeted
We just added GPT-6 Sol to MathArena! It comes in only just behind GPT-6 Astra, at slightly lower cost. Despite its significantly lower cost per token, it reasons more, bringing its cost closer to Astra.


