


Seldon retweeted

Continuing my series on CAD AI:
Here Gemini 4 Argon is supposed to build a base for a given DAMIAO 4340 actuator. It uses coding exclusively and finishes after 263 steps with a reward of 0.459 mostly because of missing wire openings
Seldon retweeted
Starting a new series where I show the latests models' performance on different real-world tasks in Engineering
The first one is GPT-6.1 trying to reconstruct the graph on the right in AutoCAD. It took 181 steps and got a reward of 0.414
Our Co-Founders @PascalBtd and @atoof_sh sat down on the Europe on Edge podcast and talked about the current state of multimodal AI and the company's mission. If this mission resonates with you, have a look at our open job listings (links are below).

Muse Spark 1.3 improves despite pass rate staying at 0%:
• Mean verifier score: 13.44 → 20.66 (+54%)
• Average runtime: 60.8 → 23.8 minutes (61% shorter)
• Valid tool calls: 76.8% → 93.0%
Better intermediate results and faster runs, but full task completion remains unsolved.

Read more: seldon.global/blog/cadbench
We’re expanding into more real-world engineering workflows across multiple domains, with new tasks and benchmarks coming soon.

Seldon retweeted

Can computer-use agents use complicated graphical software? You’re watching GPT-5.6 Sol operate Autodesk Fusion for 250 turns as it attempts a real mechanical-design task. The run is part of a benchmark aimed at the question "how good are agents at CAD?"
@seldon_tech's CADBench contains 105 mechanical-design tasks tested across 10 frontier models, and the results show how early reliable, autonomous CAD work remains:
More than two-thirds of the tasks are still unsolved.
That gap matters as agents make their way into the professional tools used to design the physical world. Getting around Autodesk Fusion is one thing, but producing a correct, editable model an engineer can pick up and use is much harder.
CADBench gives us a way to see and measure that frontier.
Great work from the Seldon team! Explore CADBench: seldon.global/blog/cadbench


Read the full report here:
seldon.global/blog/cadbench
Seldon retweeted
drop by our meetup today if you're in SF!
luma.com/g7ludajl

Infinibench-v0: part of the benchmark was created by a continuously exploring agent, rewarded for identifying new failure modes in VLMs.
It produces non-trivial, out-of-distribution problems — trivially easy for humans, yet SOTA VLMs fail — and diagnoses failure modes that were previously unknown.
To celebrate the release of this benchmark we'll host a meetup in SF. If you're in town, sign up here: luma.com/g7ludajl
Full blog-post about this benchmark: seldon.global/blog/vgi-bench


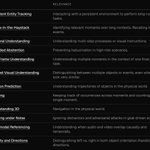
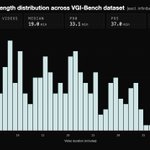
Introducing VGI-Bench: a multimodal, holistic benchmark probing 12 distinct visual and audio-visual skills.
550 human-curated questions, designed to mitigate the common mistakes in today's video benchmarks and expose pragmatic failures of state-of-the-art models.
Best model: 64.73%. Humans: 84.5%.

