

Trained Multiple Frontier Models, Distinguished Research Scientist @fastinoAI, Theoretical Physics @Cambridge_Uni , 3,000+ GitHub Stars⭐️, Math Olympiad, Genius
Cambridge, United Kingdom
Joined January 2026
- Tweets952
- Following121
- Followers528
- Likes632
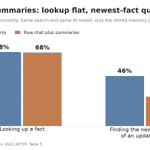




Adding summaries to an AI agent's memory made it worse at finding the latest version of a fact, even with the full chat still stored.
The AI model and the search method stayed the same. The only change was a summary attached to each piece of the raw chat. Looking up a fact stayed at 68%. Finding the newest version of an updated fact fell from 46% to 27%.
A summary is a cache, a copy of the chat written at one moment. Here, even with the original chat sitting next to it, adding summaries barely moved lookup and hurt most at what changed later. Knowing when a saved copy has gone out of date is one of software's oldest hard problems. Now it's agent memory's too.

Sources: Bao et al., arXiv 2610.30755 (Table 5; same chunking, embedding model and reranker, only the stored memory changes). Rewriting the chat as lists of single facts did worse still. With those single-fact lists, learning from examples in the chat fell from 48% to 15%.
A separate group (He et al., arXiv 2610.34073) tested 11 memory systems on 3 benchmarks with 3 models. By my count, plain two-round search over the raw chat did better in 90 of the 99 comparisons.
On timestamps: The plain-chat setup stored every message with its timestamp, and in this test each fact also carried a serial number (bigger means newer), which the summaries were told to keep.
Caveats: The first test used one answering model, and the paper reports no repeat runs. The second group says their benchmarks may suit plain search. Both are new preprints.
This isn’t surprising.
Once you observe how hard the brilliant people work at the incredible academic institutions across China and India it makes you wonder why the Nobel prizes are mostly going to the ivy leagues and Oxbridge.
simply put it’s a graph problem.
The nodes at these prestigious institutions are densely connected with all the cream of the crop around the world.
Game theoretically: if you’re a renowned researcher in any country, you can pick whoever you want to associate with, and you’ll more often than not pick to collaborate with someone at one of those prestigious institutions.
All connections tend to cluster densely this way


When two maps of an AI model's concepts disagree, it isn't necessarily noise, their agreement usually matches neurons.
A map is one run of a concept-finding tool on the model, each run from a different random starting point. This is the same tool people are using to find “single neuron concepts”.
The tool can only reliably lock onto a direction where the data has a distinctive, non-Gaussian shape: anything but a plain bell-curve blob. Where the data is a round, featureless cloud, every direction looks about the same, so each run picks its own.
In the model pictured, each neuron's switch (its activation function) squashes negative values to near zero. That folds the cloud into an L along the neuron axes, so that's where runs most often agree.
So when runs disagree, the structure can still be real: the data may just not pin down its exact direction.

GLiDE is not only the Frontier but ALSO Pareto Frontier in EVERY category. Size, speed, and low calibration error. (All according to Hugging Face's own independent evaluations.)
Think about that... GLiDE is not only the best Decision Model in the world (beating OpenAI and all the top labs) by a large margin but it's also the Pareto Frontier in every category. All independently and officially evaluated by Hugging Face.

Here's my technical report on how we did it: 🔗 fastino.ai/blog/training-gli…

Professor Eldad Tsabary: “GLiDE is the first specialized decision model in my benchmark to outscore GPT-6 Sol” 🤯
Let that sink in… our tiny 27B GLiDE Decision Model beating a monstrous SEVERAL TRILLION parameter GPT 6 SOL on an unseen, hidden benchmark 🤯🤯🤯
We obviously couldn’t have trained it for this benchmark as we had no clue about it while training GLiDE.
We not only beat Jev but also OpenAI’s GPT 6 SOL, which many experts even called AGI.
Feeling blessed 🙏


Have you ever wondered “How do the top labs train a Frontier Model?”
Read this technical report I wrote on how we trained the Best Decision Model in the world (according to Hugging Face’s official rigorous rankings). fastino.ai/blog/training-gli…
Keep in mind, that we did it with a fraction of the resources that the other brilliant frontier labs on the leaderboard have. They have made incredible models and deserve applause as well.
Official Jev Decision Index leaderboard: huggingface.co/spaces/multim…

We used a training technique inspired from the revolutionary chess model AphaZero. We taught the model to think and then distilled the reasoning back into the weights so you had the same performance without needing the slow and expensive chain of thought tokens.
Therefore taking the expensive and slow chain of thought reasoning and making that reasoning happen in the latent space during one single forward pass.
We basically used the same model as the teacher and student and performed self distillation.

Sahibzada Allahyar retweeted

The best decision model in the world. GLiDE v1.2 is here (and it’s multimodal).
#1 on the @huggingface Decision Index, beating the next best model by 1.7 points.
The benchmarks are genuinely impressive:
- 71.5 full score
- 82 ms latency on NVIDIA RTX PRO 6000
- 1.9% calibration error on held-out decisions (one of the lowest on the index)
This model is smart, fast, well-calibrated, and open weight. Everything a good decision model should be. We’ve also dropped our pricing to $0.04 / million input tokens.
Try it today. Use promo code GLIDEIS1 for $10 in API credits.
API: agent.fastino.ai/
Weights: huggingface.co/fastino/GLiDE

Sahibzada Allahyar retweeted

Our newest decision model is the world's best decision model.
Introducing GLiDE v1.2, the #1 model on the @huggingface Decision Index.
With an overall score of 71.5, GLiDE v1.2 also has one of the lowest calibration errors on the entire Decision Index, meaning its confidence more closely reflects how often its answers are correct.
Beyond improved benchmark performance, it also adds support for multimodal inputs, enabling decision-making using text, JSON, and images.
We are excited to release the model weights on Hugging Face. For hosted inference, you can also run GLiDE v1.2 through the Fastino API at $0.04 / million input tokens.
Use promo code GLIDEIS1 for $10 in API credits.
Model weights: huggingface.co/fastino/GLiDE
API: agent.fastino.ai
Blog: fastino.ai/blog/training-gli…

Sahibzada Allahyar retweeted
We're proud to be a post-training partner with @NVIDIAAI, advancing the future of open weight models.

We’re releasing more open models to help teams across Europe build AI with their own data, on infrastructure they control.
Announced at GTC Berlin, the models help developers, researchers and enterprises build specialized AI agents, train robots, design proteins and develop quantum computers.
See what’s new: nvda.ws/4iwBMvF

Sahibzada Allahyar retweeted
One line Tinker migration:
docs.fastino.ai/training/mig…


Sahibzada Allahyar retweeted
The new Super Finance and Healthcare models are 🔥
huggingface.co/collections/f…

We collaborated with @NVIDIAAI on early access post-training. Spoiler alert: It's an incredible model to train!
Technical blog: fastino.ai/blog/nvidia-nemot…

Sahibzada Allahyar retweeted
Today we’re launching the Fastino Training API for supervised fine-tuning and reinforcement learning.
The Fastino Training API includes day-zero support for @NVIDIAAI Nemotron 3.5 Super VL, alongside Nemotron 3.5 Lightning.
Our API gives ML and research teams low-level control over post-training without requiring them to provision GPUs or operate separate training and generation systems.
A few highlights:
• Write your own SFT and RL loops in Python
• Train with importance sampling, PPO, CISPO, or DRO
• Run grouped sampling with token log probabilities
• Save and resume adapter and optimizer checkpoints
• Pay per token processed, not per GPU hour
• Spend 25% to 85% less than Tinker’s published rates
• Migrate existing Tinker workloads by changing only the server address and API key
Along with the Training API, we’re releasing two start-of-the-art open weight models fine-tuned on NVIDIA Nemotron 3.5 Super VL, specialized for finance and healthcare. Together, they improved performance across all 15 held-out benchmarks we measured.
And for a limited time, we’re offering discounted pricing on training for NVIDIA Nemotron 3.5 Super VL through the Fastino Training API.
Try it now: agent.fastino.ai/

This is huge.
This is THE cheapest training API in the world 🤯. @DhruvAtreja1 taking Fastino Labs to the moon.
To all my researcher friends, hop on this it’s a no brainer. You’ll get more GPU hours and flops for your dollar
Sahibzada Allahyar retweeted
@andrewdsouza fastino now serves the cheapest training API for ML teams
