
vit.cpp, modernbert, lightonocr
Joined January 2024
- Tweets535
- Following446
- Followers553
- Likes1.7K





Pinned Tweet
🚀 LightOnOCR-3 is out! 🦉
This time we go beyond OCR: text transcription, document layout, image descriptions and chart extraction, all in one model.
We release 3 sizes: 0.8B, 1B and 4B, all under Apache 2.0!

Said Taghadouini retweeted

Hi all, I have a new result I'm excited to share. It turns out that *all existing implementations* of softmax and cross-entropy (that's JAX, PyTorch, textbooks, etc) have a subtle bug --- two bugs, actually. A simple rewrite fixes both, and eliminates "slingshots" when grokking:
Said Taghadouini retweeted

First finetunes for LightOn landed over the weekend!!! So far, the finetunes are for medieval Latin 0.8B and 4B and cultural heritage English 0.8B and 4B. As expected, these models took to finetuning nicely and outperform my models from a few weeks ago. I think I can push more.


World-leading document recognition. Beyond text extraction.
Introducing LightOnOCR-3, our new family of state-of-the-art AI models for document intelligence.
Building on LightOnOCR-2, it recognizes text and handwriting, describes images, extracts data from charts and preserves document structure, all in a single processing step.
🏆 Leading benchmark results : ahead of Chandra-OCR-2, Mistral OCR 4.1 and dots.mocr on OlmOCR-Bench, and first among open-weight models on ParseBench.
📊 More information from every document : turn text, tables, images and charts into content your business applications can use.
⚡Compact and efficient: 0.8B and 4B versions, with document processing up to twice as fast as LightOnOCR-2.
🔓Apache 2.0 license: use, adapt and deploy the models on your own infrastructure.
From handwritten administrative files to financial reports and technical documents, make more of your information searchable and usable.
👉 Explore the models and benchmark results: huggingface.co/blog/lightona…
👉🏻Explore the model page on our Website : lighton.ai/research/lightono…
#LightOn #DocumentIntelligence #OCR

Said Taghadouini retweeted

🚀 Introducing ColGrep-Agent-2B!
An open 2B model, now integrated into NextPlaid via ColGrep, that runs locally to make coding agents more efficient.
With Claude Code:
→ 34% fewer API tokens
→ 40% lower API costs
All by delegating code search to a tiny agent.
Here's how 🧵
Said Taghadouini retweeted

Today we’re releasing LightOnOCR-3, the third generation of our OCR models—a joint effort with @staghado and @baptaubertin!
Here’s how we built its grounding data, and how intermediate checkpoints helped improve the annotations used for subsequent training. 🧵
Said Taghadouini retweeted

🚀 We just updated LightOnOCR! 🦉
LightOnOCR-3 is faster, more accurate, and brings new capabilities: it now tells you where everything is on the page, describes images, and pulls the numbers out of charts.
Three sizes (0.8B, 1B, 4B), still Apache 2.0.

Said Taghadouini retweeted

World-leading document recognition. Beyond text extraction.
Introducing LightOnOCR-3, our new family of state-of-the-art AI models for document intelligence.
Building on LightOnOCR-2, it recognizes text and handwriting, describes images, extracts data from charts and preserves document structure, all in a single processing step.
🏆 Leading benchmark results : ahead of Chandra-OCR-2, Mistral OCR 4.1 and dots.mocr on OlmOCR-Bench, and first among open-weight models on ParseBench.
📊 More information from every document : turn text, tables, images and charts into content your business applications can use.
⚡Compact and efficient: 0.8B and 4B versions, with document processing up to twice as fast as LightOnOCR-2.
🔓Apache 2.0 license: use, adapt and deploy the models on your own infrastructure.
From handwritten administrative files to financial reports and technical documents, make more of your information searchable and usable.
👉 Explore the models and benchmark results: huggingface.co/blog/lightona…
👉🏻Explore the model page on our Website : lighton.ai/research/lightono…
#LightOn #DocumentIntelligence #OCR
We also push quality further with multi-objective RLVR!
In the same training runs, we jointly optimize grounding, OCR across different document types, and empty-page handling.


Everything is released under Apache 2.0 on @huggingface
Models:
huggingface.co/lightonai/Lig…
huggingface.co/lightonai/Lig…
huggingface.co/lightonai/Lig…
Code + reproducible benchmarks:
github.com/lightonai/LightOn…
Docduck:
github.com/lightonai/docduck
blog:
huggingface.co/blog/lightona…

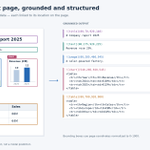
Why not just output HTML for grounding?
We use compact inline markers for region labels and coordinates to save on output tokens.
On the same 512 pages, our grounded outputs use 9–14% fewer tokens than Chandra 2 and Infinity Parser Pro 2.

How did we train grounding?
Turns out getting reliable document bounding boxes is quite hard.
We(@CavaillesAdrien) built an annotation pipeline combining multiple OCR and layout detectors, then aligned their outputs with our LightOnOCR-2 transcriptions.

What about document understanding?
On ParseBench, LightOnOCR-3 takes the top 2 spots among open-weight models:
🥇 4B: 75.1
🥈 0.8B: 74.6
Infinity Parser Pro (35B): 74.3
Chandra 2 (4B): 70.1
The 4B also leads on chart extraction and semantic formatting.

What's new compared to LightOnOCR-2?
We have added full page grounding with full backward compatibility for OCR only mode.
The models accept a single prompt "grounding" to steer between grounding and OCR only modes.
We also caption images and convert charts to tables


our next model does pretty well on this!
h/t @baptaubertin


We trained a document parsing model that's good at differentiating muffin vs chihuahua. We also provide precise bounding boxes for human review.
If your current document parser struggles with muffin vs chihuahua, please consider @reductoai r-1.
