




Steven retweeted

LiveBench finally reflects real-world performance
- Fable 5.1 and Astra are on top
- Opus 5.5, not far behind, excels at design
- Argon beats Terra, good at data analysis
- Google beats open-source for the first time
- DeepSeek is the top open-source model

Steven retweeted

Nemotron 3.5 Transcribe ranks #1 among open-weight models on the @huggingface Open ASR English leaderboard with a 5.33% average word error rate.
Download the model → huggingface.co/nvidia/NVIDIA…
Learderboard → huggingface.co/spaces/hf-aud…
2/

Steven retweeted

Today we’re releasing Underdog Bark 3.0, the #1 frontier speech model
It's a tiny 163 MB download as accurate as NVIDIA’s Parakeet (15x bigger). It beats OpenAI's Whisper large-v3 (57x bigger)
It's fast- transcribes 1 min of audio in <0.25s on a Macbook. On recorded meetings (AMI), Bark 3.0 gets 7.82% of words wrong. Parakeet gets 9.42%. OpenAI's Whisper large-v3 gets 13.63% error rate
Bark runs on both your Laptop & Phone. It’s free and open source under CC-BY 4.0
Try private on-device meeting notes & dictation, powered by Bark, in Underdog today: underdog.ai/bark

Steven retweeted
Gemini 4 Argon is now rolling out globally in Search!
Built to solve your hardest problems, Argon brings big improvements to tackling nuanced, multi-step tasks in AI Mode. It’s better at understanding your intent and following your instructions in back and forth conversations.
Available starting today for Google AI Pro & Ultra subs, tap the ➕ icon to switch over to Argon and test it out.
Steven retweeted

Gemini 4 Argon is here.
It’s available globally today for developers and enterprises in the paid tier of the Gemini API and the Gemini platform, for Ultra subscribers in Google Antigravity, and Ultra and Pro subscribers in the Gemini app and Search.
Hope you all enjoy it!
Steven retweeted

Claude now works inside Google Docs, Sheets, and Slides, and those files also open inside Claude.
In Google Workspace, Claude sits in a sidebar next to your file, reads what you have open, and edits it in place. You can approve each edit before it lands.
Steven retweeted

We heard you loud and clear. ChatGPT Voice can now:
- Use plugins like your email, calendar, and Slack.
- Be powered by GPT-6 Astra, Sol, and Luna.
- Be used in ChatGPT Work on web and mobile, so you can create docs, decks, sites, and spreadsheets or tackle complex tasks in the browser, just by talking.
Rolling out globally today in the latest version of the app.
Steven retweeted

@NVIDIAAI Nemotron 3 Diarization just dropped!
FluidVoice is shipping it Day-0
Introducing FluidMeet —
Be the best notetaker in the meeting, with barely any effort.
Meeting transcriptions built for privacy:
-> Fully processed on your device
-> Captures - Who spoke "what" and "when"
-> No bots. No cloud. OSS.
Public beta is out. Link & blog below
Steven retweeted

Muse Voice Transcribe is on the Open ASR Leaderboard, and the results can seem surprising 😲
It's an important reminder to take rankings with a grain of salt, as the datasets and the other models considered can significantly change the story!
For ASR, this is especially important when considering the right model that meets your application, language(s), accent(s), and deployment environment.

Introducing Muse Voice Transcribe, the first real-time audio perception model from Meta Superintelligence Labs.
Muse Voice Transcribe delivers real-time streaming ASR, diarization with 20+ speakers, and endpointing. It’s multilingual with seamless code-switching and improves accuracy with language, keyword, and context biasing.
The model ranks first on @ArtificialAnlys streaming speech-to-text and on public diarization benchmarks.


Steven retweeted

StepFun has released StepAudio 3 ASR, ranking #1 on the AA-WER Index for non-streaming Speech to Text with 1.7% WER, a notable improvement on StepAudio 2.5 ASR (4.7%)
StepAudio 3 ASR is StepFun's new Speech to Text model, available through the StepFun API for non-streaming transcription, and the first StepFun model to reach the top of our non-streaming Speech to Text leaderboard.
Key takeaways
➤ Accuracy: StepAudio 3 ASR scores 1.7% on the AA-WER Index, effectively tied with Alibaba's Fun-Realtime-ASR-preview at 1.7%. It leads on AA-AgentTalk, our held-out voice-agent dataset, at 1.4%, but trails on long-form Earnings22 calls at 2.8%, where Fun-Realtime-ASR-preview scores 1.8%
➤ Speed: The model transcribes at a speed factor of 88x real time, behind MAI-Transcribe-2 at 374x, Smallest AI Pulse Pro at 285x and Grok Voice Transcribe 2.0 at 154x, roughly level with ElevenLabs Scribe v2 at 84x and Gemini 3.5 Transcribe at 91x, and ahead of Fun-Realtime-ASR-preview at 20x
➤ Price: StepAudio 3 ASR costs $0.40 per hour, or $6.67 per 1,000 minutes, the most expensive of the five most accurate models. MAI-Transcribe-2 and Grok Voice Transcribe 2.0 cost $1.67 per 1,000 minutes and ElevenLabs Scribe v2 $3.67, so the trade-off is top-tier accuracy on conversational audio at a higher cost per minute
See more details below ⬇️

Steven retweeted
SpaceXAI has released Grok Voice Transcribe 2.0, taking the #1 spot for Final Transcript accuracy and First Partial Transcript accuracy on AA-WER Streaming with 2.7% WER at 0.49s after end of speech
Grok Voice Transcribe 2.0 is @spacexai's new Speech to Text model, succeeding Grok Voice Transcribe 1.0 (previously Grok Speech to Text). It improves streaming Final Transcript WER from 3.9% to 2.7% and non-streaming AA-WER from 4.0% to 2.3%. It is available through the SpaceXAI API for both streaming and non-streaming transcription, at the same price as its predecessor.
Key takeaways
➤ Final Transcript: Grok Voice Transcribe 2.0 achieves 2.7% WER at 0.49s after end of speech. It is more accurate but slower than Muse Voice Transcribe at 3.1% and 0.16s, and ElevenLabs Scribe v2 Realtime at 3.6% and 0.14s. It is also more accurate, though slightly slower, than Cartesia Ink-2 (semantic endpoints) at 3.4% and 0.43s
➤ First Partial Transcript: The model achieves 3.4% WER at 0.49s, just ahead of Muse Voice Transcribe and ElevenLabs Scribe v2 Realtime on accuracy, both at 3.6%, though slower than both at 0.13s. It is more accurate but slower than Cartesia Ink-2 (semantic endpoints) at 4.9% and 0.17s, and Cartesia Ink-2 (external endpoints) at 4.0% and 0.07s
➤ Non-streaming: Grok Voice Transcribe 2.0 scores 2.3% on AA-WER, placing #5 of 59 models. It sits behind Alibaba's Fun-Realtime-ASR-preview and StepFun's StepAudio 3 ASR at 1.7%, Microsoft AI's MAI-Transcribe-2 at 2.0%, and ElevenLabs Scribe v2 at 2.2%, with a speed factor of around 160x
➤ Price: Grok Voice Transcribe 2.0 costs $0.20 per hour for streaming, or $3.33 per 1,000 minutes. This is just above Muse Voice Transcribe at $3, below Cartesia Ink-2 at $4, and around half the $6.50 charged for ElevenLabs Scribe v2 Realtime and Deepgram Flux. Non-streaming transcription costs $0.10 per hour, or $1.67 per 1,000 minutes
Congrats to @elonmusk and the @spacexai team on the launch!
See more details below ⬇️

Steven retweeted
Check out Muse, your personal AI agent. Redeem my code in Settings within 48 hours of joining and we'll both get 1 billion Muse tokens.
muse.ai/join


If you want 1 Billion free @Muse tokens…
Here’s your invite:
Check out Muse, your personal AI agent. Redeem my code in Settings within 48 hours of joining and we'll both get 1 billion Muse tokens.
Code: 7AOHEA
muse.ai/join

Steven retweeted

Google starts rolling out the Live Translation UI in Gemini Live
A new "Turn on live translation" option in voice settings allows Gemini Live to translate spoken conversations on the fly, displaying translation captions during multilingual dialogue
✅ Details - androidauthority.com/gemini-…

Steven retweeted

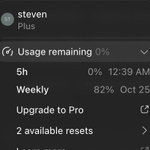
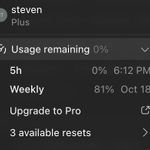
Tomorrow we will bring back the 5h limit for Plus accounts across ChatGPT Work and Codex. I had mentioned this a while ago, but then postponed it.
This is necessary as (a) the 5h limit allows us to smoothen the load on our compute, allowing to keep the plan generous in terms of weekly usage and (b) users on the Plus plan are relatively casual and new users, but then also just accidentally eat through their whole weeks usage and then are confused, making it not a great experience.
We are for the upcoming months keeping the 5h limit not enabled for Pro $100 and Pro $200 subscriptions.
Steven retweeted

We launched the Meta AI Mac OS app today! 🚀
I particularly love the dictation feature which allows me to dictate anywhere on my computer with ultra high accuracy. Just hold down 'fn' and yap!
Steven retweeted

📢Meet Qwen3.8-Max — our most capable model to date.
Next week, the open weights of Qwen3.8-Max will be released, and Qwen3.8-27B is also going open-weights to meet you all!🎉
Qwen3.8-Max, a new bar for coding and cowork at 2.4T parameters:
- Autonomous coding: 10+ days of self-evolving development, from empty folder to production without hand-holding, complete project trace in the GitHub:github.com/qwen-code-dev-bot…
- Real work, real results: Production-quality deliverables across hundreds of professions.
- Long-horizon mastery: System-level autonomous planning with closed-loop adaptive learning, driving 500+ turns of chip design optimization and 365 days of e-commerce strategy.
- Native multimodal intelligence: Vision isn't just input — it's a continuous feedback loop for planning, execution, and self-correction.
💰Pricing:
Input: $2.0 / M tokens
Output: $6.0 / M tokens
Implicit Caching: $0.25 / M tokens
Start building with Qwen3.8-Max! 🚀
📖 Blog: qwen.ai/blog?id=qwen3.8
✅ Qwen Studio: chat.qwen.ai/?models=qwen3.8…
⚡ API: qwencloud.com/models/qwen3.8…

Steven retweeted
Introducing Qwen-Audio-3.0-ASR-Flash:
More context-aware. Stronger domain-term recognition.
🚀Our latest ASR model upgrades:
• Context consistency
• Domain-term recognition
• Custom hotwords
• Speech polishing into structured transcripts
⚡️In internal tests:
• Medical term recall: 95.36%
• Industrial term recall: 93.24%
Qwen-Audio-3.0-ASR-Flash-Streaming:
alibabacloud.com/help/en/mod…
Qwen-Audio-3.0-ASR-Flash-Filetrans:
alibabacloud.com/help/en/mod…
Qwen-Audio-3.0-ASR-Flash:
alibabacloud.com/help/en/mod…

Steven retweeted

Open-source ASR just took the top spot.
Audio8 ARK-ASR-3B now ranks #1 on the @huggingface Open ASR Leaderboard with a 4.76 Mean WER.
Our 0.6B model also ranks in the Top 5.
Two model sizes. One open speech stack. Thread ↓
🤖 Made with AI

Steven retweeted

Gemini Spark 🤝 @GoogleChrome
Gemini Spark is now integrated with auto browse in Google Chrome. With your permission, Spark can handle web tasks for you right in your Chrome browser, like scheduling apartment viewings or auto-filling flight info.
Steven retweeted
Kimi K3 scores 57 on the Artificial Analysis Intelligence Index. Its intelligence is comparable to Opus 4.8 and GPT-5.5 but remains behind Fable 5 and GPT-5.6 Sol. Moonshot AI has expressed plans to release the 2.8T parameter model's weights, which would make it the leading open weights model
Key results:
➤ Strong agentic task performance: @Kimi_Moonshot's Kimi K3 reaches an Elo rating of 1668 on GDPval v2. This is a marked improvement over K2.6’s 1190, surpassing GLM-5.2 (1514), GPT-5.5 (1494), and Claude Opus 4.8 (1600). However, it still lags behind Claude Fable 5 (1760). Kimi K3 also scores an impressive 53% and takes the #1 position on AutomationBench-AA, our implementation of Zapier’s Agentic SaaS workflow evaluation.
➤ Second-highest performance on AA-Briefcase (agentic knowledge work): On our private long-horizon knowledge work evaluation, Kimi K3 reaches an overall Elo of 1547, +732 points from Kimi K2.6 and behind only Claude Fable 5. It is well-rounded: its rubric scoring and analytical quality almost reach Claude Fable 5’s scores, while GPT-5.6 Sol continues to outperform other leading models on presentation quality.
➤ Set to lead open weights models once weights are released: Moonshot AI has not yet released the weights but expressed plans to do so. Once available, Kimi K3 would clearly lead other open weights models including GLM-5.2 (51) and DeepSeek v4 Pro (44). However, at 2.8T parameters, it is significantly larger than its open weights peers (eg. GLM-5.2 at 753B params and DeepSeek V4 Pro at 1.6T), as well as the Kimi K2 to K2.6 models (1T params).
➤ Cost per task ($0.94) is similar to GPT-5.6 Sol ($1.04), ~1/2 the price of Opus 4.8 ($1.80) and higher than open weights peers: Moonshot AI’s pricing for K3 is significantly higher than their K2 pricing (K3’s output token price is $15/1M tokens while K2.6 was $4). This positions the model as cheaper on a cost per task basis than Opus 4.8, similar to GPT-5.6 Sol ($1.04) and more expensive than open weights peers, GLM-5.2 ($0.32) and DeepSeek V4 Pro ($0.04)
➤ Improved token efficiency alongside higher intelligence: Kimi K3’s token usage on the Artificial Analysis Intelligence Index decreased significantly, using 21% fewer output tokens than K2.6. The new model used approximately 132M output tokens to complete all nine evaluations, compared to approximately 166M for K2.6, while achieving higher scores.
➤ Native multimodal capabilities: Kimi K3, like K2.6, is released with native image and text multimodal input. If weights are released, this will position Kimi K3 as one of the leading open weights models with multimodal input capabilities
Other model details:
Context window: 1M
Size: 2.8T total parameters
Pricing: The first-party API is priced at $3.00/$15.00 per 1M input/output tokens, with cached input discounted 90% to $0.30 per 1M tokens.
Modality: Native multimodal input supports text and images, and the model remains text-only for output.
Accessibility: Accessible at launch through Moonshot’s first party API. Model weights are not yet released but Moonshot AI has expressed plans to do so.
