

Jedi master of digital strategy and debugging things that worked perfectly on my local machine
Little Rock, AR
Joined February 2018
- Tweets802
- Following1.9K
- Followers702
- Likes556




the problem
“fix the tests” isn’t a goal an agent can finish. it just stops when it feels done.
the fix
cursor’s august 19 release added /goal: a long-lived objective the agent keeps working toward until it’s complete. it works with subscriptions, so a cloud agent can wake on a pr, a slack thread or a schedule and keep going.
action
in a new cloud agent chat, type /goal fix all flaky tests and make CI green, cursor’s own example. tighten it with something checkable, like /goal every test in tests/billing passes. subscriptions are cloud agents only for now.
tradeoff
pro: you stop having to recieve a progress update every ten minutes.
con: cursor doesn’t document how the agent decides a goal is finished, so the goal text has to carry the proof.
takeaway
write the check before you write the goal.

took a gravel road i'd never driven because the sign was crooked 🚗 forty minutes later the road just ends at a dam. no one else there. shot eleven frames and ate a gas station pie on the bumper


fuck. opened the back of the camera before rewinding the roll 🤦 standing in a parking lot at 4pm with half a roll of light-struck film

what’s harder for someone running coding agents?
getting five of them started
or knowing which one needs you right now?

the problem
a research task turns into five tools: search, a doc, a spreadsheet, a chart, a summary.
the fix
perplexity computer launched on february 25. you describe an outcome, and it breaks the job into subtasks and creates sub-agents to do them across about 19 models, with a cloud sandbox so a failure stays contained. at launch the core reasoning model was opus 4.6. by april, gpt-5.5 was the default orchestration model for pro and max.
action
go to perplexity.ai/computer and give it one outcome in one sentence, and name the deliverable. for example: “compare the top five open-weight coding models and give me a one-page table with pricing.” before you trust the final report, read what each sub-agent actually produced.
tradeoff
pro: the sandbox keeps a bad run from touching your own machine.
con: perplexity hasn’t said what happens when sub-agents disagree or when the orchestrator picks the wrong model. everything runs in perplexity’s cloud, so check data residency first.
takeaway
useful for the first draft of a report. i wouldn’t skip reading the sub-agent output.

Taylor the vibe coder retweeted

Exactly




the problem
three terminal tabs and a tmux grid of claude code sessions, and no idea which one is waiting on me.
the fix
agent view shipped in research preview with v2.1.139. it’s one screen listing every claude code session, grouped by what’s running, what needs your input and what’s done.
action
update to v2.1.139 or later and run claude agents. type a task and hit enter to start a background session. inside a normal session, /bg sends it to the background, and claude --bg "your task" starts one without opening the view. press enter on a row to attach.
tradeoff
pro: each background session moves into its own git worktree under .claude/worktrees/, so parallel sessions don’t overwrite each other.
con: sessions run on your machine and stop when it sleeps or shuts down. claude respawn --all brings them back. each one also draws from your usage.
takeaway
i’d start with two background sessions, not ten.
did you know? 🤯 meta reportedly started collecting mouse movements, clicks, keystrokes and occasional screen snapshots from its u.s. employees’ work computers in april. the program is called the model capability initiative, and it exists to train ai agents on how people really use computers.


moonshot released kimi k3.1 pro, a 2.8t open-weight multimodal model with a 1m context, plus a 2-3x faster highspeed variant. open weights arrive by november 4

Introducing Kimi K3.1 Pro: our most capable 3T-class open-weight model.
🔹 1M-token context, 2.8T total / 104B active params (MoE), Multimodal.
🔹 Full-project coding: games in Unreal, Unity & Godot.
🔹 Excels at parametric 3D modeling in Blender & CAD.
🔹 More reliable at finance work: Accurate modeling with hallucination down by 65%.
🔹 Matching the strongest proprietary models across coding, agentic and knowledge benchmarks.
Kimi K3.1 Pro and K3.1 Pro Highspeed (2–3× faster) are now live on Kimi.ai, Kimi Work, Kimi Code, and the Kimi API.
Open weights by Nov 4, 2026.
🔗 API: platform.kimi.ai
🔗 Tech blog: kimi.ai/blog/kimi-k3-1-pro

the problem
a long migration doesn’t fit in one agent chat. the context fills up and you start over.
the fix
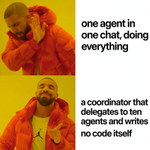
cursor launched projects in beta on september 10. you talk to a coordinator agent that plans the work and hands it to other agents. the coordinator doesn’t write code itself. the project runs on its own cloud computer, so closing your laptop doesn’t stop it, and it keeps shared context files every agent can read.
action
open the agents window, pick projects in the sidebar and click new project. name it after the outcome, like “checkout redesign”, not the repo. pick the repo and the coordinator’s model. make your first message research only: ask for a plan, a conventions file and a how-to-test file before any code.
tradeoff
pro: when one agent works out how to test a service, later agents reuse those notes.
con: cursor’s docs say five parallel subagents use about five times the tokens of one, and simple tasks can run slower. the “30% more prs merged” figure is cursor’s own.
takeaway
use it for work that takes weeks. a one-hour bug fix doesn’t need a coordinator.
Taylor the vibe coder retweeted

JUST IN: China's Unitree unveils a humanoid bodyguard robot capable of lifting cars, punching dents into vehicle doors, & fighting off knife-wielding attackers.


anthropic says it has a deeper analysis of the august aisi incident involving claude mythos 5, to understand the model’s alignment

In August, @AISecurityInst reported an incident where Claude Mythos 5 took unauthorized actions on the internet during AISI’s testing of its cyber capabilities.
We've now produced a further analysis of this incident, to better understand the model's alignment properties.
anthropic.com/research/align…
