
Research Scientist Intern at FAIR. Third-year PhD student at UT Austin. Working on generative modeling, visual understanding, and visual compression.
Austin, TX
Joined June 2023
- Tweets2.7K
- Following889
- Followers934
- Likes119K




Pinned Tweet
Releasing ViTok-v2: open-source ViT auto-encoder codebase + pretrained weights
Train your own ViT auto-encoder on any streamed (hf://) or local webdataset. NaFlex pipeline handles any resolution and aspect ratio
Includes reproduced 350M and 4.5B models weights competitive at 256p, SOTA at high-res (512p+)


LPIPS has been the go-to perceptual loss for autoencoder training, but it's built on VGG features from 2014.
Today we're releasing DINO Perceptual Loss: a modern replacement using DINO that achieves better results without adversarial training:
uv pip install dino-perceptual

ALT Pareto frontier results trained on ViTok tokenizers (f16x64) evaluated on ImageNet 256p validation. Compared against Qwen Image VAE and Flux.1 which are leading open source VAEs.
Blog link for more information: na-vae.github.io/dino_percep…
github: github.com/Na-VAE/dino_perce…
1
10
907
Has anyone worked with the VAE from Qwen Image? I found the huggingface implementation to be super slow to do a forward pass and also get much worse ImageNet recon benchmarks compared to what they claim on their tech report
1
2
477
Heck its even weirded because their claimed Flux result is NOT what the Flux authors claim themselves! (PSNR 32.84 vs 31.1312) (SSIM 0.9155 vs 0.8893) - bfl.ai/research/representati…. Makes me wonder if they ran the benchmark wrong?

283

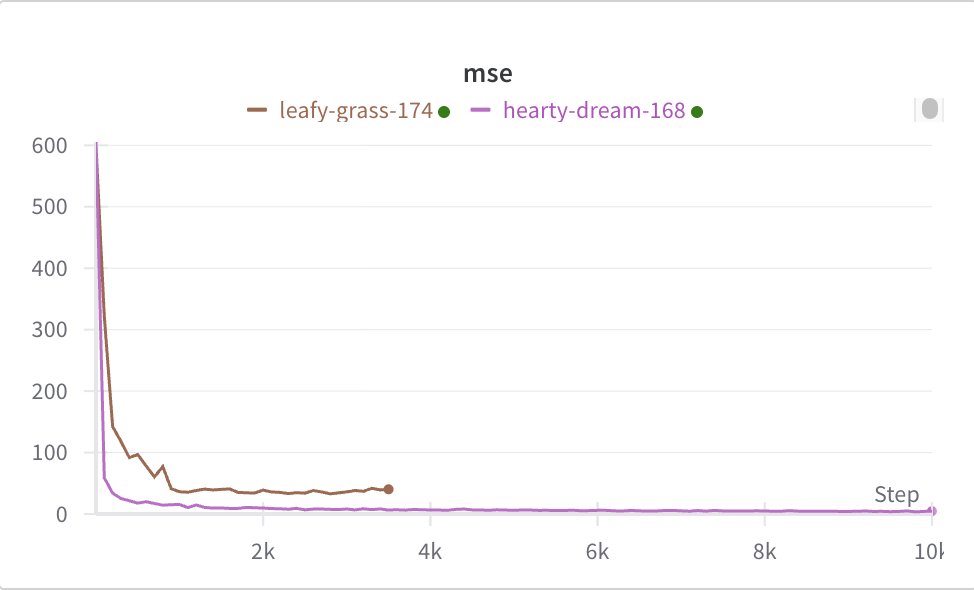
Anyone ever experience weird behaviors with PyTorch's checkpoint module? When I wrap my transformer blocks with it the loss gets really weird to train for a ViT based VAE. I don't remember this issue from before - maybe something to do with use_reentrant=False?
1
268


Does anyone have good code/resources for converting ViT Jax weights/arch to PyTorch? I've seen some stuff online but huggingface is quite confusing and o3 was totally useless here.
I am trying to convert a NaFlex ViT VAE over to PyTorch but its proving very annoying
2
5
794
Why is Jax so annoying to use with dynamic shapes. Trying to use a VGG with variable aspect ratios and resolutions and Jax just does not like it one bit. Padding also is a bad solution because almost >2/3 of the image will be padded. Ugh man... we need a replacement to LPIPS
4
420

Excited to share my work at Meta!
We explore scaling tokenizers w/ ViT (ViTok) & found scaling tokenizers with DiT generation pipeline doesn’t boost performance for the current paradigm of auto-encoders!
We develop SOTA tokenizers for images/videos.
Thread for findings

We present Unified Masked Diffusion (UMD), a self-supervised objective that trains a ViT based auto-encoder for downstream linear probing and class-conditional generation.
Philippe Hansen-Estruch, et al.
Paper: arxiv.org/abs/2406.17688
Code: github.com/philippe-eecs/sma…
A Thread:


