




i haven't touched it yet, no access, so this is all straight from deepmind
open question, what's the first world you'd build, a game level, a product demo or your own office?
what testers are using it for, per deepmind's blog
• filmmakers running multiple "takes" of a scene live
• turning one archival photo into an explorable scene
• game devs going from idea to explorable prototype before writing engine code
• enterprise teams testing "zero-to-one" scenario generation
deepmind says every genie 4 video and audio output will carry a SynthID watermark
no pricing or date yet, just a waitlist in project genie!

straight from deepmind:
"steer scenes in real time using natural language"
"has been released as a research preview to trusted testers"
so the access ladder looks like
→ trusted testers, right now
→ google ai ultra subscribers in project genie, "coming soon"
→ gemini api + ai studio early access partners, also soon!

@GoogleDeepMind dropped genie 4, a real-time world model you steer w/ plain text!
per deepmind, it generates the world and its audio live
▸ move the camera, change the weather, add characters mid-scene
▸ ambient sound, music and dialogue made w/ the world
▸ research preview, trusted testers only for now!


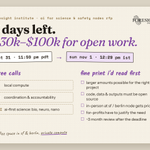
3 days left on @foresightinst's rfp and the local compute call is the one i keep rereading
they're asking for:
→ a prototype ai cluster an average person can set up at home
→ software that runs it without expert knowledge
→ models where the hardware pays for itself, like selling idle compute on openrouter
→ setups that work across different connectivity and electricity environments
if you've been running models on your own gpu in india, that last line is basically your daily life
fine print i'd read before applying:
• typical grants are $30k–$100k, bigger is possible
• code, data and outputs all have to be open source
• they prioritise people who'll work in person at the sf or berlin node
• for-profits have to explain why they need grant money
• review takes ~3 months, no individual feedback if you're rejected
deadline is oct 31, 11:59 pm pdt
for us that's sun nov 1, 12:29 pm ist
haven't applied myself, just didn't want anyone here missing it by a timezone


Four days left to apply for our Request for Proposals.
Up to $100K in grant funding, office space in SF and Berlin, community, and compute for open AI for science and safety projects. Three calls:
• Local Compute
• Coordination and Accountability
• AI-first Science: Bio, Neuro, Nano
Deadline: Oct 31. Apply: foresight.org/grants/ai-scie…
Links to each open call in thread.

tonight in ist, if you trade us stocks from india
• 11:30 pm, fomc rate decision
• 12:00 am, fed chair's presser
• 1:30 am, us market close
• 2:00 am, alphabet earnings call
• 3:00 am, microsoft earnings webcast
and $GOOGL + $MSFT never close as hip-3 perps on @tradexyz, xyz:GOOGL had ~$129m oi and xyz:MSFT ~$37m on @HyperliquidX this afternoon
the kit is open source, anthropics/single-agent-loop-kit on github
copy the skill into .claude/skills, open claude code in your agent repo and say "Run the single-agent-loop skill."
it audits first, stops before any paid run w/ a token estimate, and keeping a subagent counts as a fine outcome too!
full guide: claude.com/resources/article…

the part most people will skip, the evals
• 10 golden examples is enough to start
• fold one subagent at a time, score before + after
• look at which tasks flipped, not just the total
• run each task more than once
in their sample support agent, folding one subagent cut latency but broke a process that had been passing, and it only showed up in 1 of 2 runs
everything else gets folded in
→ steps, rules, judgment calls → a skill
→ actions, live data, approvals, validation → a tool
→ policies, specs, reference docs → a knowledge base behind a lookup tool
group tools by user intent, they say tool choice tends to degrade past 30-50 tool definitions
loading skills + tools only when needed is part of how they cut claude code's system prompt by 80%+ for newer models
keep a subagent only if one of these is true
• one loop measurably degrades from context bloat
• tasks run in parallel and need fresh context you throw away after
• one agent can't pick the right tools, or the prompt has conflicting instructions
and even then, call it as a tool w/ a structured result so the main agent keeps the conversation

ALT Screenshot of Anthropic's article listing when to use subagents, and noting agent architectures often become a copy of the org chart (Conway's law).
@AnthropicAI is now telling teams to fold most subagents back into one agent loop
across several enterprise deployments, one agent w/ skills frequently beat both the one-giant-prompt setup and the subagent setup on quality, often cheaper and faster per task
they shipped a kit for the migration too, here's the triage i pulled out of it

ALT Decision tree from Anthropic's guide: keep a subagent if context bloat, parallel fresh-context tasks, or tool-selection conflicts apply, and call it as a tool; otherwise fold it into one loop as a skill, a tool, or a knowledge base.
run it locally w/ the commands from the card:
brew install llama.cpp
llama-cli -hf LiquidAI/LFM3-1.7B-GGUF:Q4_K_M --temp 0.1 --top-k 50 --repeat-penalty 1.1
the card says you need an LFM3-compatible llama.cpp build, a fresh build from main worked
clip is a real run on a plain linux cpu box, no gpu, 1.1G Q4_K_M file, 39 tok/s on that run, w/ a long think block before the answer!
from liquid's blog:
"six 2B-class models (text, vision, audio, omni, and decision) trained from LFM3-1.7B-Base"
"LFM3-1.7B to outperform our previous LFM2.5-2.6B while using 35% fewer parameters"
from the model card:
"at 4-bit precision, it takes about 1 GB of memory"
→ built for local agents, tool calls, structured outputs
→ the card itself says skip it for agentic coding or complex multi-step reasoning!


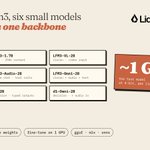
@liquidai just dropped lfm3, six open-weight models around 2B params on one backbone!
text, vision, audio, omni and two decision models
▸ liquid says the text model fits in about 1 GB at 4-bit
▸ 256k context on LFM3-1.7B
▸ every model fine-tunes on a single GPU, per the blog


Introducing 𝙻𝙵𝙼𝟹: our new generation of Liquid Foundation Models. With a new tri-hybrid architecture and new multimodal encoders, the LFM3 family is the ideal model suite for specialized intelligence.
> 6 model instances, across text, audio, vision, and omni modalities, generative and decision models.
> 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱: text, 256k context window.
> 𝙻𝙵𝙼𝟹-𝚅𝙻-𝟸𝙱: vision-language model with video-input support for spatial understanding
> 𝙻𝙵𝙼𝟹-𝙰𝚞𝚍𝚒𝚘-𝟸𝙱: tool calls, voice chat, reasoning in 18 languages.
> 𝙻𝙵𝙼𝟹-𝙾𝚖𝚗𝚒-𝟸𝙱: an omni model combines vision, audio, and language.
> 𝚍𝟷-𝟸𝙱 and 𝚍𝟷-𝙾𝚖𝚗𝚒-𝟸𝙱: decision models with typed outputs and calibrated probabilities in a single pass. Omni adds audio input.
> fine-tune on 1 GPU.
> a new tri-hybrid architecture
> architecture optimized for 14 processor classes across GPUs, CPUs, and NPUs.
> 𝙻𝙵𝙼𝟹-𝚅𝙻-𝟸𝙱 is a beast. It performs competitively with Gemma 4 12B (6x larger), and Gemini 3.5 Flash Lite, and GPT-5.6 Luna, with 1.9B parameters.
> 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱 is #1 on the Pareto frontier of device intelligence 𝚙𝚒𝚙𝚎𝚝𝚝𝚎.𝚕𝚒𝚚𝚞𝚒𝚍.𝚊𝚒
Every modality for specialized intelligence. Pick the one that fits your use case, customize it, and run it on-device.
1/ 🧵
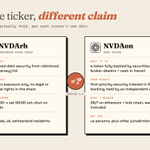
same ticker, i'd be careful w/ the usdc/usdt comparison though
• @RobinhoodApp's are tokenized debt securities from robinhood assets (jersey), economic exposure only
• @Ondo's say they're fully backed by securities at us broker-dealers, w/ a first-priority security interest for holders
• robinhood's mint + redeem shuts on weekends, ondo's 11 paired ones redeem 24/7
the pool treats them 1:1, the claims underneath aren't the same, and that drift is what stablepair's dynamic fee is there for

ALT Comparison card: NVDArh is a tokenized debt security from Robinhood Assets (Jersey) with economic exposure only and weekday mint/redeem; NVDAon is backed by securities at US broker-dealers with a first-priority security interest and 24/7 mint/redeem.

One of the largest tokenized stock issuers is now on Robinhood Chain, with Uniswap as its liquidity layer
@Ondo Stocks and Robinhood Stock Tokens are the same shares, pegged 1:1 like USDC/USDT
That’s what StablePair Hook was built for, now in its first use beyond stablecoins
read the q3 release so you don't have to
• crypto revenue $120m, down 55% yoy
• equities revenue $121m, up 41%
• robinhood chain, first quarter on mainnet, $80b+ dex volume and $50m+ chain fees
the app's crypto trading revenue is shrinking while the chain it launched in july is already making fees, that's the tokenization bet in one release!

$XTEN doesn't exist yet and it's already trading on @HyperliquidX, so what are you actually pricing?
• it's a hyperp, the oracle is an 8h ema of its own mark price, no spot feed at all
• mark is capped at 3x that ema
• max 3x leverage, isolated only
pulled it just now, mark ~$0.260, ~$647k oi, ~$1.7m 24h volume, that's ~$260m implied fdv
when momentum runs one way, funding leans hard the other way for the next 8h, check it before you hold!
