




Don't know if I should spend less time coding and more on farming engagement, but either way here's a neat cat simulation.
It's not entirely accurate (still needs to model viscosity and surface tension), but it was more of a stress test anyway, made by a new 1.66 bpw quant of Qwen3.8-Flash-Next running on one RTX 5090; no experts offloaded to the CPU, only vision tower in pinned memory (negligible overhead), and embeddings on disk.
Stable inference throughout, no reasoning loops, just smooth sailing at 200-300 t/s (and a lot of compacting since one 32 GB GPU still doesn't leave a lot of room for context, even with cache quantization).
Get yours today at huggingface.co/turboderp/Qwe…
Is anyone else confused why everyone's all hyped about using "decision models" to solve deterministic problems, instead of leveraging AR models' ability to implement classical algorithms?
I challenge any Jev or Jev-like harness to compete with A* in 80 lines of JavaScript. I get the selling point of "you don't need to write any task-specific code, the decision model just figures it out." But in this case the cost was all up-front: four minutes with Astra-medium, and a one-line prompt. What am I missing?
I doubt I'm the first to notice this, but MiMo-V2.6-Pro seems to have a lot of redundant weights.
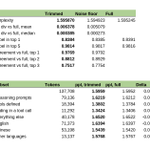
If you remove the expert blocks from layers 1 through 12 and the attention blocks from layers 1-4, 6 and 8-11, end-to-end KLD is largely unaffected. Their contribution to the residual is on the order of BF16 rounding errors.
Overall, it looks like you can trim away 17% of the model's ~1T parameters and still end up with largely the same model. That's six whole Qwens.
Is this known, or can anyone confirm?


turboderp retweeted
keepandroidopen.org/cta/
The *only* reason I have been using Android for the last 8 years is the fact that I have control of my device, I can hack on it and write software for it and sideload it without begging anyone for the privilege. As soon as Google's "Close Android" initiative goes into effect, I will buy an iPhone and I won't develop on Android again.
@Google - Don't do this. Turn around. Cancel. Change your mind. Realize that you just made a stupid mistake after one too many beers, and you didn't actually mean it. And you are sorry for the confusion and chaos. Then this will just be a bad memory that fades away - instead of the permanent destruction you are about to inflict to your own platform, and millions of customers. And the major boon you are about to hand to Apple.


turboderp retweeted

We just added Tensor Parallelism to TabbyAPI!
Huge thanks to @turboderp_ and testers who made this possible.
Now, enjoy the clip diving into the origins of Exllama.
Wanna see TabbyAPI built live? Follow me on twitch: kingbri1st
turboderp retweeted
1000 stars on tabbyAPI. Holy crap.
Huge thanks to @turboderp and everyone who contributed!

turboderp retweeted
TabbyAPI now supports ExllamaV3 with automatic backend detection! 🎉
Please note that exl3 is being actively worked on and mileage may vary compared to exl2
Thanks to @turboderp_ and all contributors for making this a reality.

I made a thing.
github.com/turboderp-org/exl…

turboderp retweeted
Supply chain alert!
Don't use the comfyUI Impact pack! Its dependency ultralytics has been compromised on pypi.
Thanks Shinon for letting me know in Discord.
github.com/ultralytics/ultra…
