

in love w generating pixels
Bangalore
Joined July 2024
- Tweets3.4K
- Following134
- Followers1.1K
- Likes3.9K






Pinned Tweet
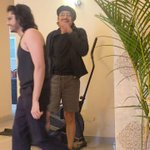
this is apparently what registering a company looks like
3 of us have been building from this flat in bangalore
today we finally had to register the thing
i want to remember this day exactly like this

2
9
600

kunal Lodha retweeted

The most consistent mistake I see young would-be founders make is to care too much about investors' opinions and not enough about users' opinions. They've been trained their wholes lives to seek out and please the gatekeepers. But this is where gatekeepers stop mattering.
genuinely trying to understand this one
so many gen ai apps are offering seedance 2.5 way cheaper than bytedance's own api. and from what i've seen talking to bytedance directly, there's no real discount even at high volume
so how does the math work? are people burning vc money to win users, or getting some deal i don't know about?
not calling anyone out, i actually want to learn how this works
2
124
glimpse from elorian is a good example of why routing should live inside the harness
it reasons over the image and video itself instead of turning it into text first, and it's trained to use its own tools (code, image transforms, watching video) and spawn subagents that pass visual stuff back and forth
so routing becomes one more harness piece, next to context, tools and verification:
1. tag each step as visual (look, count, track, check the frame) or language (plan, write, decide)
2. send visual steps to the specialist, even planning when it depends on what's on screen. keep astra or opus for long text and code
3. models aren't fungible, the specialist needs its own prompt and tool shape
4. eval per step and end to end, per step tells you which model broke it, end to end catches what got lost in the handoff
the harness doesn't pick one model anymore. it picks per step

85
kunal Lodha retweeted

Be profitable and run your company with maximal agentic loops
You don’t need to sell more of your co anymore
$10M profit per year reinvested is like an annual Series A no dilution
The best startups do this now. No whinging about the Series A/B crunch.
You don’t need saving.

Series A and Series B are the hardest rounds for founders today.
Founders launch a vertical AI SaaS company. They reach $1M-$3M ARR in 2 years or $5M-$10M in 3-4 years.
They go out to market with their 1x-3x growth. Almost no interest from investors.
If it's not the right category or a deep, long-term conviction bet, most investors stay away.
Founders are stuck with large pref stacks and a market that doesn't value this growth. They are neither sustainable (at their current burn) nor venture-fundable (without growth).
The exit options (if available) don't leave much for the team. In most cases, founders are required to join the acquiring company (but they aren't interested).
I talk to many founders who have been misadvised, and they keep grinding without making progress.
The Series A or B that didn't happen won't magically happen in 1 year with a little more progress. If the market moves much faster than your company progresses, you will always be behind. If you are told today to hit some metrics and come back, the market will have already moved by the time you return.
kunal Lodha retweeted

Dusting off this tweet from April because this gap in shared understanding of LLM capability is *widening*. It's now less "two groups of people speaking past each other" and more a sharp funnel.
- Napkin math somewhere around 6B people (~75% of the population) have barely come in contact with LLMs at all.
- Around 1-2B (~20%) are casual and infrequent users of free-tier ChatGPT-like products. This group sees derpy chatbots and treats them a bit like a better Google search, a writing aid, or etc. Maybe an agent tries to book you a flight. I have non-tech friends who (reasonably, imo) say they have not much use for it at all. Even many professionals outside of math&code are in this tier. For example, execs and many other functions spend a lot of their time talking to other people, so while they understand what is happening intellectually, it is still second-hand and a bit abstract.
- Now we get to professional use of frontier-grade LLMs in math&code. Somewhere around 20M people (0.2%) see first-hand that large, complex projects that used to take them weeks/months can now be completed by agents with a prompt. Building apps, copying apps, translating apps, decompiling apps from binaries... This has all happened very quickly and recently - less than 1 year ago, I was writing code manually by hand, typing memorized computer code commands into a code editor character by character, occasionally pressing Tab to autocomplete a little chunk of code.
- And finally we get to the ~5,000 people (~0.00006%) with access to frontier-grade systems internally. The external world has seen the preview. It looks like swarms of thousands of agents collaborating over weeks on software mega projects: minting zero days, running cyber attacks and defenses at machine speeds, discovering new science, advancing the frontier of mathematics. Things that would have taken top professionals in the industry years of work. Meanwhile, human review and comprehension are starting to fall behind. For example, people are still involved in the "archeology" of the OpenAI-HF incident from many months ago. Mathematicians may be poring over the 722 manuscripts on frontier mathematics for a while.
The funnel is driven by a combination of factors:
1. The impact scales with ambition, problem size, and horizon. A question with a paragraph answer barely stresses the system. You need a reservoir of big, difficult problems that you really care about. This aspect drives the consumer / professional dimension of the funnel.
2. The jaggedness of the system (which I have written about a lot separately). Capability peaks in domains that are digital, verifiable and economically valuable. This is because LLM capability emerges from reinforcement learning on verifiable rewards on a curated environment mixture driven by revenue potential. This aspect primarily drives the area (e.g. math&code) dimension of the funnel.
3. Access. Free-tier, paid-tier, internal.
So this is the weirdness of the moment. The general public has mostly not interacted with these systems. When they have, it looks like a derpy chatbot. The majority of professionals still see only a modest uplift. And a small sliver of professionals are experiencing the vertigo of the curve going vertical. And it is all happening at the same time.

Judging by my tl there is a growing gap in understanding of AI capability.
The first issue I think is around recency and tier of use. I think a lot of people tried the free tier of ChatGPT somewhere last year and allowed it to inform their views on AI a little too much. This is a group of reactions laughing at various quirks of the models, hallucinations, etc. Yes I also saw the viral videos of OpenAI's Advanced Voice mode fumbling simple queries like "should I drive or walk to the carwash". The thing is that these free and old/deprecated models don't reflect the capability in the latest round of state of the art agentic models of this year, especially OpenAI Codex and Claude Code.
But that brings me to the second issue. Even if people paid $200/month to use the state of the art models, a lot of the capabilities are relatively "peaky" in highly technical areas. Typical queries around search, writing, advice, etc. are *not* the domain that has made the most noticeable and dramatic strides in capability. Partly, this is due to the technical details of reinforcement learning and its use of verifiable rewards. But partly, it's also because these use cases are not sufficiently prioritized by the companies in their hillclimbing because they don't lead to as much $$$ value. The goldmines are elsewhere, and the focus comes along.
So that brings me to the second group of people, who *both* 1) pay for and use the state of the art frontier agentic models (OpenAI Codex / Claude Code) and 2) do so professionally in technical domains like programming, math and research. This group of people is subject to the highest amount of "AI Psychosis" because the recent improvements in these domains as of this year have been nothing short of staggering. When you hand a computer terminal to one of these models, you can now watch them melt programming problems that you'd normally expect to take days/weeks of work. It's this second group of people that assigns a much greater gravity to the capabilities, their slope, and various cyber-related repercussions.
TLDR the people in these two groups are speaking past each other. It really is simultaneously the case that OpenAI's free and I think slightly orphaned (?) "Advanced Voice Mode" will fumble the dumbest questions in your Instagram's reels and *at the same time*, OpenAI's highest-tier and paid Codex model will go off for 1 hour to coherently restructure an entire code base, or find and exploit vulnerabilities in computer systems. This part really works and has made dramatic strides because 2 properties: 1) these domains offer explicit reward functions that are verifiable meaning they are easily amenable to reinforcement learning training (e.g. unit tests passed yes or no, in contrast to writing, which is much harder to explicitly judge), but also 2) they are a lot more valuable in b2b settings, meaning that the biggest fraction of the team is focused on improving them. So here we are.
kunal Lodha retweeted
It's great to have competitors who are motivated by money. If they're any good, they eventually get it, and then they stop working. And if they aren't good, they aren't good.
kunal Lodha retweeted
The rate of progress in the labs is accelerating
The rate of adoption of that progress in society is not
It’s going to go both very fast on one end and it will feel slower than ever to those who understand AI because society has natural brakes
Fast takeoff with slow uptake

ok so jean phil isn’t even a real guy and he’s still pulling millions of views and everyone’s like the internet is dead
i got annoyed and made one today
mushroom hair, teddy bear in the suit pocket
gonna post him for 15 days and see if a new one can still get seen or not
ig: cosmo_pettibone
1
384

ai skit videos doing millions of views but no conversion
as a founder, i feel this.
although i haven’t experienced it myself yet.
but what’s the truth?
76
if this works
then i think you need Chromatic
> add Pinterest plugin
> use ref character to build a new character
> make a new video 3 times a day
all in one canvas
if you wanna try Chromatic - lmk

dead internet theory is real.
you can actually create an AI character and get 200k followers in 1 week.
please don’t buy a $299 course.
> create a realistic character sheet
> swap your character into viral videos
if you’re skeptical, i’m gonna recreate these videos with people who comment.


64
kunal Lodha retweeted
A CS undergrad asked me where he could have most effect in the AI age. I said probably at either extreme: either close to the technology, actually making LLMs, or close to the customer, using AI to give them exactly what they want. Or maybe both if you can stretch that far.

idk why people freak out so hard about AI images
like if the photo still looks like the real product who cares how you made it
keep hating - in a few months you won't even be able to tell if it's ai or not


90

going to rent a gpu and run this.

Open weights. Shared progress. MiniMax H3 is moving fast.
We built H3 for video generation with native stereo audio and multimodal reference control. The open-source community is making that capability faster, more accessible, and easier to build on.
Recent highlights:
• FastH3 — FastVideo, Nuva Lab and NVIDIA: 4-step distillation, now running on DGX Spark and Apple Silicon.
• Sol-H3 — NVIDIA’s SANA team: 15 seconds of 768p video + audio in 6.6 seconds on 8×B300, in the team’s warm-inference benchmark.*
• VDN — Haocheng Xi and the OpenVDN team: rethinking attention for faster H3 inference, with weights, training and inference code released.
• PDD — NVIDIA’s distillation method, brought to H3 by Alibaba PAI as 8-step Acc-LoRAs, now supported in ComfyUI.
• LightX2V — 4- and 8-step Turbo LoRAs, with workflows for text, image and reference-conditioned video + audio.
Behind every release are people training, optimizing, quantizing, testing and sharing. Special thanks to:
@haoailab @nuvalab @NVIDIAAI @xieenze_jr @HaochengXiUCB @ArashVahdat @julberner @LightX2V @ComfyUI
And to the individual contributors pushing the work forward:
@haozhangml @cxlcl1 @lawrence_cjs @yitongli165665 @haopengl33 @songhan_mit @shanasaimoe
Thank you for building with H3 and helping make it faster, more accessible, and more useful for the community. Powerful models go further when we build together. Keep pushing H3. Excited to see what comes next. 🚀
Explore the ecosystem: github.com/MiniMax-AI/awesom…


95