




Ilia Kulikov retweeted

i hate ai slop.
i feel like everyone hates it, but what i hate even more than slop (and can't do) is writing texts by hand, so what do i do? rlaif a model on non-sloppy texts!
it's a qwen 27b, reward from a judge calibrated on human vs non-ai texts, with rubrics and quality scores. it didn't drop on terminal bench or the rest, and also i like rl'ing llms.
so basically it's a qwen3.8 that writes shorter, annoys less, and can pass slop-checking systems: huggingface.co/AlexWortega/Q…
also i uploaded the env to hf with the scores and the texts:
huggingface.co/datasets/rawm…
And also its top4 on eqbench4 by @sam_paech

Ilia Kulikov retweeted

🥥🌪️ Introducing CoCoMix - a LLM pretraining framework that predicts concepts and mixes them into its hidden state to improve next token prediction.
📈 More sample-efficient and outperforms next token prediction, knowledge distillation, and inserting pause tokens.
🔬Boosts interpretability and steerability by analyzing and modifying the predicted concepts.
📝: arxiv.org/abs/2502.08524

We are using fairseq2 for llm post-training research in our team. This release comes with a decent documentation (facebookresearch.github.io/f…) 😅 My favorite feature of the lib is the runtime extension support: one can develop research code without forking out the entire lib repo!

Interested in LLM inference algorithms? Please come and watch our tutorial next week!
cmu-l3.github.io/neurips2024…

Curious about inference-time scaling, the #1 trending topic in LLMs?
Come to our NeurIPS tutorial: Beyond Decoding: Meta-Generation Algorithms for LLMs (Tue. @ 1:30)!
cmu-l3.github.io/neurips2024…


🚨new research!
Probability of short sequences tend to be too high with autoregressive NMT (and beyond). We quantified this tendency and defined the oversmoothing rate. We minimize its upper bound, oversmoothing loss, and present our findings!
w/ Maksim Eremeev and @kchonyc !
1/n

The proposed regularization expands the dynamic range of the prob and rank of eos when it is not supposed to be. We see improvements in translation quality when large beam sizes (up to 1000) are used. But, the gap between performance w/ smaller and larger beam is still there!
2/n
Apparently ancestral sampling yields high quality translations if we sample enough number of times, but how to choose one of them in the end? @BryanEikema shows how to scale utility computations over large hypotheses spaces efficiently! very cool

Check out our latest work on minimum Bayes risk decoding for NMT! We show that MBR is a robust decision rule and sampling-based approximations scale well with more computation. Unlike MAP, more computation always improves translation quality. paper: arxiv.org/abs/2108.04718 1/4

Poster #90 in gather town, I am there *now*!


Ilia Kulikov retweeted

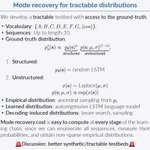
"Mode recovery in neural autoregressive sequence modeling"
We study mismatches between the most probable sequences of each stage of the "learning chain": ground-truth, data-collection, learning, decoding
Led by @uralik1 w/ @kchonyc, SPNLP talk on Friday
arxiv.org/abs/2106.05459


Finally we have studied mode recovery under different learning chain settings and figured that (1) mode recovery cost is non-trivial at every step of the chain and (2) the pattern of mode recovery heavily depends on the property of the ground-truth distribution. (5/6)
We have both live QA and poster on Friday afternoon EST timezone:
talk & poster: bit.ly/3yqWbcb (underline link)
arxiv: arxiv.org/abs/2106.05459
We will be happy to discuss our work with you, please join the session! (6/6)