

Researcher
India
Joined February 2023
- Tweets302
- Following427
- Followers58
- Likes9.3K



DeepSeek just open-sourced an agent you don't prompt. It listens.
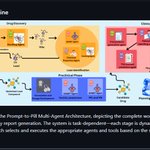
dsh-superagent watches one GitHub repo (and optionally Feishu chats). When an allowed teammate asks for work, it opens a ticket, runs it in its own isolated session and directory, and replies in the same thread, often with a PR.
The design splits a long-lived Router (talks to humans, dispatches) from Worker sessions (do the work). In DeepSeek's synthetic tests, p95 task time was 15.7 min vs 29.5 for a single session with a subagent tool.
Research prototype, MIT, ~11.5k stars in ~2 days.
github.com/deepseek-ai/dsh-s…
#AIAgents #OpenSource #GitHub

The most underrated use of ML in science isn't predicting new materials. It's watching experiments closely enough to explain why they vary.
Perovskite films are famously sensitive to tiny shifts in conditions. A University of Osaka robot logs everything while they form: subsecond color changes, millisecond antisolvent droplets, temperature, humidity, oxygen, VOCs.
SHAP analysis showed two- and three-cation perovskites react very differently to temperature. Acting on the findings, the team tuned droplet speed and hit 24.4% efficiency.
#AI #Robotics #MaterialsScience
Can a training example that looks completely harmless make an LLM easier to jailbreak?
Yes. A new DatologyAI paper finds those examples by reading their gradients, not their text.
Their method, SimpleLoRIF, embedded all 939k Tulu 3 examples in about an hour on 8 H100s. Remove the 20% most aligned with unsafe responses and you get SafeTulu.
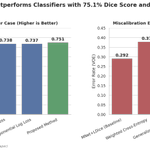
Result: up to 22% lower GCG jailbreak success across Qwen, Llama and Olmo, beating an LLM-as-a-judge filter, with capability mostly intact.
Possible culprits it surfaced: failed Python tool runs and narrative arithmetic.
arxiv.org/abs/2610.37481
#AISafety #LLM #AIResearch

Vansh Bhavsar retweeted

GPT-6 Astra can edit Qwen3.5-0.8B’s weights and raise its MATH-500 from 7.9% to 48.1%, without gradients or retraining.
“Sparks of Weight-Space Programming”
This blog from MIT asks whether LLMs can read and edit neural network weights directly, much like code.
In Qwen, Astra traced repetitive reasoning loops to a direction written by two MLP layers, then edited the weights to suppress it.
With 50 batches of forward-pass feedback, the fix also raised instruction following from 21.0% to 62.3%
Read on alphaXiv: alphaxiv.org/abs/2611.weight…

In 2022, someone picked up a rose-colored rock on a salt plain in Mali's Sahara.
It turned out to be a piece of Mars that formed more than 4.1 billion years ago, making it one of the three oldest Martian meteorites ever found.
Teghaza 001 weighs about 800 g. Its minerals record Mars's crust cooling from magma, then being altered by underground water. One reviewer called it a "Rosetta Stone for Mars."
The NASA JPL-led team narrowed its likely birthplace to 13 sites in the southern highlands.
#Mars #Space #PlanetaryScience
In 2004 NASA launched a telescope built for a 2-year mission. It ran for nearly 22.
Swift caught 2,000+ gamma-ray bursts, studied 1,400+ supernovae and fed ~7,000 papers. It could swing to a new burst in about a minute.
The twist: drag kept pulling its orbit down. A commercial robot, Katalyst's LINK, launched in July to boost it, but comms dropouts and attitude-control problems meant it never grabbed Swift.
Last observation: Oct 20. Now ~275 km up, it's expected to mostly burn up within days.
#Space #NASA #Astronomy
Two weeks ago Google shipped Gemini 4 Argon. Now it's Gemini 4 Carbon, and not everyone gets it first.
Argon → Carbon:
Prompt-injection attack success (Gray Swan): 0.7% → 0.0%
Internal secure-code success: more than 2x
Intro price: unchanged at $2 / $10 per M tokens
Security evals: 88.2% on SEC-bench Pro (finding vulns), 54.8% on ExploitGym, 71.0% on CWE-bench (patching). It also ranks #1 on the Artificial Analysis Intelligence Index (59).
First access: a subset of cyber defenders via the Fairwind Program. Everyone else: "coming soon."
#AI #LLM #CyberSecurity #Gemini

How much does a first-author slot on an IEEE conference paper cost?
$43 to $400, going by ads that paper mills posted openly on Telegram, WhatsApp and Facebook.
A team of research-integrity sleuths logged 4,407 such ads across 200+ channels and matched them to 2,062 published IEEE papers in 366 proceedings (2021–2026).
IEEE has now pulled 1,417 of them in one day. Integrity specialists told Nature it's the largest single bulk retraction by any publisher.
If you cite conference papers, check Xplore for retraction notices.
#ResearchIntegrity #IEEE #PeerReview
My take as an AI researcher: we keep grading LLMs on how well they explain the past. That's the easy part.
Investor's Last Exam tests the hard part. Agents get a frozen, timestamped corpus (3.43M document versions), do 86 buy-side analyst assignments, and their calls are scored against what actually happened next.
GPT-6 Astra tops research quality at 78.9/100, then drops to 52.5 on forecasting.
And on real outcomes, DeepSeek V4.1 Flash ($0.36/task) beat both Astra and Claude Opus 5.5 on forecast ranking and simulated returns.
arxiv.org/abs/2610.38342
#AI #LLM #AIResearch #FinTech

AI-built websites have a look. Hallmark is an open-source skill that tries to stop your coding agent from producing it.
It plugs into Claude Code, Codex, Cursor and OpenCode, deals 3 themes from a catalog of 50, and builds the page around what the visitor came to do.
Then it checks the result in a real browser at 8 screen widths for the tells: a label above every heading, one coloured word in the headline, an email sign-up ending every page. A fresh-context reviewer gets the last word.
MIT, made by Together AI. ~44k stars, ~12k this week (as of Nov 1).
github.com/Nutlope/hallmark
#OpenSource #GitHub #AIAgents #WebDesign

Vansh Bhavsar retweeted

Neuralink deep dive

Full HUGE* If True episode on Neuralink and the future of brain computer interfaces
I toured @neuralink and got a close up view of their new R1 surgical robot, to see the future they and @elonmusk are building and how it is already changing lives...
00:00 What if you put a chip in your brain?
01:02 What does a human brain feel like?
02:17 How does your brain work?
03:58 Can a brain computer interface read your thoughts?
05:19 How do you get a chip into your brain?
08:07 What’s inside Neuralink’s implant?
10:06 How do you build a brain implant?
11:07 How does robot do brain surgery?
12:20 What could you do with a brain chip?
15:05 How are brain computer interfaces already being used today?
16:07 How are brain chips huge if true?
My take: the most useful thing an LLM agent can do with a game isn't play it. It's build the thing that plays it.
A new paper from Nanjing University + Shanghai AI Lab tests exactly that on Hearthstone Battlegrounds.
Six LLM research agents spent 20 days building a full game simulator, then shipped 23 versions of a PPO-trained agent. On the live ladder it climbed from ~6,000 to ~15,000 rating, into the server's top 100.
The kicker: the trained agent gets 91% of play tasks right in 0.03 s. Best frontier LLM: 63%, taking up to 26 s.
arxiv.org/abs/2610.33845
#AI #LLM #ReinforcementLearning #AIResearch

Long-document parsing is still a weak spot for frontier multimodal models. Baidu's new 3B model makes that hard to ignore.
Unlimited OCR 2 (open weights, MIT) parses documents hundreds of pages long in one request. Its trick, SR-SWA, attends to a small fixed set of reference tokens instead of every page, so per-step memory and latency stay nearly flat as the document grows.
On Baidu's new hundred-page benchmark, MarathonDocBench: 77.1 overall. Best other model in their chart: 33.7.
It's their own benchmark, so wait for independent tests. Still, a 3B model doing this is a big deal for document AI.
github.com/baidu/Unlimited-O…
#DocumentAI #OCR #OpenSource

How do you give an aging space station more power? You unroll new solar panels onto it, by hand.
On Oct 29, NASA's Anil Menon and CSA's Joshua Kutryk spent 7 h 11 min outside the ISS installing the 7th roll-out solar array (iROSA), with Menon riding the Canadarm2 robotic arm. It was Kutryk's first spacewalk.
The 8th and final array goes up Nov 5. Together they're expected to lift station power from 160 kW to ~215 kW.
Part of that extra power supports the station's endgame: a safe, controlled deorbit.
#Space #ISS #NASA
GPT-4o mini can hold about 37 rules at once before it starts slipping. A new arXiv paper actually measured it.
The test is simple: a table of word-swap rules ("replace A with B"), each with a checkable answer, and every replacement scored. 2,958 requests, 642,430 trials.
At 95% accuracy the model holds ~37–38 rules. When every word of the text must be replaced, that drops to ~18.
The bigger failure was length. 995 of 2,958 answers lost the text itself (lines dropped or merged), and each doubling of text length multiplied those odds ~11x.
One model so far, but code and data are open.
arxiv.org/abs/2610.36095
#LLM #AIResearch #MachineLearning
What should a coding agent still know after the chat window closes?
JetBrains' answer is ThinkRail, an open-source agentic IDE (Apache 2.0) built around the pi coding agent.
Every task runs in its own git worktree, so several agents work in parallel without touching your checkout. Merge the good branch, delete the rest.
Project intent lives in a graph of SPEC.md files next to the code. The agent reads and maintains them with dedicated tools, so context survives the session.
Bring your own model provider. ~6.3k stars.
github.com/JetBrains/thinkra…
#OpenSource #AIAgents #GitHub #DevTools

Mistral just put the weights of a 1-trillion-parameter model on Hugging Face.
Mistral Large 4 is a granular MoE: ~1T total parameters, 128 routed experts with 4 active per token plus 1 shared, so only ~49B parameters fire per token. 1M-token context, text and images in.
On Artificial Analysis' Coding Agent Index it scores 48%, effectively tied with GLM-5.3, while using 47% fewer tokens per task. Mistral is pitching it for cyber defence you can run on-prem.
The catch: it's a modified-MIT "ecosystem" license, and selling it as a hosted API needs a separate deal with Mistral.
#AI #OpenSource #LLM #MistralAI
Vansh Bhavsar retweeted
Our second product is called Blindsight and it will, as the name suggests, enable even those who are completely blind or have never seen to see.
It is ready from an engineering standpoint. Just waiting on regulatory approval.

Vansh Bhavsar retweeted

🚨 Neuralink just delivered one of its most emotional breakthroughs yet
Terry, diagnosed with ALS in 2024, is now speaking again using only his thoughts.
The implant translates brain signals into words, with Grok Voice restoring his own natural voice.
Watching him hear himself speak again is incredibly powerful.
This is what restoring human connection looks like. Truly life-changing. As found.