
I like taking things from 0 to 1. From nothing to something. Sprinkled with ML when necessary.
Joined March 2011
- Tweets107
- Following130
- Followers98
- Likes233



Pinned Tweet
Unstructured weight #sparsity made practical.
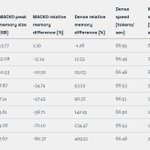
50% unstructured weight sparsity was considered too low for real GPU speed up without specific hardware support (like @cerebras).
With @bozavlado we built MACKO-SpMV - a new matrix format + SpMV kernel to change that. 🧵

if you are at ICML2026, you should definitely check this free tour store. I was suspicious, but it is actually legit! #icml2026 . They are sad that not many people stop by. Still free spots for tours tonight and tomorrow!

Just came to #ICML2026 to present a spotlight paper on how we made the fastest general sparse matrix vector multiplication GPU kernel.
github.com/vlejd/macko_spmv
Come talk: Thu, Jul 9, 2026 • 5:00 PM – 6:45 PM KST
HALL A #2713

Flying to #ICML2026 to present a spotlight paper on how we made the fastest general sparse matrix vector multiplication GPU kernel.
arxiv.org/pdf/2511.13061
Come talk: Thu, Jul 9, 2026 • 5:00 PM – 6:45 PM KST
HALL A #2713
Vladimir Vlejd Macko retweeted

Now, accepted to ICML as a spotlight paper.
I am super proud of my student @vlejd.

Unstructured weight #sparsity made practical.
50% unstructured weight sparsity was considered too low for real GPU speed up without specific hardware support (like @cerebras).
With @bozavlado we built MACKO-SpMV - a new matrix format + SpMV kernel to change that. 🧵
Vladimir Vlejd Macko retweeted

opus 4.5 is really good at GPU programming, but somehow it’s even better at GPU programming jokes (h/t @Si_Boehm)


It is funny how little correct information is there about how to properly benchmark a CUDA kernel. Most papers are wrong, eval libraries are hard to inspect and even this could have a problem because it may include the kernel launch depending on clear_cache implementation

btw, I think BackendBench just uses triton's do_bench function, which uses a very similar timing mechanism to the one exploited here and wouldn't be robust to the same side-stream shenanigans

116


I found "high-priority" "oncall" bug in torch. Achievement unlocked: github.com/pytorch/pytorch/i… Two weeks of insanity were worth it.

Vladimir Vlejd Macko retweeted

We are introducing Quartet, a fully FP4-native training method for Large Language Models, achieving optimal accuracy-efficiency trade-offs on NVIDIA Blackwell GPUs! Quartet can be used to train billion-scale models in FP4 faster than FP8 or FP16, at matching accuracy.
[1/4]

Before #ICLR2025 I was nervous about the size of our poster. Now I am tempted to think outside of the box and push some boundaries. Cool papers btw.


2
108