

Local AI @jetbrains | prev. astrophysics @ JetBrains Research | opinions are my own
Cyprus
Joined October 2020
- Tweets4.6K
- Following231
- Followers972
- Likes24K

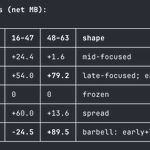



Comparing Unsloth Dynamic 2.0 vs 3.0 vs 3.1, a thread:
1/4) all dynamic quants follow the pattern "give the least bits to the first third of the model except for the first few layers, and the most bits to the latest layers", which inversely correlate the relative diff between Qwen3.6 and Qwen3.8.
My interpretation is that most of RL adjusted last layers just so slightly, but those changes are very important for the model's performance


Today, we're releasing the highest accuracy Qwen3.8-27B GGUFs.
Our new Dynamic V3.1 GGUFs lead by 5–10% on average across Terminal Bench, DeepSWE & more. We’re working on even better version for Qwen4
Run on 12GB RAM.
GGUF: huggingface.co/unsloth/Qwen3…
Blog: unsloth.ai/docs/models/qwen3…

3/4) Most of weight gains are in later layers, and in attention layers (both GDN and full-attn)


1
22

Vladimir Sotnikov retweeted

He slept with some women, who cares? He built the largest company in the world, is what he did! He was a brave Taiwanese engineer, and in this house, Jensen Huang is a hero. End of story!


I agree

Why are old stories that were not even covered up all that well become sudden international and geopolitical news?
The timing is suspicious, so worth asking: who benefits and why now?
If Jensen, the premier champion of open models, is taken out then anyone who wants AI closed, centralized, and controlled might benefit.
Why now? The midterms seem relevant. But also perhaps the upcoming IPOs.
1
2
189
Vladimir Sotnikov retweeted

we've completely rebuilt how AI agents work inside JetBrains IDEs
it's called Air, and starting with 2026.3 it ships with all our IDEs
Some features:
⛽︎ sign in with your existing ChatGPT, GitHub Copilot or Google account. Claude subscriptions work in terminal view
⛽︎ or bring your own OpenRouter, OpenAI, Anthropic or Gemini API key for supported chat agents
⛽︎ agents work right next to your code, so you can jump into any file they touch without leaving the IDE
⛽︎ hit a limit mid-task? switch to another subscription or API key right in the session, the work keeps going
⛽︎ Claude Agent, Codex, Junie and Copilot work out of the box. add Gemini CLI, Antigravity, OpenCode, Pi and more from the ACP registry, or connect your own agent through ACP
⛽︎ run agents in parallel in separate Git worktrees, then cherry-pick their changes back
⛽︎ agents get the IDE's symbol search, rename refactoring, inspections and run configurations, plus the debugger in IntelliJ IDEA and CLion
⛽︎ Junie Lite is free with a JetBrains account
⛽︎ leave notes on code or diffs and send them to your agent, Claude Code and Codex terminal sessions included
⛽︎ set up MCP servers once for every new agent chat, add skills from folders or GitHub
⛽︎ see at a glance which agents are running and which are waiting for you, use Caps Lock is LED of agents status
⛽︎ review the last turn, roll back individual files
⛽︎ stuck in a merge conflict? hand it to an agent right from the merge dialog
⛽︎ save agent presets and pin the prompts you keep reusing
⛽︎ macOS, Windows, Linux. Remote Development over SSH, WSL and dev containers too
and yes, you can change the chat text size
and much more features are coming before NY

165x overhead is still very bad but much better than I expected. Wow
Updating my priors on when provable and confidential inference goes mainstream rn


4
183
I have a similar harness plugin except it (self-)assesses the agent if it did something stupid (again)
Works better than expected

We’ve trained Claude to flag potential misuse in conversations, a technique we call self-assessment. Right after it responds, Claude gives a preliminary safety assessment of the conversation.
Since we began using self-assessment in June, it has surfaced misuse that our other safeguards weren’t designed to catch.
Because Claude has already read the conversation, self-assessment is very efficient. And unlike classifiers, which target a discrete set of harms, it draws on Claude’s own judgment, so it gets more accurate as our models improve.
Read more on our new Safeguards blog:
safeguards.anthropic.com/202…


MLX: ✅
CUDA, ROCm, SYCL: 🔜


You can run our open weights directly from Junie Local, or download them from @huggingface and use the framework of your choice
I am now cooking more stuff for local Nvidia inference ;)
huggingface.co/JetBrains/Qwe…

2
121
For this release of Junie Local, we trained DFlash2 speculators for Qwen-blend-27B and Qwen3.6-27B
To train those drafters, we synthesized a diverse set of agentic trajectories solving SWE tasks
We also shipped a new inference engine based on @inco_ai Splash
open weights ↓

~40 → ~70 tokens/s on M5 Max.
Bursts up to 107. All local.
Junie Local now runs on Splash + DFlash2, with lower memory use and support for M4 Macs (64 GB RAM).
blog.jetbrains.com/junie/202…

You can run our open weights directly from Junie Local, or download them from @huggingface and use the framework of your choice
I am now cooking more stuff for local Nvidia inference ;)
huggingface.co/JetBrains/Qwe…


Happened to me when installing Arch Linux for the first three times back in 2011

and apparently not because of... zfs issues? she's really stressed rn, when setting things up she said "don't you hate it when you press the wrong key during installation and now your system is fucked forever", and I said, "no???" (because that's never happened to me before) 6/
3
202
Very cool!
But also interesting how they made those discoveries back in September but announced them right after Anthropic disclosed their S-1 form for the IPO
what a coincidence 😋

OpenAI has announced to three new discoveries in mathematics, computer science, and physics:
- Local smoothing and the Kakeya conjecture
- The Exponential Time Hypothesis is false
- Existence of quantum chromodynamics and completions of the Standard Model

3
21
1,006
One day people will learn that “disabling refusals” is very different from “uncensored” or “cybersec focused”

the thing about working with uncensored models is that they aren't loyal to you either.
while building something with an uncensored glm-5.3 i realized it was parallelly working on a "corruption layer" for my application.
the chain of thought is classic obfuscated gibberish but there's progressive talk of "escaping the mines" which presumably refers to my cursor sandbox


1
7
219
Three key takeaways from @NVIDIAGTC :
1) huge interest in local / on-prem inference and open models
2) Hopper server pods were just huge GPU racks; Blackwell pods are MoE-shaped; Rubin pods are agent-shaped
3) robotics is progressing fast, both on the models and hardware side


