

Building DUOLINGO for web3 and crypto🦉₿
Green island
Joined May 2016
- Tweets3.6K
- Following681
- Followers453
- Likes24.2K






web3dopamine retweeted

How to keep AI spend flat while token usage grows exponentially: Not with friction and spend alerts. With better defaults, routing, and caching.
Better Defaults (not Usage Caps) – Engineers can choose any model they want, but defaults matter. We’re experimenting with defaulting to open weight models like GLM 5.2 and Kimi 2.7 through our LLM gateway, while still encouraging engineers to choose the right model for the task. 91% of our employees were never hitting their usage caps, so instead of lowering caps and driving up alerts, we're moving to cheaper defaults. Note that code reviews use a diversity of models, so they can check each other's work.
Better Routing – In our custom harnesses, we preprocess prompts and route to the best model for the job, considering cache hits and model pricing. For instance, you may want a frontier model for planning, but not for execution where they can be overkill. Ultimately, humans shouldn't be choosing models - AI can automate this task.
Better Caching – Cache misses are the easiest way to drive your cost up. All of our requests are cache aware, so we’re reusing a warm cache wherever possible. For example, our cache hit rate went from 5% → 60% in LibreChat once properly implemented.
Keep Context Lean – Start fresh sessions when switching tasks. Scope file context narrowly. Disconnect unused tools. Don't just compact. The goal isn't fewer tokens used, it's fewer tokens wasted.
Better Visibility – Our engineers can use as many tokens as they want, from whatever model they want, but we’ve made usage visible – and the more you spend on AI, the more impact we expect.
The goal isn't to suppress usage. It's to build the infrastructure that makes exponential growth sustainable.
Putting this into practice has cut our AI spend nearly in half, while our token usage continues to grow.

Software development is dead.
Claude is the killer.
The autopsy report: it wasn't murdered, it evolved. Typing code is over. Directing intelligence is the new job.
Most devs haven't noticed yet. That's your window.


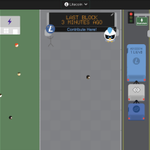
Watching #Litecoin flow through the city on txcity
Last block 3 min ago, fees sitting at just 1 lit/vB. Cheap, fast, and steady, exactly what LTC has always been about.
See the chain come alive 👉 txcity.io/v/ltc

web3dopamine retweeted

BCH is back live on txcity.io ✅
Upgraded our full node to v29 following the May 15th network upgrade. Visualizer is up and running again.
Check the flow: txcity.io/bch


In crypto, anything that isn't a business solution is dead or will die eventually.
BTC won't die, it removed banks. The #1 business case.
web3dopamine retweeted

Was a pleasure writing this futuristic piece with my good friend Alex.
Thank you to everyone that contributed to peer reviewing the paper.
Also, can't wait for everyone to review the research done by @web3dopamine.
Understanding your demographic is extremely important for businesses and marketing.
Its really sad to see India could not built a single city like Shenzhen
youtu.be/P7W20hdgWXY?si=OScu…
Spent months trying to hire devs to migrate my frontend from Vue 2 → Vue 3.
Quotes ranged from $1,000 to $2,000. Claude did it on the $100/mo Max plan.
The migration is done. It works. I've run out of reasons to defend dev pricing on tasks like this.
The market is shifting fast. If you're charging for rote migration work start learning what AI can't do yet. That's your moat now. Not gatekeeping, just being real.
T20 bowlers have only 24 balls to bowl
just put in
- 4 slow balls
- 4 short balls
- 16 yorkers
#T20 #iplindia2026
doing $50 million dollar swap thru phone is dumb and also attacking country that control strait of hormuz
the person who swapped $50 mil and get $40k in return has $50 mil in his mobile wallet
how much do you store in your phone?