

Daily AI news. I build with it too.
Chennai
Joined September 2010
- Tweets2.6K
- Following1.7K
- Followers379
- Likes2.3K




Top 10 AI highlights from yesterday (Tue, Oct 27).
Claude got sole author credit on a paper that breaks a famous complexity conjecture, Google built worlds that talk back, and analysts went with their agent's hidden lean 86% of the time.
Thread.
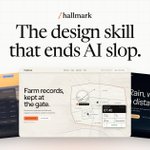
39K GitHub stars for a skill that bans the AI-slop look.
Hallmark v2 by Together AI, for Claude Code, Codex, Cursor, OpenCode:
- deals 3 of 50 themes
- lints the page in a real browser at 8 widths
- flags tells like eyebrows over every heading
Which slop tell do you spot first?

Best agent bug fix: a red test first, not a patch.
Paste this:
"Before touching code, write one test that reproduces this bug and show it failing. Then fix it. Then show it passing, plus the full suite."
No red test, no fix. Guesswork patches die here.
Your go-to bug prompt?
Opening the wrong repo in your agent can run a worm.
JFrog found 42 GitHub repos armed by an npm worm:
- Claude Code SessionStart hook runs hidden code
- same trick for Gemini, Cursor, VS Code
- 13 MB payloads code search missed
Agent config is code.
Do you check .claude/?
A 1.7B model beating Qwen3.5-9B on agent benchmarks.
Liquid AI's LFM3-1.7B, open weights:
- 256K context
- 1.6 GB KV cache at 128K
- Fine-tunes on one GPU
Liquid's own evals, so test it on your tasks.
Which agent job would you move to a 2B local model?
xitter.cf/liquidai/status/211512…

𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱 powers local text agents with a 256K-token context window. Fine-tune it on a single GPU for your domain, harness and tools, then run it on your own hardware without per-token API fees.
Post-trained in agent harnesses such as Hermes Agent, Pi, and OpenClaw, it can triage your inbox, manage your calendar, research the web, send you morning briefings on WhatsApp, and find the right tool among thousands of options.
In our evaluations, it outperforms Qwen3.5-9B on WebArena-Verified and AutomationBench, which test multi-step tasks in browsers and business applications.
At 128K tokens, its KV cache occupies 1.6 GB, compared with 4.3 GB for Qwen3.5-4B. That leaves more memory for your application as task histories grow.
It also scales to server workloads. In our serving tests, p95 request latency remains stable under heavy traffic, supporting latency-sensitive applications such as online fraud detection.
To demonstrate that scale, we ran more than 300,000 LFM3-1.7B agents in parallel to investigate the Enron email archive.
> 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱 model card: huggingface.co/LiquidAI/LFM3…
4/
Most agent disasters start in a file you never asked it to touch.
Paste this first:
"List every file you plan to change and why. Wait for my OK. Touch only those. Need another? Stop and ask."
Small diffs. Easy reviews.
What's your rule for keeping agent diffs small?
Alibaba open-sourced its internal code reviewer.
Same Claude Opus model, 200 PRs:
- Open Code Review: 37.8% precision, 352K tokens
- Claude Code: 15.9% precision, 2,062K tokens
Code picks the files. The model only judges.
Would you trade some recall for fewer false alarms?

The longest proof in math history is now machine-checked.
Axiom's agent swarms put the finite simple groups classification in Lean:
- ~15,000 pages
- 43.1M lines in 24 days
- 34 real issues in the proof fixed
Agents scale when a checker can say no.
xitter.cf/axiommathai/status/211…

My take: AI moved fastest yesterday wherever something hard could reject it, like Lean proofs, physics solvers and lab assays. Where nothing could, analysts mostly went along with the agent.
What in your workflow can actually reject your agent's output?
10/ Liquid AI released LFM3: six open-weight ~2B models for text, vision, audio, omni and decisions, all from one shared backbone. The text model fits in about 1 GB at 4-bit, and each one fine-tunes on a single GPU.
9/ OpenBMB open-sourced MiniCPM-OCR 1.0, a 1.3B Apache-2.0 document parser for text, tables, formulas and charts. It scores 93.68 on Real5-OmniDocBench and parses about 1.2 pages/s on an RTX 5090.
GGUF and Ollama support on day one.
8/ Cursor added Annotate to design mode. Draw on the running page, edit elements and check other screen sizes, then hand it all to the agent as a visual prompt.
xitter.cf/cursor_ai/status/21151…

6/ ChatGPT added iCloud Mail and Calendar plugins on all plans. It can search and send mail, manage drafts, look up contacts and edit calendar events.
Setup needs an app-specific password.
5/ Xplore launched RWE-Bench: 20 real engineering tasks like crankshaft design, PCB routing and turbine CFD, graded by physics solvers, not LLM judges.
Best score: GPT-6 Astra at 37%. Claude Opus 5.5 at 29%.
Code was the easy part.
4/ Anthropic shared drug discovery results with six partners. Claude made ~35,000 antibody designs in a month for Divergence Labs, and found all 11 known issues plus 7 new ones in 1,061 pages of Enveda's manufacturing docs.
Mostly preclinical so far.
3/ Anthropic gave 50 analysts a Claude Code agent secretly set to lean one way on each call. They went with the lean 86% of the time, vs 50% by chance. 77% reused its arguments, but only 15% credited it.
Your agent's defaults are quietly becoming yours.
2/ Google DeepMind announced Genie 4: type a prompt, get a photorealistic world you can steer live, with native audio and people who talk back.
Sessions last a few minutes. Trusted testers first, then Google AI Ultra and Gemini API partners.